@raulbehl@rohitdotmittal From the people I talked to, they made it clear that their old marketing is out of date (Sohu architecture and burning the transformer). There isn’t any recent marketing which mentions this anymore either. All their old marketing on Sohu is deleted
@raulbehl@rohitdotmittal Not sure. Although no where on their website do they state that they are doing the transformer asic thing.
https://t.co/Z3eyotOhjR
Have heard from individuals at the company who have told me this as well.
ICYMI we showcased our 10x faster than real-time video generation demos at TT-Deploy ft. Tenstorrent Galaxy Blackhole in collaboration with @prodialabs .
- 10x faster real-time high-quality video gen
- infinite movie w/ real-time prompting
My current list of "laws" governing computer design
I miss any ?
Rents Rule
Pollacks’s Rule
Amdahls Law
Moores Law
Dennard Scaling
Bitter lesson
Little’s Law
Jevon’s Paradox
Tenstorrent just dropped serious benchmarks on DeepSeek 671B, and they are worth watching.
On decode, they hit 350 tokens per second. That is more than double Fireworks and Google Vertex at 144 tsu, and over 12x faster than Novita at 28 tsu. On prefill (100k sequence length), they clock 4.0 seconds — right in the top tier, behind only Google Vertex at 1.4 seconds while beating everyone else between 6.0 and 8.5 seconds.
The cost story is even bigger. At high throughput, Tenstorrent delivers at $6 per million tokens while NVIDIA GPU setups jump to $30 and keep climbing. They compare Galaxy Blackhole with the GB300 NVL72 rack from NVIDIA, quoting SemiAnalysis benchmarks.
The advantage comes from Tenstorrent’s purpose-built inference architecture. It is engineered from the ground up to keep cost per token low even as throughput scales, unlike general-purpose GPUs that were originally designed for training workloads. For DeepSeek 671B specifically, this translates into dramatically better efficiency on the metrics that matter most to AI companies: speed + real dollar cost at high volume.
This is the structural edge they are betting the entire inference market on, and the real question is whether Tenstorrent could serve inference at scale, provided that they gain traction within the infrastructure industry.
Funny to think robotics was such a hard problem back in the days, when @BostonDynamics had the edge of doing accurate dynamics models of robots’ kinematics + whole-body controllers that compute joint torques in real time that satisfy multiple constraints. It was extremely labour-intensive (and doesn’t scale). Then the 2020s came along and “Learning Agile Robotic Locomotion Skills by Imitating Animal” and “Rapid Locomotion via Reinforcement Learning” made the old ways completely obsolete.
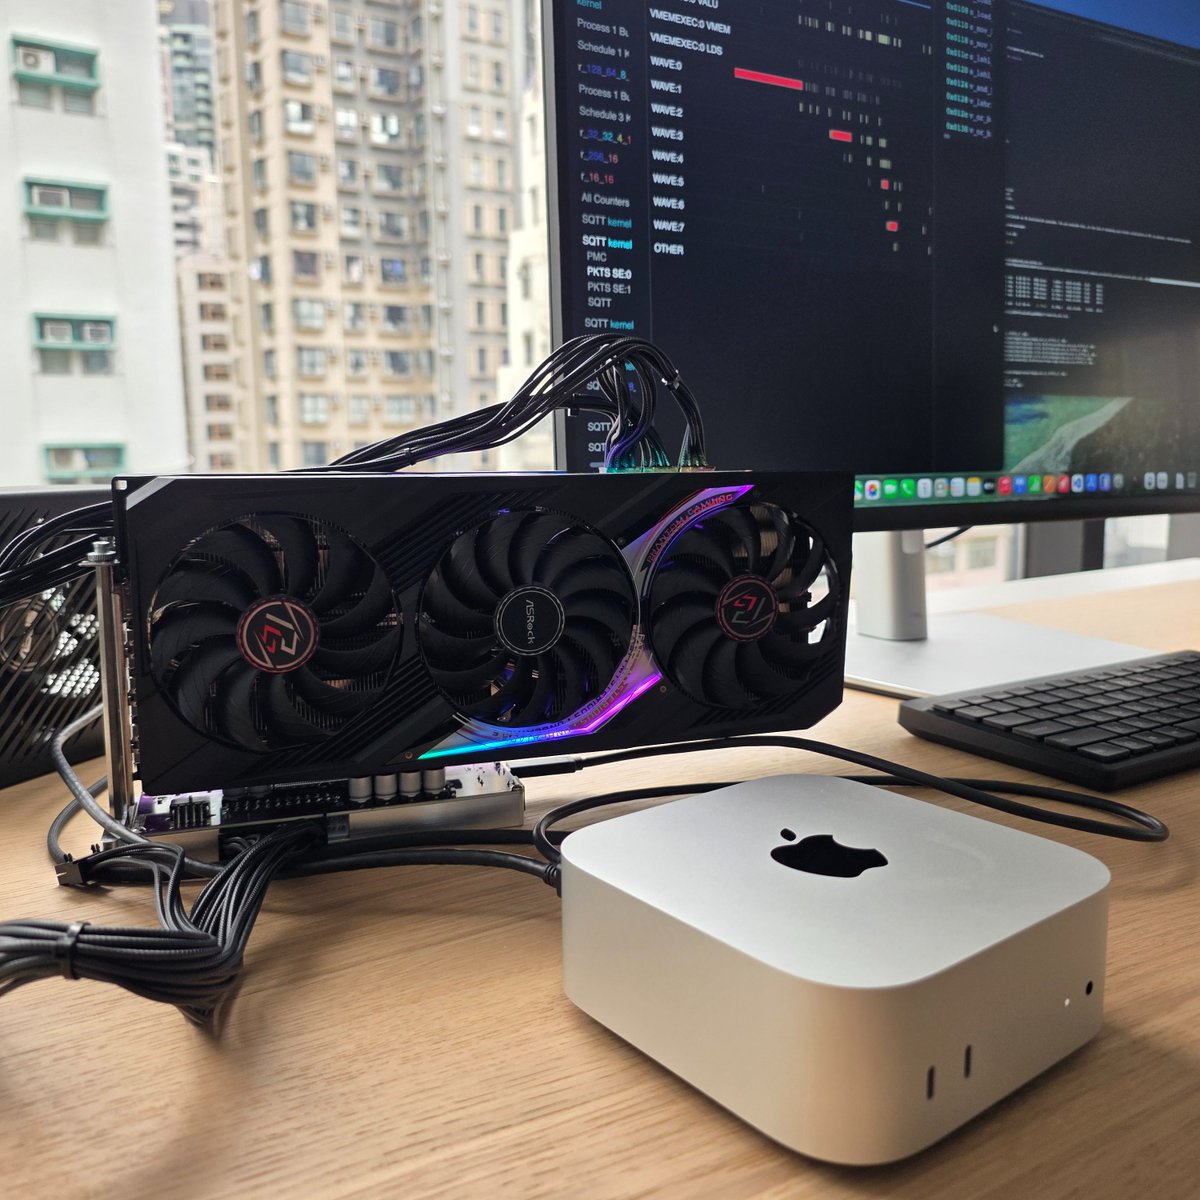
If you have a Thunderbolt or USB4 eGPU and a Mac, today is the day you've been waiting for! Apple finally approved our driver for both AMD and NVIDIA. It's so easy to install now a Qwen could do it, then it can run that Qwen...
First day in SF and already met Garry Tan at Chipotle on his birthday
Told him what I was building and the guy invited me for an interview
SF is truly the greatest city on Earth