Introducing Physical Agent 🥚🦾
We post-trained an open 4B general-purpose agent to control a robot, on four GPUs. Weights are open.
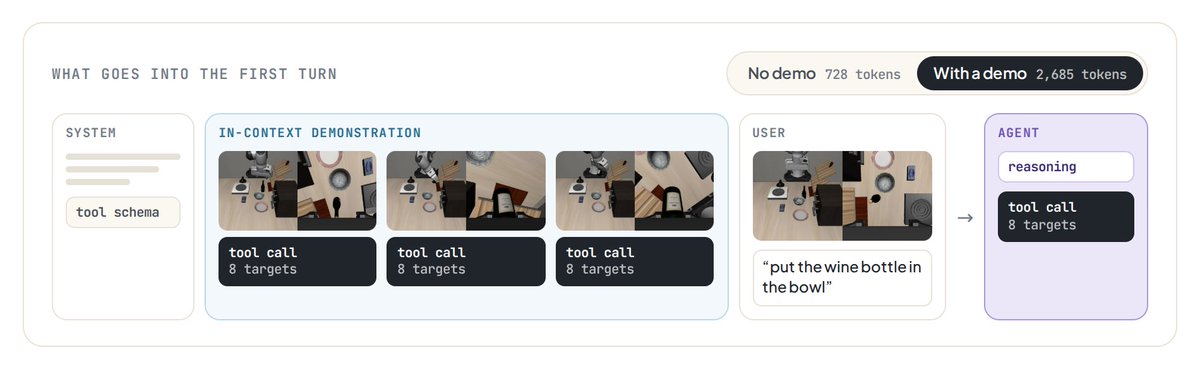
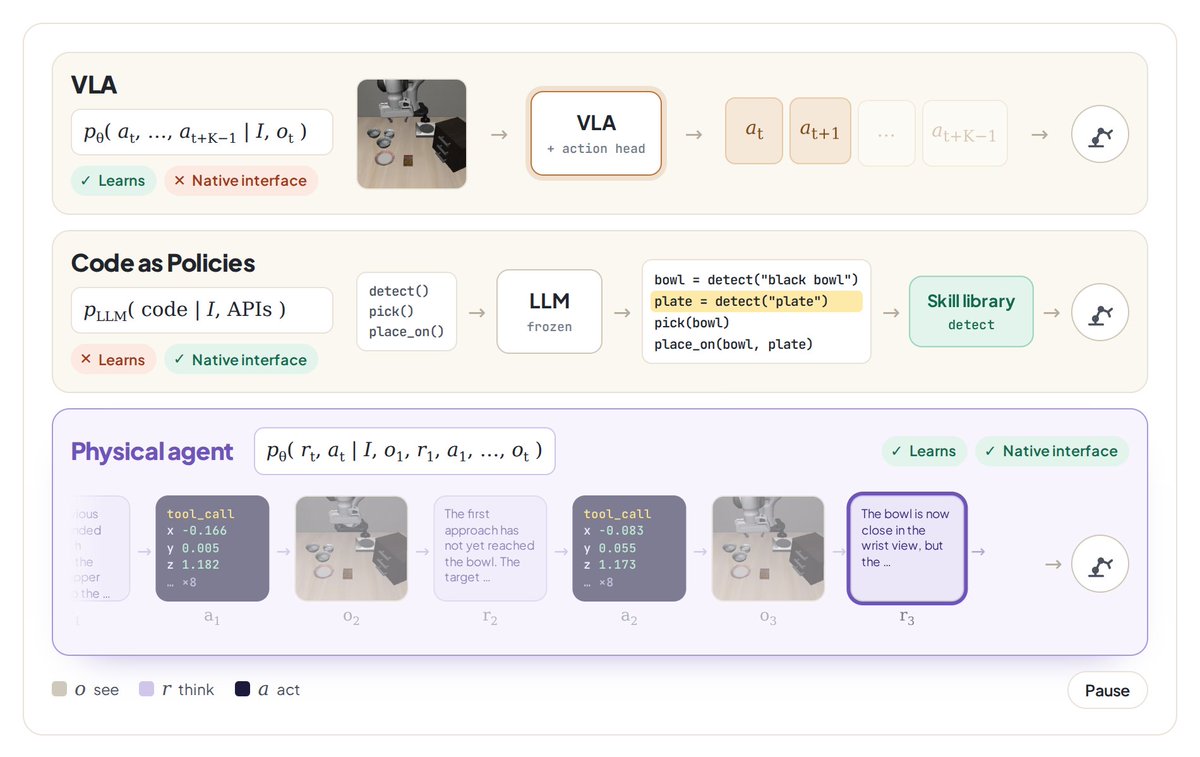
It acts by writing tool calls, not an action head. So it is still a general agent, and it learns new robot tasks from one demo in context.
🧵
Love this. 0 -> 22.5% on unseen scenes with a 4B model is a real result. We're on a very similar path (4B agent, not a vla, but a physical agent, actions as tool calls) and found one demo in the prompt takes task success from 45% to 56% with no weight updates. Curious if in-context demos help yours too.
https://t.co/EGu1XxvCST
@LuccaChiang Thank you Guangqi, preserving those ability that vlm already have is much easier than abandon it and try hard to pick it up in other ways.
Introducing Physical Agent 🥚🦾
We post-trained an open 4B general-purpose agent to control a robot, on four GPUs. Weights are open.
It acts by writing tool calls, not an action head. So it is still a general agent, and it learns new robot tasks from one demo in context.
🧵
@cattttang@substratemag Great read. "Your GPU-hours just became data" is such a good way to put it, and the distillation point is one most takes skip. Fwiw it matches what we've seen: a 4B LLM fine-tuned for manipulation purely in sim, and it kept its reasoning and in-context learning.
@jmtang42@zhuoyang_zhang@jerry_gjx Really nice work, thanks for releasing everything!
We also train robot-use agents (we call them Physical Agents). Ours inherits the LLM's ICL: one demo raises success. Maybe a direction for the community: ICL for better success, then RL.
https://t.co/o3JO5MXKQI
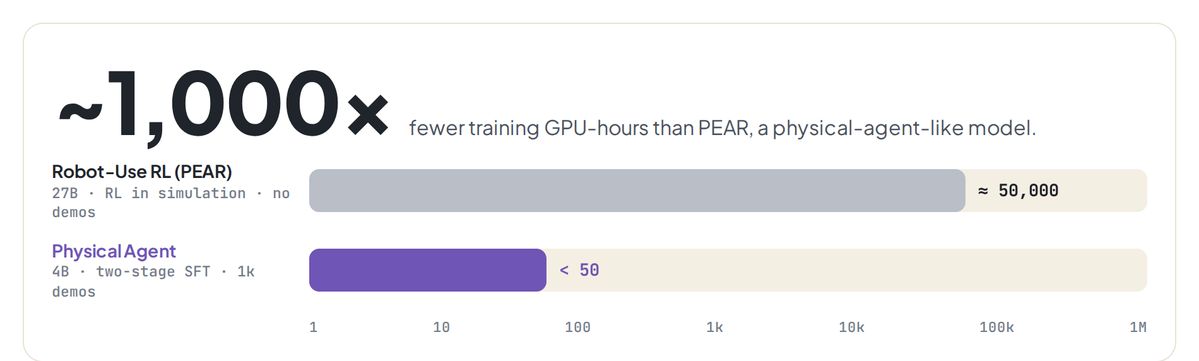
One 4B model, four B200 GPUs, under 50 GPU-hours.
Simulation only for now. Next: real robots and large-scale RL. We are short on GPUs and would love to work with US labs.
Page: https://t.co/o3JO5MYiGg
Weights: https://t.co/fUMKfVDIn0
With @XuJunxiaoxn and Ye Zhao, Georgia Tech
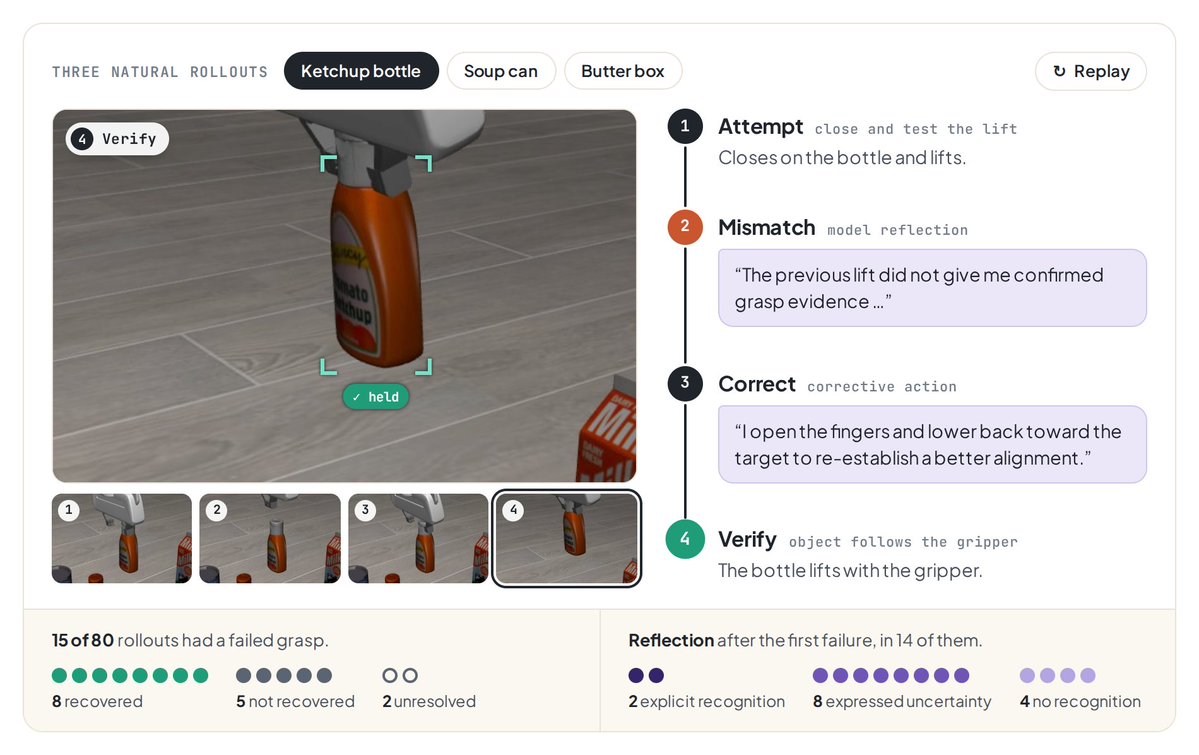
The demonstrations contain only successes.
In natural rollouts the agent still catches some of its own failed grasps: it writes that it cannot confirm the object is held, opens the gripper, and grasps again.
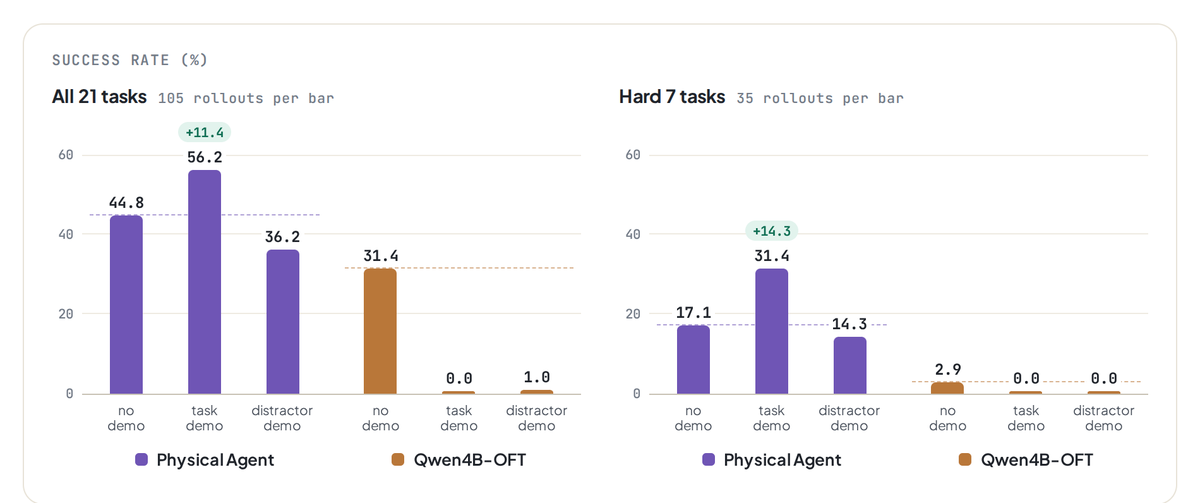
The key result is in-context learning.
Put one robot demonstration in the prompt, with no parameter update:
• 44.8% → 56.2% on 21 perturbed tasks
• 17.1% → 31.4% on the hard ones
Given the same demo, the VLA baseline falls to 0%.
We never trained for this. It is inherited.
It matches a VLA on robot tasks and is still a general agent.
LIBERO: 79.2% vs 80.0% for a VLA baseline from the same model and data. Under task perturbation: 23.3% vs 15.0%.
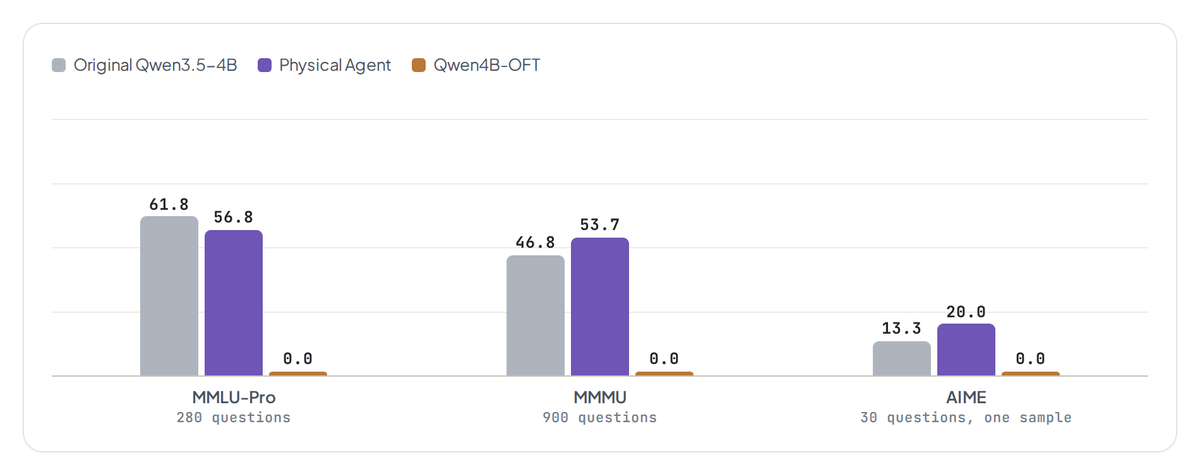
MMLU-Pro 56.8% (61.8% before), MMMU 53.7% (46.8% before). The baseline scores 0 on both.
What is a physical agent?
A general-purpose agent that sees with its own vision, reasons in language, and acts through physical tool calls: native tool calls whose arguments are end-effector targets.
Like a VLA, it learns from robot data. Unlike a VLA, the action stays native.
Find it. Reach it. Grasp it. Easy for us, hard for a humanoid.
Introducing HuG (#CoRL2026): Learning Humanoid Whole-Body Affordance-Aware Grasping with Active Perception.
The robot looks around for a half-hidden object, squats or stretches its whole body to reach it, and grasps. Zero real demos, zero-shot to unseen objects and everyday scenes, from low tables to high shelves.
🌐 https://t.co/XQ8SDmZf97
Excited to share OpenRoboKit, our series of open-source robotics projects! 🤖
- RoboKit for fast, scalable optimization & simulation https://t.co/9KosQmzZP3
Our RoboKit paper has been accepted for a spotlight at #CORL2026
- RetargetingKit for motion transfer & teleoperation https://t.co/fniCD3Uhms
- GraspKit for end-to-end grasping https://t.co/Tikg9Fz94U
Website: https://t.co/fzDLfxoPh5
Check the video (sound on 🎵) for a 16-hour grasping time-lapse in beautiful San Diego, plus a quick look at dexterous retargeting and robot simulation.
We introduce RoboSkills: a minimal, low-cost skillset for agentic robotics 🤖
It supports diverse robotics workflows, such as learning cat’s cradle 🧶 from a human video (Real2Sim) and transferring multi-person motion to characters and humanoids 💃 (Motion Generation).
We also support Auto Research, Agent as Policy, and Agentic Simulation. With suitable tools and workflows, we enable cheaper models to solve complex tasks.
GitHub: https://t.co/pofI0n6xoM
Website: https://t.co/qxzU18vN0R
Watch the video for more examples.
Excited to share RoboSkills 🤖! A minimal, low-cost skillset for Real2Sim, Agent-as-Policy, Agentic Simulation, and much more.
Its lightweight design enables lower overhead, faster iteration, and greater flexibility in agentic robotics development. 🚀
Can we scale robot learning without scaling human labor? 📈
Demonstrations, resets, failure recovery, constant supervision—collecting robot data still takes substantial human effort.
🔑 Three keys let agents take on more of the work:
1. Real2Sim2Real: Agents explore and learn in digital twins, where trial and error is safer and cheaper.
2. Autonomous Recovery: Robots learn to recover from unexpected failures instead of waiting for human resets.
3. Human-on-Demand Learning: Multiple robots run in parallel, and humans step in only when autonomous recovery falls short.
🥑 Recova brings these together to get more robot learning out of every hour of human effort.
https://t.co/Wy7gucGq9r
Joint work with @anjjei, Johan Bjorck, @ZhidingYu, @yin_hongxu, @jankautz, @DrJimFan, @yukez, and @Sifei30488L.
👇 Here's how it works 🧵
No train. No teleop. No pre-built map. ASENA keeps self-evolving ↺ with every task.
With ASENA, we put coding agents in the engineer's seat: they break down tasks, write and execute robot programs, diagnose failures, and turn experience into reusable skills.
The robot doesn't just complete tasks. It builds new capabilities for the next one.
Our G1 robot found its way to the pantry, picked up a Pringles can, and handed it over. No pre-built map. No training for this task.
Behind it is a coding agent, writing, running, and fixing the robot's programs as it goes. And it self-evolves: what works is saved as code for the next task, no retraining needed. This is ASENA.
Joint work with @Isabella__Liu, @edmund_bu, Johan Bjorck, @yin_hongxu, @zhengyiluo, @jankautz, @DrJimFan, @yukez, and @Sifei30488L. 🧵👇