Proud to be part of Palomma’s $14M round, led by COMETA. Congrats to @ciprianoec11 and team on building the AI-native bank for real estate in LatAm. 500+ property managers, 200K+ users and $1.6B+ in annualized rent in just 18 months. At Yango Ventures, we back founders rebuilding financial rails in emerging markets, and Palomma is a standout. Excited for what’s next!
We just raised $14M to build the AI-native bank for real estate in LatAm, starting with rent. 🕊️
Rent is the biggest monthly payment for 50M households across LatAm.
Yet it still runs on co-signers, paperwork, and spreadsheets.
We're changing that...
In just 18 months:
🏢 500+ property managers
🏠 200K+ tenants & landlords
💸 $1.6B+ in annualized rent payments
🇨🇴 #1 rent payments platform in Colombia, the world's 4th most rent-penetrated market
It's time for rent to fly! 🕊️
@ashvardanian and I are building @aal_vc together, so I get to watch this kind of work up close. Today he shared the largest body of open-source work he has ever put out at once.
The v3 release candidate of USearch is public, along with UStore, UCall and UForm. Underneath them are NumKong, StringZilla, ForkUnion and SmashTable. The hardware moved on, and Ash spent three years rebuilding the software to catch up. Code, docs and a 10-minute pitch are in his post below.
This is why AAL VC exists. The people who write C, CUDA and assembly for a living, and who rebuild the same library ten times until it is right, see what infrastructure will be needed years before the market does. That is the same eye we want when we back deeply technical founders in AI, data, cloud and devtools. Building open-source infra and investing in it are the same craft, seen from two sides.
Worth a look if you build anything that touches vectors, strings, databases or GPUs.
The hardware moved on. Most software didn't!
So I spent 3 years and 2 months since the USearch v2 release rebuilding mine. The v3 release candidate is now public - not a stable release yet, but open for anyone to try - and it didn't come alone:
UStore v1 - a multi-modal GPU-accelerated transactional DBMS engine.
UCall v1 - the fastest take I know on secure client-server networking.
UForm v4 - work in progress on drastically more efficient multi-modal AI training pipelines.
All of this now lives on the main branches, as release candidates rather than tagged releases. It is by far the largest body of open-source work I have ever shared at once, and it pulls in the now-public release candidates of the libraries underneath:
NumKong v8 - one of the largest & most opinionated mixed-precision numerics libraries.
StringZilla v6 - with even more Unicode optimizations and GPU kernels.
ForkUnion v4 - with better UX for low-latency parallelism.
SmashTable v1 - reinventing associative containers again 🤦
It's far from complete or fully stable. I also didn't write all of this alone - AI models have helped massively. A few years ago I was afraid it would take drastically more resources to get even to this point, especially given how often I hate the results of my last month's work and redesign everything from scratch for the tenth time, always taking longer than I anticipated.
The attached 10-minute stuck-in-elevator pitch covers the most important new ideas across these projects. The slightly more detailed, but still brief, 2.5-hour lecture is online: https://t.co/z2ydrCy6bE
Code is live on GitHub: https://t.co/3XXGdBFpOn
And most importantly for developers in 2026 - your AI agents can now read all of the docs on a fully redesigned website: https://t.co/UvZENytfu8
We, @aal_vc, wrote the check into @mostik_ai at incorporation. Today: #1 on ARC-AGI. 15 people, 12 PhDs, a Fields medalist — proof that genuinely different models can collaborate without either losing what makes it distinct. Diversity + collaboration, working exactly as it should.
meet @mostik_ai!
what happens when you put 12 PhDs in one room for four months? first place on the ARC-AGI leaderboard, which I can't say much about while the competition is still running. and this, which I can.
everyone's arguing about whether open models will catch up to frontier models. we think it's the wrong question. here's the one we pose: why does a frontier model have to generate your answer at all, when the only thing you need from it is the reasoning?
we do this by enabling models to communicate in latent space. through our protocol, hidden states pass straight from a frontier model into a small one running on your infrastructure -- no text between them, and neither model is fine-tuned. two models from different families, sharing reasoning, both left untouched.
how do we know it works? we tested it on a setup where a 753B model reads the problem, and a 4B edge-class model writes the answer. with this approach, we get results 80% as accurate as the frontier model, but at 20x faster performance.
we're committed to preventing frontier model lock-in and are already partnering with inference providers to accelerate open-weight adoption. we've done this between 15 of us, in four months, 12 PhDs and a Fields medalist, backed by @generalcatalyst
WIRED has the first external account of the company and the work: https://t.co/tP8nItCsDl
full writeup, the setup, and all the numbers: https://t.co/C9NZ5vtV1V
1/
@higgsfield AI just closed $400M at a $5.4B valuation — 4x its $1.3B mark from 8 months ago. @global_dst led, joined by @GoldmanSachs , @intel , @libertyglobal, @tribecap, Smash Capital, @fifthwallvc + more.
2/
ARR reportedly hit $700M in August, up from ~$20M a year ago. Enterprise now drives the majority of revenue vs. <25% in January. 30M+ users, 238 countries.
3/
@alexmashrabov posted something that stuck with us: Kazakhstan just took #1 in the world at the Physics Olympiad — 5/5 golds, one medalist headed to MIT. Higgsfield is built mostly by a Kazakhstan team. Same talent pipeline, same rigor — a generation later, scaling one of the fastest GenAI companies on the planet.
4/
This is our thesis at @aal_vc: back deeply technical founders wherever they build, before the category has a name.
Proud to keep backing builders like this.
12 PhDs and a Fields Medalist in the mountains arguing about latent communication, and it happened to be my birthday 🎂
taking suggestions on how to top that 😂
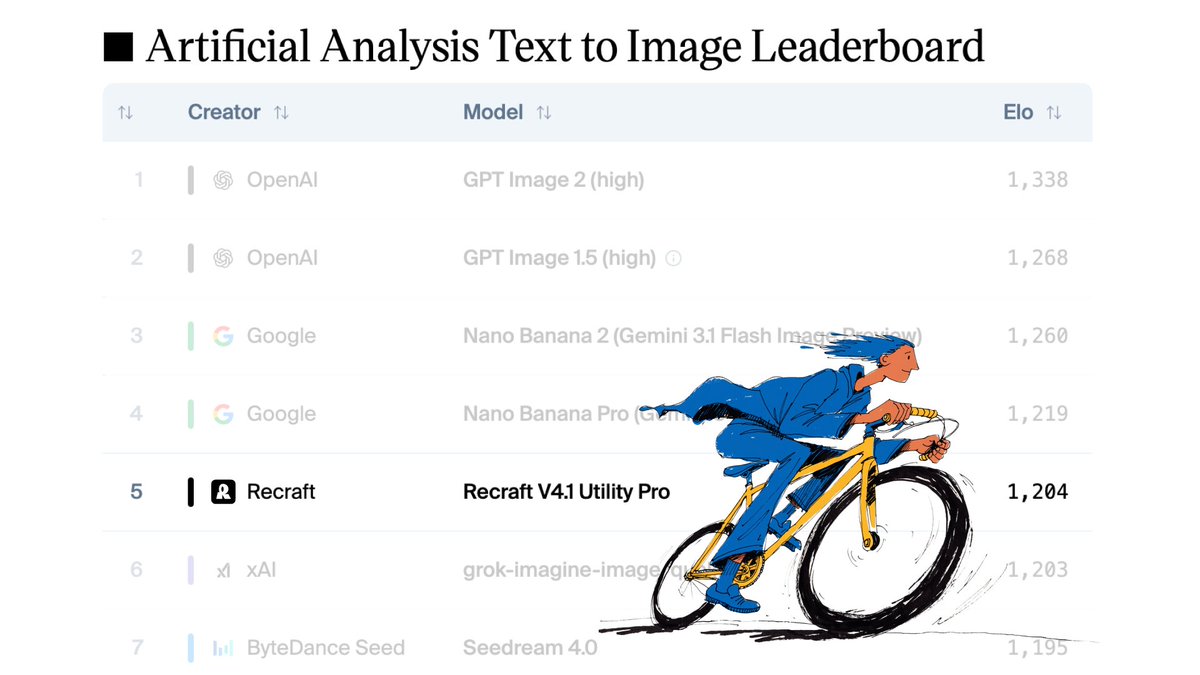
Recraft just hit #1 on public image gen benchmarks — 2 weeks post-launch.
Our @recraftai portfolio company. Founded by the creator of CatBoost. Own foundation model. No API wrappers.
This is exactly what we back at @aal_vc.
My friend and partner at AAL VC, @ashvardanian, already has the code ready before the hardware ships. That's the kind of founder and GP you want ahead of the curve.
Vera nice indeed!
As SpaceX, OpenAI, & Anthropic start getting NVIDIA Vera CPUs, they may soon discover that the only open-source codebase GitHub can find optimized for Vera is my NumKong mixed-precision library 😎
vdotq_f32_mf8 is already there:
https://t.co/l6yaML4jIj
The port-mapping docstring is stale & entirely wrong, but until the hardware arrives, all of us are benchmarking vibes. Will share real numbers once Vera reaches open-source maintainers.
@TheStageAI, an @aal_vc portco, just opened their platform to everyone.
@GarchFather and team built AI compression tech inside Huawei that shipped in millions of phones — now they're making that same power available to every AI developer. The problem they're solving: up to 70% of AI costs are pure GPU infrastructure. Their platform compresses, compiles & deploys models with up to 5x cost reduction. No quality loss. Hours instead of months.
@recraftai already doubled model performance with it. If you're an AI dev or founder tired of brutal inference bills — go try it.
Proud to back xmemory as an @aal_vc portco.
We invested early — before the story was obvious.
Memory is becoming core infrastructure for AI. xmemory is building right at that layer.
We’re excited to share that our team at @xmemory_ai has published our main white paper.
The core idea is simple: without focus, AI systems try to "remember" everything, and that is where they fail. Schema is the best way to teach them focus.
We compared xmemory against major open-source and commercial RAG and hybrid RAG systems, markdown-file memory approaches ("agentic memory"), and memory implementations in customer-facing frontier AI apps. Instead of testing whether systems can recall similar text, we evaluated whether they can store, update, deduplicate, and retrieve facts and relationships reliably.
xmemory achieved 97% accuracy, compared with 87% for the strongest competitor. Our core also outperforms the latest frontier models’ one-shot APIs in extraction tasks, showing that the harness matters just as much as model quality.
We’ve also open-sourced our measurement datasets and a toolkit to generate new ones synthetically.
Huge thanks to the dream team of engineers at xmemory who keep pushing this vision into production. If your company is seeing memory systems fail in real workflows, we’d love to talk.
Thrilled to see @xmemory_ai featured in @BessemerVP’s latest AI Infrastructure Roadmap for 2026.
We’re one of the companies highlighted in Memory, Context, and State Management, alongside seven other strong builders.
What stands out even more than the mention is the broader shift it signals: memory is becoming core infrastructure for production AI.
As AI moves from one-off interactions to persistent, real-world workflows, the systems that win will be the ones that can retain context, manage state, and stay grounded over time.
Proud of what the our team is building, and excited for what comes next.
#AIInfrastructure #Memory #ContextManagement #AgenticAI #EnterpriseAI
Memory is becoming the next critical layer in AI.
Excited to back xmemory — building a precision-first memory layer for AI systems, fixing reliability at the root (the “write path”) instead of patching it later.
$4M pre-seed, strong syndicate — and just getting started.
Proud this is an @aal_vc portfolio company.
Today we’re sharing our first blog post: “Schema as the Core of Reliability.”
Our view is simple:
AI memory breaks down when facts are stored as unstructured text and reconstructed later. That approach can work for thematic recall, but it becomes fragile when systems need to answer exact questions, maintain state, support workflows, and drive automation.
In the piece, we explore why:
- Search can recover context, but memory must support facts
- Graph RAG is a meaningful step forward, but not the endpoint
- Reliable memory needs structure - types, relations, constraints, deduplication, provenance
- Schema is not decoration - it is the contract that makes memory observable, enforceable, and dependable
If AI systems are going to do more than sound coherent - if they are going to make decisions, trigger workflows, and operate over long horizons - memory has to become a governed system of facts.
That is where reliability starts.
Read the full post - link in the first reply.
Some contributions quietly reshape the entire stack.
Huge respect to @ashvardanian for an insane multi-year open-source effort — pushing SIMD, vector search, and numerical computing forward.
Proud to have him as the CTO at @aal_vc.
This is what real infra-level innovation looks like.
My biggest open-source release!
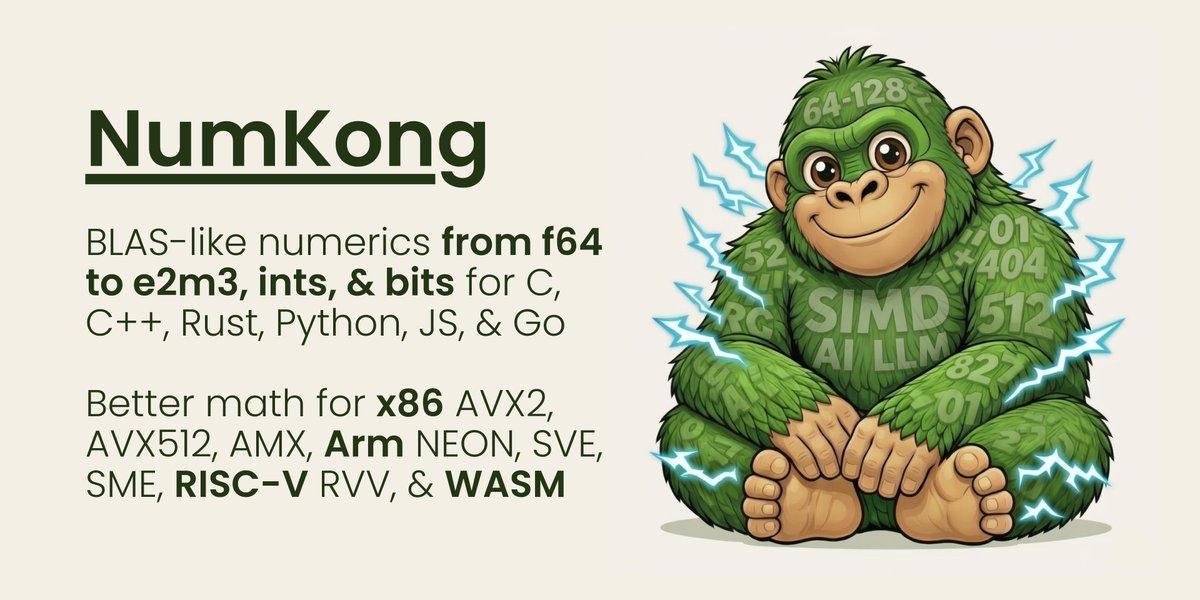
NumKong — 2'000+ SIMD kernels for mixed-precision numerics, from Float6 to Float118.
Started in 2023. Opened the PR in 2024. Finally, merged this week!
RISC-V, Intel AMX & AVX-512, Apple SME & SVE, WASM Relaxed SIMD. 200'000 lines of code in a 5 MB binary. Same scale as OpenBLAS. Available for C 99, C++ 23, Python 3, Rust, Swift, GoLang, & JavaScript.
Int4 dot products via nibble algebra. Ozaki Float64 GEMMs on Float32 tile hardware. 6-bit and 8-bit floats back-ported to 10-year-old CPUs. 5'300x faster Geospatial metrics than GeoPy. 200x faster Kabsch than BioPython. 0 ULP where OpenBLAS hits 56... and a lot more!
pip install numkong
Or pull it from NPM, Crates, GitHub... and let me know what breaks 🤗
Links & highlights ⬇️
The real signal around GTC isn’t just on stage — it’s in rooms like this.
Activeloop convening top builders across AI infra + physical AI.
We invested via @aal_vc with a clear thesis: data infrastructure will define the next decade of AI.
Glad to be part of it.
Jensen just announced the start of the GPU-accelerated database era at #GTC26.
AI runs on GPUs. But your data still runs on CPUs.
That mismatch is breaking the AI stack.
For the last two months, we’ve been busy solving this problem.
Excited to announce Deeplake becoming the GPU Database.
Deeplake brings your database directly onto the GPU, eliminating the CPU <-> GPU bottleneck for AI workloads.
The pendulum has switched.
GPU-native queries are now 10× faster and an order of magnitude cheaper to run.
Last week we even put up a 101 banner in San Francisco.
And this is just the beginning.
We’re planning a huge set of announcements starting this week. Stay tuned.
AI apps are getting complex fast.
Not just prompts — but systems of agents, tools, and workflows.
Observability is becoming the bottleneck.
Laminar is building right at that layer. Proud that @aal_vc participated in the round.
Excited to share that @lmnrai has raised $3M to build open-source observability for long-running AI agents.
Laminar is how companies like @browser_use, @OpenHandsDev, and Rye see what their agents are doing, understand why they fail, and spot patterns across millions of runs.
Cinema Studio 2.0 is officially live!
Proud to have @higgsfield_ai in the AAL VC portfolio. Watching @amashrabov and the team bridge the gap between AI and true filmmaking has been incredible.
Seeing directors like Emmy-winning filmmaker Jason Zada use it to remove the "production tax" on creativity is the ultimate proof of concept.
Today is a big day for us.
We've just released SOUL 2, the next generation of our flagship in-house image model.
This is a product we've been working on for the past six months.
A bit of backstory: when we released the first SOUL, the response was absolutely rewarding. It became the go-to model on our platform, and grew into a daily creative tool for hundreds of thousands of people. It was the first image model in the AI space that didn't have the "AI plasticity". It had taste, and we're happy that creators and brands have adopted it for real commercial work.
To take that further, we've worked closely with creatives, art directors, photographers, stylists, and concept artists to build SOUL 2. They helped define what quality really means.
We're very excited for beauty, fashion, and lifestyle brands to adopt Soul 2 for their ideation and photoshoot workflows. And with SOUL ID, we're opening that door even wider, now, anyone can be a model.
Higgsfield built this to bring high-quality artistic taste to AI and let the two worlds elevate each other.
To celebrate the launch, we're giving up to 5,000 free SOUL 2 generations per user, depending on your plan. Can't wait to see what you create.
What started in 2020 as a simple podcast tool grew into Async — an AI studio connecting ideation -> production > localization in one flow.
A good reminder: big AI platforms often start as small, focused tools. Shrink the distance between imagination and output, and creators win.
📷𝐏𝐨𝐝𝐜𝐚𝐬𝐭𝐥𝐞 𝐢𝐬 𝐧𝐨𝐰 𝐨𝐟𝐟𝐢𝐜𝐢𝐚𝐥𝐥𝐲 𝐀𝐬𝐲𝐧𝐜!
No, we weren’t acquired. No, we’re not going anywhere.
Just getting smarter, faster, and fully AI-powered.
Step inside https://t.co/aI8027qPUa unleash your ideas now!
More details coming soon!
📷𝐏𝐨𝐝𝐜𝐚𝐬𝐭𝐥𝐞 𝐢𝐬 𝐧𝐨𝐰 𝐨𝐟𝐟𝐢𝐜𝐢𝐚𝐥𝐥𝐲 𝐀𝐬𝐲𝐧𝐜!
No, we weren’t acquired. No, we’re not going anywhere.
Just getting smarter, faster, and fully AI-powered.
Step inside https://t.co/aI8027qPUa unleash your ideas now!
More details coming soon!