I've seen a lot of discussion on chess cheating detection in the past year or so -- Hans Niemann incident and whatnot -- and it's led me to think about modelling projects regarding this, given my background in finance, chess variants and AI research. 1/16
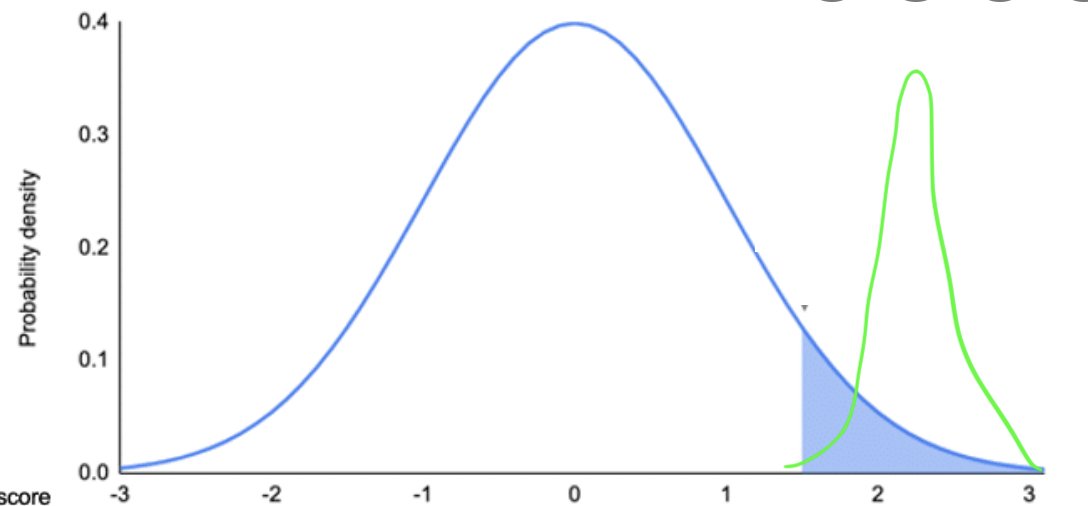
@amanrsanger Retraining on a subset of outputs, even if human curated, seems bad. Imagine blue distribution is what the model outputs, and green is the true desired distribution. Then you just filter down to the shaded blue distribution which is very badly shaped (see your chinchilla tweet)
@filippie509 This explains the success of Tree-based methods, as well as why classifying over bins is better than regressing for IRL problems. For example, Google MetNet Weather prediction:
@sriramk Tiktok's algorithm pushing "status equality" explains Andrew Tate's success of distributing his content across 1000s of accounts, and also why his content gets comparatively very little success on other platforms