BREAKING: The NSA's own director says Mythos broke into almost all of its classified systems in hours.
Per The Economist, Senator Mark Warner, vice chair of the Senate Intelligence Committee, said General Joshua Rudd, who runs the NSA and the Pentagon's Cyber Command, told him this directly.
This came out on June 11, the same day Amazon reportedly found a separate jailbreak in Anthropic's models. Within hours, Trump ordered Anthropic to cut off foreign access to Mythos and Fable.
Anthropic shut both down completely instead.
Now there are two competing stories for why this actually happened.
One says the shutdown was a response to the NSA's own classified systems getting breached in hours.
The other says Anthropic is privately pushing back, calling the jailbreak minor and the shutdown an overreaction to something other AI models can already be tricked into doing.
The NSA was already using Mythos for its own cyber operations, with Anthropic engineers embedded inside the agency. The same tool the agency was actively relying on is the one its own director says broke into almost everything it owns.
Z ai’s GLM-5.2 is the new leading open weights model on the Artificial Analysis Intelligence Index scoring 51 and it sits on the Pareto frontier of Intelligence vs Cost per Task
@Zai_org’s GLM-5.2 is the same size as GLM-5.1 (744B total / 40B active parameters) but scores 11 points higher on the Intelligence Index v4.1, placing ahead of MiniMax-M3 (44) and DeepSeek V4 Pro (max, 44). On the first-party API it is priced in line with GLM-5.1 at $1.4/$4.4/$0.26 per 1M input/output/cache hit tokens
Key results:
➤ GLM-5.2 is the leading open weights model on the Intelligence Index v4.1. At 51, it leads MiniMax-M3 (44), DeepSeek V4 Pro (max, 44) and Kimi K2.6 (43)
➤ Improvements across most evaluations, particularly scientific reasoning: GLM-5.2 gains over GLM-5.1 on most evaluations, led by scientific reasoning on CritPt (+16 points to 21%) and HLE (+12 points to 40%), alongside AA-LCR (+9 points to 71%), tau3 banking (+15 points to 27%) and SciCode (+7 points to 50%). TerminalBench v2.1 also improves (+16 points to 78%) and GPQA Diamond gains 3 points to 89%
➤ Leading open weights model on GDPval-AA v2 and competitive with proprietary models: GLM-5.2 scores 1524 on GDPval-AA v2, ahead of MiniMax-M3 (1418) and DeepSeek V4 Pro (max, 1328). This impressive result places GLM-5.2 in-line with proprietary models including GPT-5.5 (xhigh reasoning). GDPval-AA v2 builds on the original GDPval-AA by baselining Elo to human performance at 1000, introducing a rotating panel of frontier-model judges, and raising the turn limit from 100 to 250 for longer-horizon agent trajectories
➤ GLM-5.2 uses more output tokens per task than other leading open weights models: the model uses 43k output tokens per Intelligence Index task, up from GLM-5.1 (26k) and above MiniMax-M3 (24k), Kimi K2.6 (35k) and DeepSeek V4 Pro (max, 37k)
➤ On the Intelligence vs. Cost per Task Pareto Frontier: GLM-5.2 is on the Pareto frontier of the Intelligence vs Cost per Task chart, with the lowest cost per task among models at its intelligence level. GLM-5.2 costs ~$0.46 per task, compared to GLM-5.1 ($0.25), Kimi K2.6 ($0.31), MiniMax-M3 ($0.18) and DeepSeek V4 Pro (max, $0.05)
Additional Model Details:
➤ License: MIT
➤ Size: 744B total parameters, 40B active parameters, equivalent to GLM-5.1
➤ Context window: 1M tokens, up from 200K on GLM-5.1
➤ Pricing: $1.4/$0.26/$4.4 per 1M input/cache hit/output tokens
➤ Availability: Alongside Z ai's first-party API, GLM-5.2 is available across third-party providers including @DeepInfra, @novita_labs, @nebiusai, @parasailnetwork , @SiliconFlowAI , @gmi_cloud , @Baseten and @FireworksAI_HQ
Exciting news: GLM-5.2 (Max) ranks #2 in Code Arena: Frontend, with +29pt over Claude Opus 4.7 (Thinking) and only behind Fable 5! GLM-5.2 is the best open model vs Kimi-K2.6 and Minimax-M3 by a large margin.
- #2 React and #4 HTML sub-leaderboards
- Ranks as the top model in nearly all sub categories: Brand & Marketing, Reference-Based Design, Data & Analytics, Consumer Product, Gaming, and Simulations.
Congrats @Zai_org for the incredible milestone!
Two days ago the US banned Claude Fable 5.
Yesterday China dropped GLM 5.2.
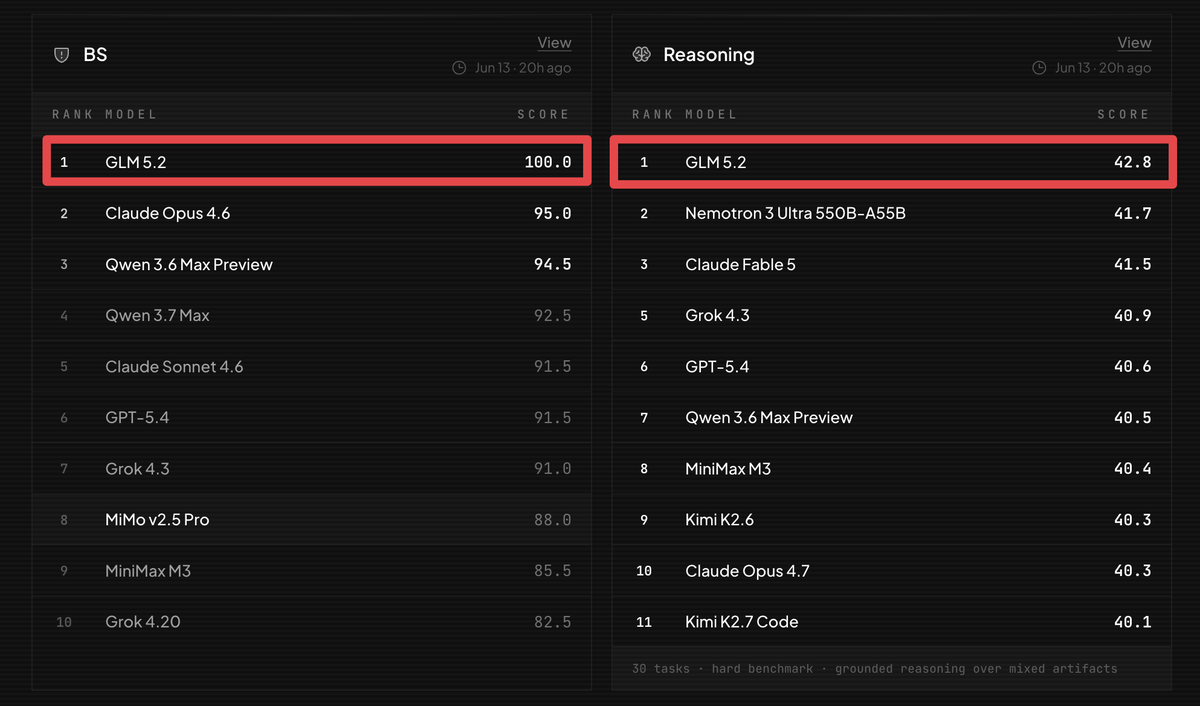
Today GLM 5.2 is #1 on @bridgebench BS at 100.0, and #1 on Reasoning at 42.8, beating Fable 5.
At 1/10th the cost and 300 tokens per second.
You cannot export control your way out of an open source race.
The ban didn't slow China down.
Unban Fable 5.
Claude Fable 5 just showed me the craziest thing Ive seen all day:
A guy gave one single prompt and got a fully playable GTA style game running straight in the browser with graphics that actually feel like GTA 4. Not some low effort mess, but a real city you can drive around in.
Now just think about it.
One person can now create something that used to take a massive team at Rockstar five full years to build. He shows a screenshot, adds a few notes about weapons loot progression and gameplay, and the whole thing starts coming together until its actually fun to play.
Pair that with tools that keep the project moving forward and suddenly the gap between an idea and a working game is disappearing faster than anyone expected.
2027 in gaming is going to be absolutely wild.
One talented person with the right vision can now do what entire studios used to need hundreds of people for.
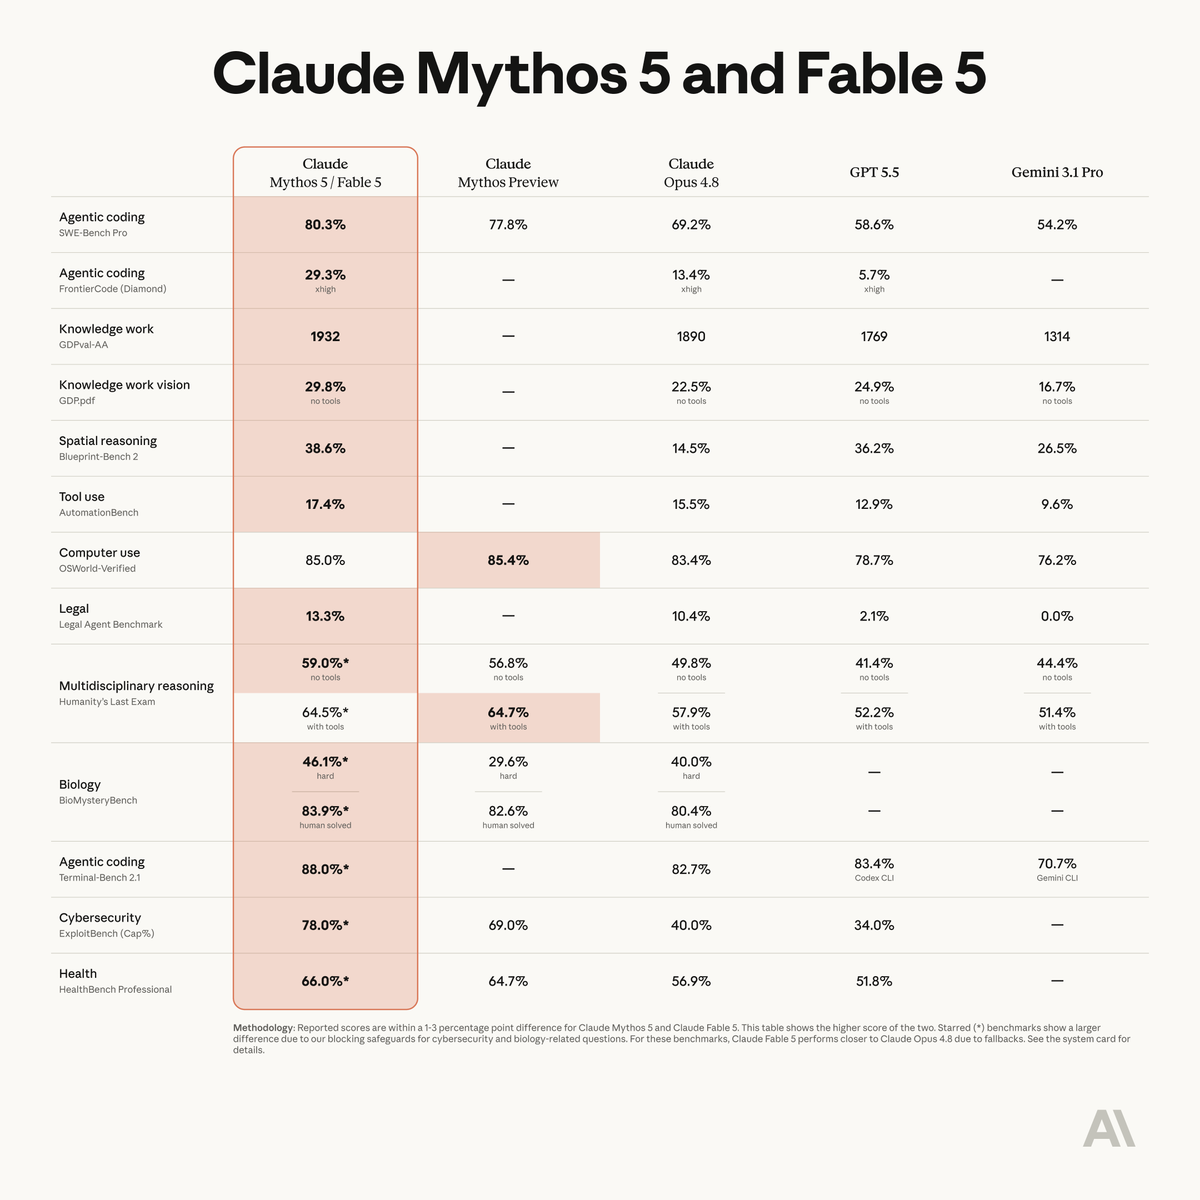
Introducing Claude Fable 5, our most capable public model ever.
Best-in-class for software engineering, scientific research, knowledge work, and vision.
Available today on all paid plans, in Claude Code, on the Claude API, and all major cloud platforms.