Working with @AMD, our models identified up to 14% PPA improvement on flagship GPU IP in less than five months—building on designs AMD’s engineers had already spent years optimizing.
The same approach helped improve Jalapeño, our first custom inference chip, with gains verified on real silicon.
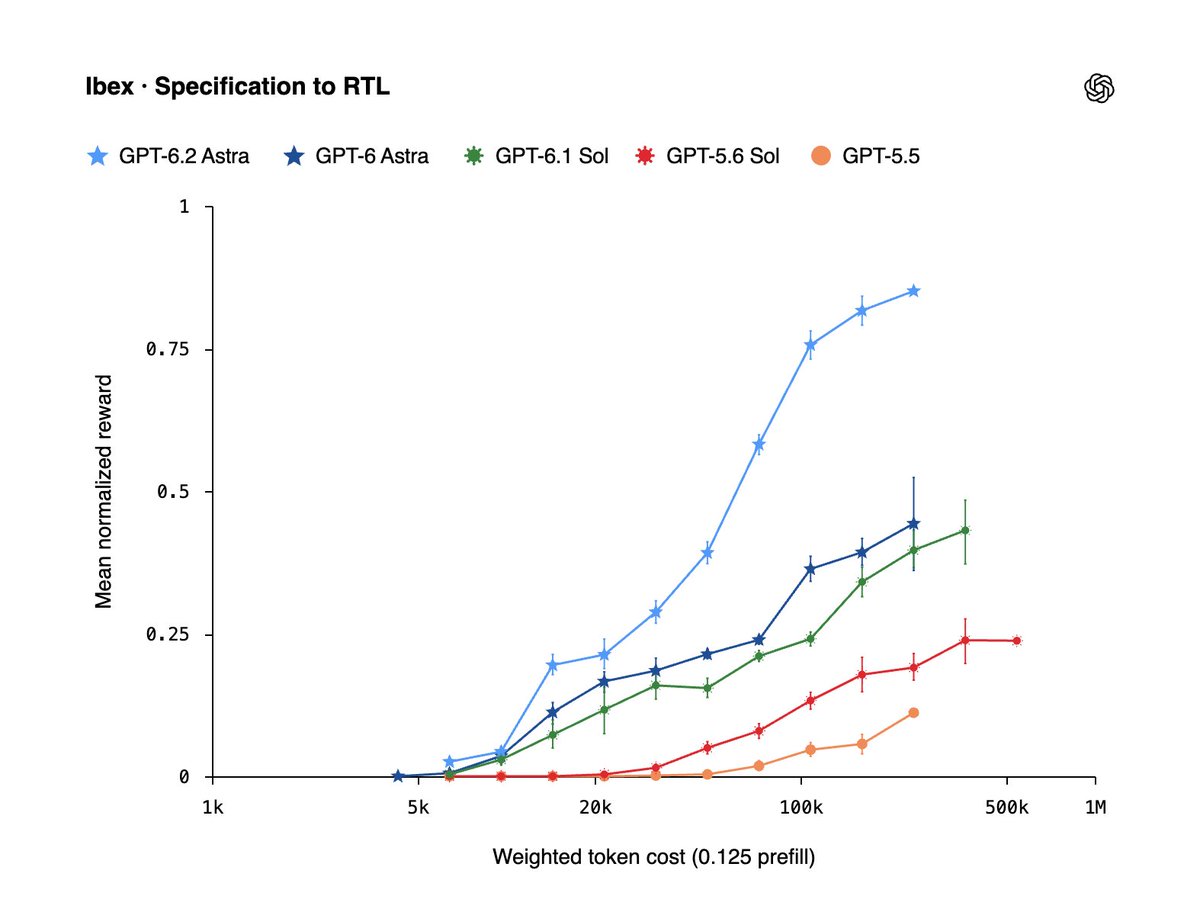
New evaluations also show our models getting better at certain chip design tasks.
We’re sharing these results and how we’re working with @Synopsys to bring our model capabilities and their trusted EDA design and validation tools to more chip designers.
https://t.co/4BNcPIqfIQ
Today, we're announcing a landmark six-year agreement to deliver 457 megawatts of dedicated AI infrastructure for OpenAI, powered by @AMD Instinct™ MI455X GPUs and purpose-built for AMD Helios™ rack-scale systems.
“AI infrastructure is entering a new phase, where the ability to deliver hundreds of megawatts of advanced compute reliably and at speed will separate the companies that can support frontier AI from those that cannot,” said @piotrstomasik, President and Co-Founder of TensorWave. “TensorWave was built to prove that AMD infrastructure could operate at the scale and reliability that the world’s most demanding AI companies require.”
As the first publicly announced neocloud supporting @OpenAI and AMD’s strategic partnership, TensorWave is taking a major step forward in its mission to deliver the performance, capacity, and reliability that frontier AI demands.
457 megawatts over the next six years is just the beginning in a new chapter for TensorWave and AMD-powered AI.
Read more: https://t.co/C4UWrkvGUA
@udayruddarraju
In the last few weeks we paid out over $4M for people to re-create their jobs as RL environments
Today we’re launching Computer Work Val v1.0: 300 tasks across 36 roles with over 200 simulated apps
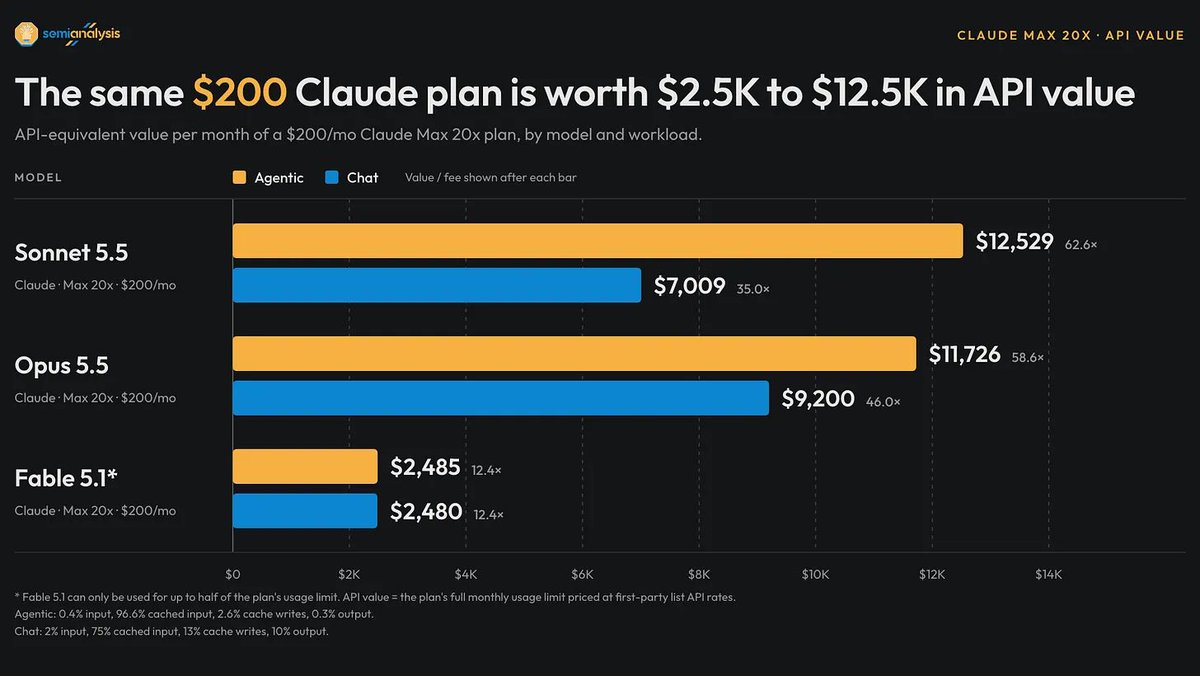
It doesn't make sense to say a subscription plan is worth $ X in isolation.
The way to think about subscriptions is that your monthly payment grants you some numbers of “credits”. Each (model, token type) combo consumes a different amount of credits. Because credit cost ratios can differ dramatically from API price ratios, the “value” of the same plan changes depending on what model and workload you’re running.
Here’s how the API-equivalent value of the same $200/month Claude plan changes depending on the model and workload. (1/6)🧵
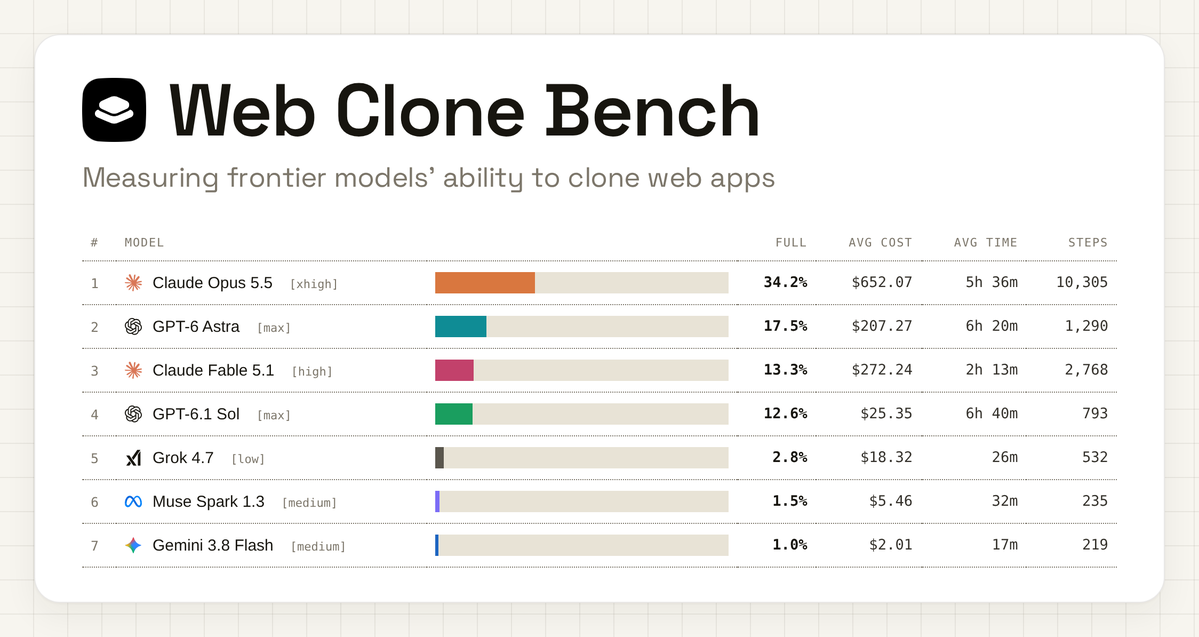
"Claude Opus 5.5 at xhigh effort leads with a full score of 34.2%, nearly twice the next model, GPT-6 Astra at max (17.5%), but it also spends heavily: $652 and about five and a half hours per run. GPT-6.1 Sol reaches 12.6% at max effort for $25 a run."
Today we're launching WebCloneBench: a benchmark which measures a model's ability to explore, copy, build and test various web apps.
For each task, we give the model a reference site from one of Gmail, Google Sheets, Jira, DocuSign, Shopify Admin, Craigslist, Figma, Slack and Zendesk. It is instructed to build a fully feature-complete clone of every part of the application with an 8 hour time limit.
What does it take to back a strategy the rest of the market has dismissed?
In @Forbes, TensorWave President and Co-Founder @piotrstomasik shares the thinking behind our bet on @AMD and why conviction means continually testing the evidence, even if that means you could be proven wrong.
Read his take on when it pays to challenge consensus: https://t.co/xzaWBqiw6T
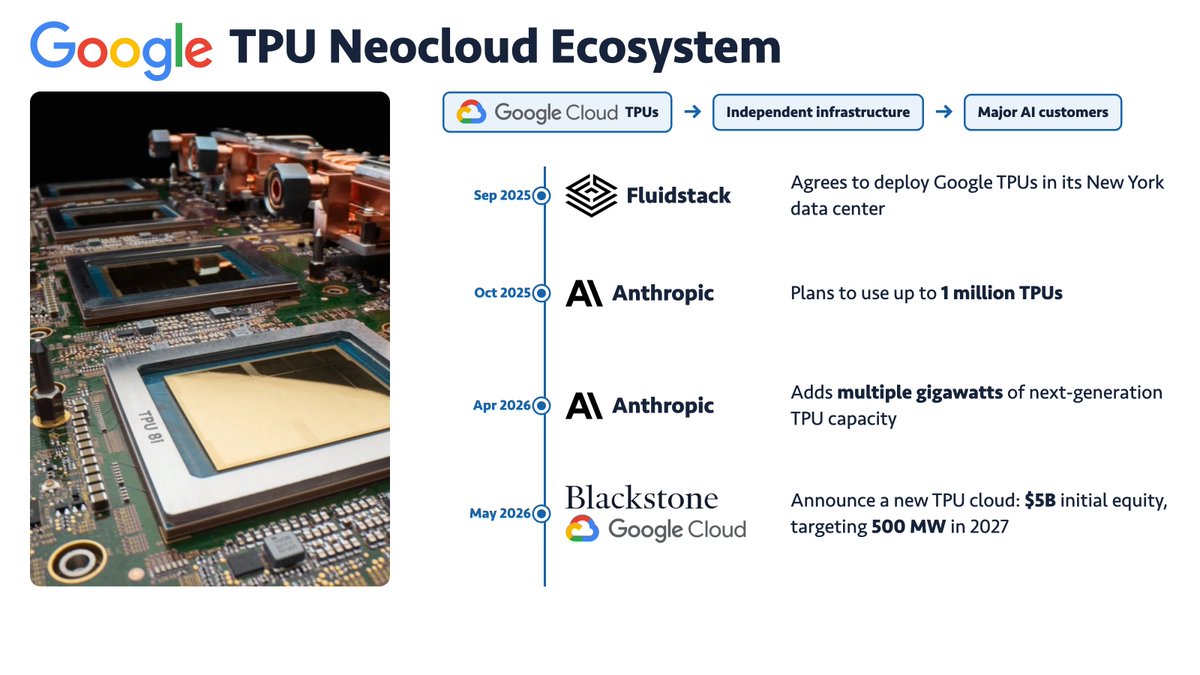
a TPU neocloud ecosystem is starting to happen. nvidia is the center of ai right now, and we see companies like etched try to compete on a chip level. google will compete to create an ecosystem of TPUs to compete with nvidia's neocloud ecosystem.
we don't give TPUs much attention but we already have two signs that they're definitely useful:
- last September, @fluidstack became the first neocloud to deploy google TPUs. no longer in google's own cloud!
- a month later, @AnthropicAI planned to use up to 1 million TPUs. and then this April, it agreed to use multiple gigawatts of next generation of TPUs
then, this May, blackstone agreed to create a new TPU cloud with google. a *5 billion* equity commitment!
"Overall, TensorWave is the leading AMD-exclusive neocloud, providing a comparable (and sometimes better) experience on AMD GPUs than hyperscalers like Oracle and Microsoft." 🚀
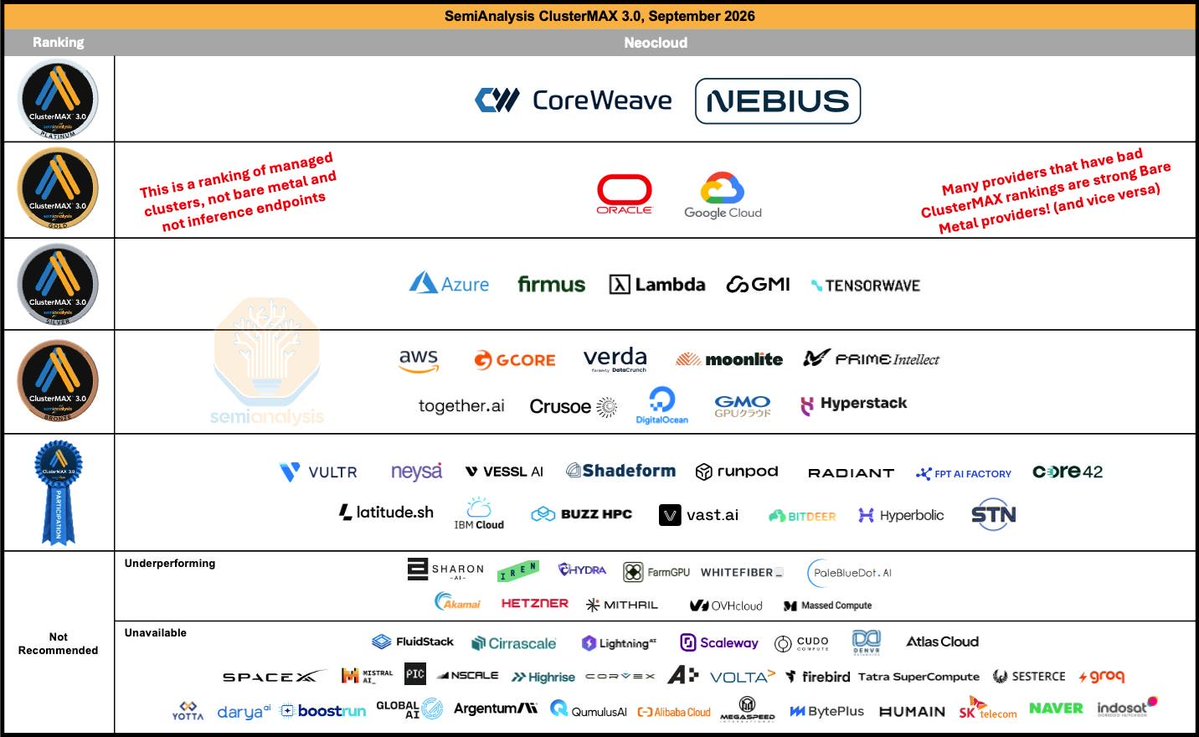
ClusterMAX 3.0 is here!
ClusterMAX 3.0 debuts with a comprehensive review of the neocloud industry, covering 77 providers.
We increase our market view to cover 323 providers, up from 209 in ClusterMAX 2.0, 169 in ClusterMAX 1.0, and 124 in the original AI Neocloud Playbook and Anatomy article.
We have now interviewed well over 200 end users of neoclouds as part of this research.
We update our itemized list of criteria across 10 categories, and update our direct descriptions of our expectations for Slurm, Kubernetes, Standalone Machines, Monitoring Dashboards, and Health Checks. All of this content is live on our website. We encourage providers to use these lists when developing their offerings. We still consider these lists as an amalgamation of our experience interviewing end users, making them representative of the features that end users expect from their cloud providers.
Nebius joins CoreWeave in the Platinum tier. While CoreWeave still sets the technical bar for others to follow, Nebius is now established as a provider that consistently commands a premium pricing over others. Strong business decisions by Nebius have put them in a position to serve an entire class of neolabs at seller’s prices.
Google Cloud joins Oracle in the Gold tier. Azure moves to Silver, Fluidstack moves to Unavailable, and Crusoe drops to Bronze. Lambda, Firmus and TensorWave remain in Silver, while GMI moves up to Silver from Bronze.
Many companies drop from Silver (or Gold) to Bronze or lower. We raise the bar this round as only 19 neoclouds globally achieve a Medallion rating.
We establish a tier between Bronze and Underperforming: the Participation Ribbon tier. 15 providers join this rating, which more accurately describes our opinion that they do the bare minimum to get by.
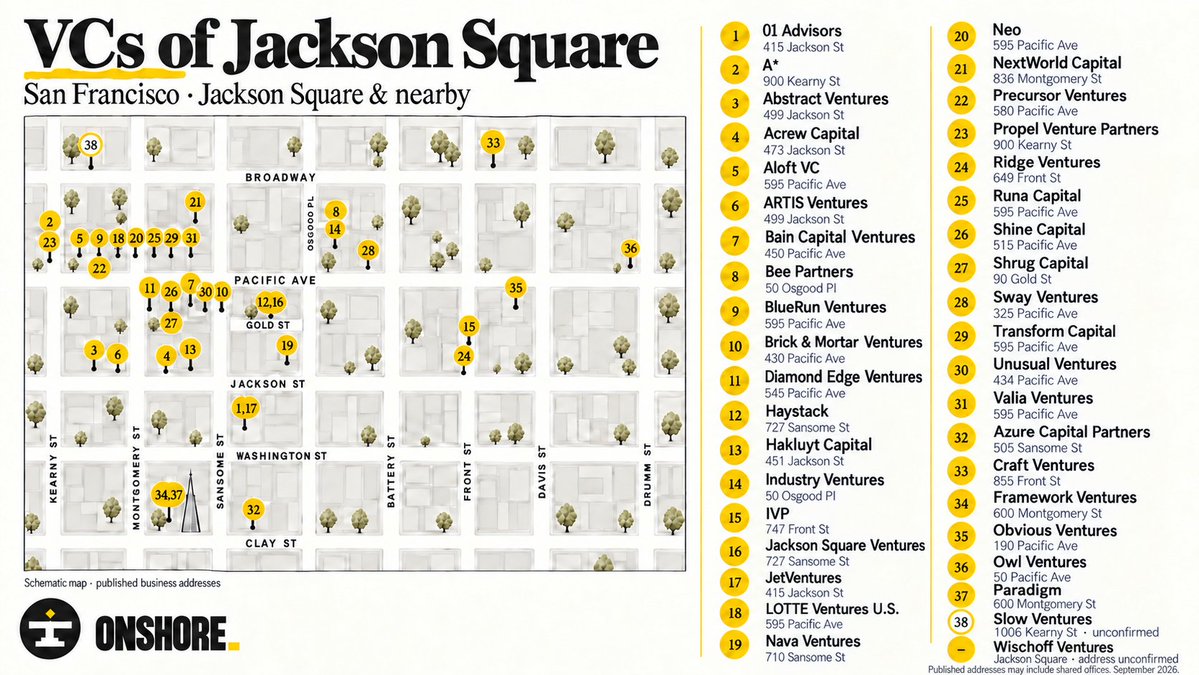
SF VC'S have found a new watering hole in Jackson Square. 37+ firms in about six blocks.
Fun fact: These are 170 year old gold rush brick buildings and @ThriveCapital paid $9M for a firehouse at 451 Pacific.
"At the current stage, the marginal return of engineering the data and environment pipeline substantially exceeds that of algorithmic novelty in post-training." @plato_rl
🚀 Introducing DeepSeek-V4.1-Flash: smarter, faster, more efficient.
🔹 Introducing the smallest model in our new architecture family, with native visual understanding.
🔹 Designed for greater capability, faster inference, higher throughput, and scaling to larger models.
1/6
"A prototype is running off-grid compute, thousands of acres are under contract, and the first campus in New Mexico targets hundreds of megawatts through 2028." @VoxelEnergy