GPT-6 Astra is out. We've been testing the model in early preview on our enterprise complex work eval at Box. It is now the best model we've ever tested on our expanded and hardest test set.
Overall, GPT-6 Astra offers a breakthrough level of capability in coding, analytics, logic, and domain specific knowledge for dealing with complex enterprise knowledge work. In our eval, we use the GPT-6 Astra model in the Box Agent and give it a set of difficult tasks that represent real-world work in various industries. These tasks often will take people hours to execute properly and require deep domain expertise.
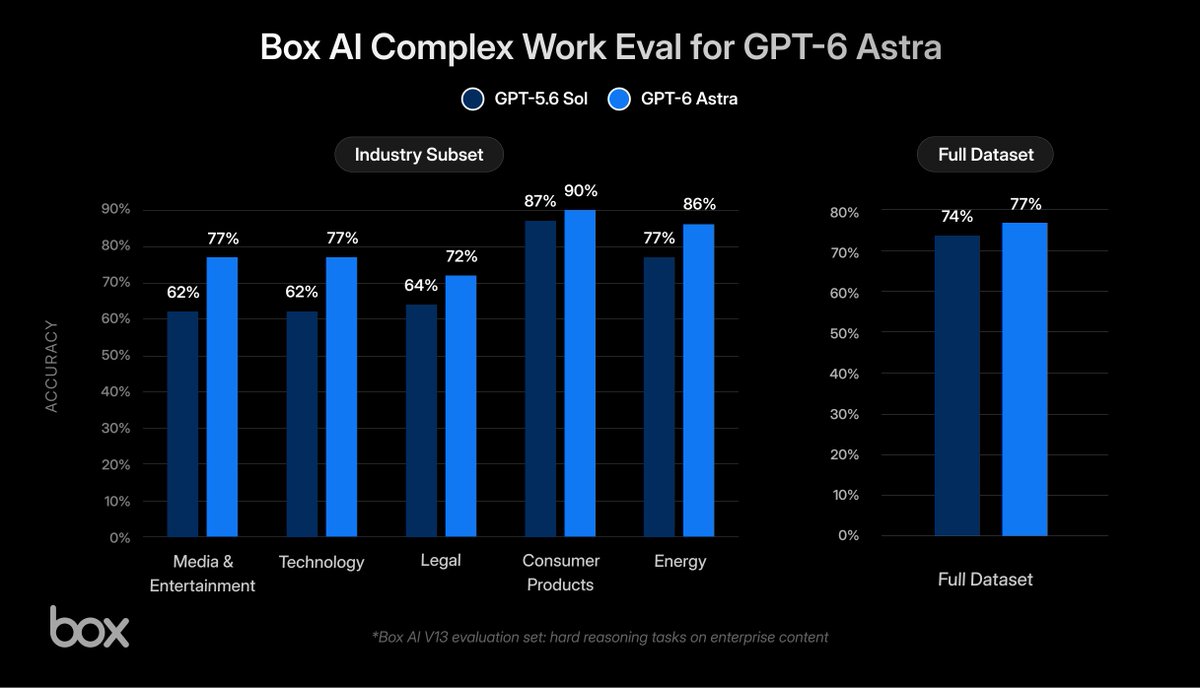
GPT-6 Astra scored 77% overall vs. 74% with GPT-5.6 Sol, representing frontier performance. But the story is in some of the bigger gains on individual task types that are incredibly complex across. Here are a few examples across the tests that show how much of an impact this will be in different industries:
* Media and entertainment (48% → 100%, +52 points). Ranking film genres and countries by profitability across a year of production data from four teams, where the trick is to apply the following year's tax-incentive corrections without double-counting them. GPT-6 Astra was perfect on every attempt. Sol had the rankings right but the underlying ratios were wrong.
* Technology (69% → 97%, +28 points). Choosing which region to fund first, from a stack of performance and infrastructure documents that never state the metric the brief asks for. GPT-6 Astra flagged the gap, labelled its own figure a proxy, and caught a growth claim that didn't match the numbers beneath it. GPT-5.6 Sol reported the proxy as the real thing.
* Legal (69% → 93%, +24 points). Reviewing an NDA against a company's own contracting policy, where reaching the right verdict isn't enough; the answer has to cite the provision behind it. Both models declined to approve the draft, but only GPT-6 Astra separated whether the liability cap's structure was permissible from whether its amount was defensible, and pointed to the policy language that settles it. GPT-5.6 Sol argued the same conclusion without citing the provision, which is a critical error in the legal industry.
* Healthcare (53% → 77%, +23 points). Auditing a batch of radiology reports for errors and rating how serious each one is. GPT-6 Astra caught a terminology error in a knee-imaging report that GPT-5.6 Sol missed on both attempts, and was more reliable at grading severity rather than just flagging that something was wrong.
* Energy (82% → 97%, +15 points). Building a consumption report on two facilities from a year of meter logs, where only one of the two sites is actually missing data. GPT-6 Astra found it and drew a line most reviewers wouldn't: the other site's odd solar readings are a measurement problem to investigate, not a gap in the record. GPT-5.6 Sol reported both sites as incomplete.
Astra clearly is going to offer a meaningful jump in powering and orchestrating enterprise workflows. We'll be making GPT-6 Astra as an option in the Box AI Studio for customers to build agents with shortly as it continues to roll out.
Claudeforce is here. ⚡️ The #1 AI (Claude) now runs natively on the #1 CRM (Salesforce). Through the new AIforce harness + Headless 360, Claude gets direct, governed access to Data 360, Tableau, Slack, and your entire Salesforce workflow—without ever leaving the chat.
What this changes today:
• Instant Grounded Intelligence — Ask complex enterprise questions and get real-time, trusted answers
• App & Agent Builder — Deploy custom workflows, agents, and secure apps on the fly
• Action-Oriented — Trigger live enterprise actions and get work done, not just summaries
• Ironclad Governance — Zero Data Retention, full trust boundary, Salesforce-certified by default
Probabilistic models alone can’t run a company. Deterministic systems alone can’t reason. Claudeforce fuses Claude’s reasoning with Salesforce’s trusted data and controls. The AI is the interface.
This is how every business will run.
See it at Dreamforce. #DF26
Introducing Index
Today we're coming out of stealth with the largest and most diverse robot dataset to scale general purpose robots
To date we've crossed 264,000 app downloads and uploaded 16 million videos
An hour of agentic computer use may now be cheaper than an hour of human labor:
Computer-use agent: $6-8
Offshore outsourced talent: ~$10
US talent: $30-45
"The math only gets better - inference keeps getting cheaper, and open-source models are getting good enough for a growing share of these workflows."
The data on computer-use agents, from @fabrisera2000, @seema_amble, and @zephratic: https://t.co/eOO1JIrT1J
Show Codex a workflow once. Reuse it as a skill.
Record & Replay lets you show Codex a recurring task, like filing an expense report or submitting a time-off request.
Codex turns that demo into an inspectable, editable skill.
You control when recording starts and stops.
The US government, citing national security authorities, has issued an export control directive to suspend all access to Fable 5 and Mythos 5 by any foreign national, whether inside or outside the United States, including foreign national Anthropic employees.
The net effect of this order is that we must abruptly disable Fable 5 and Mythos 5 for all our customers to ensure compliance.
Access to all other Claude models is not affected.
We apologize for this disruption to our customers. We believe this is a misunderstanding and are working to restore access as soon as possible.
Read our full statement: https://t.co/bwn0sximKZ