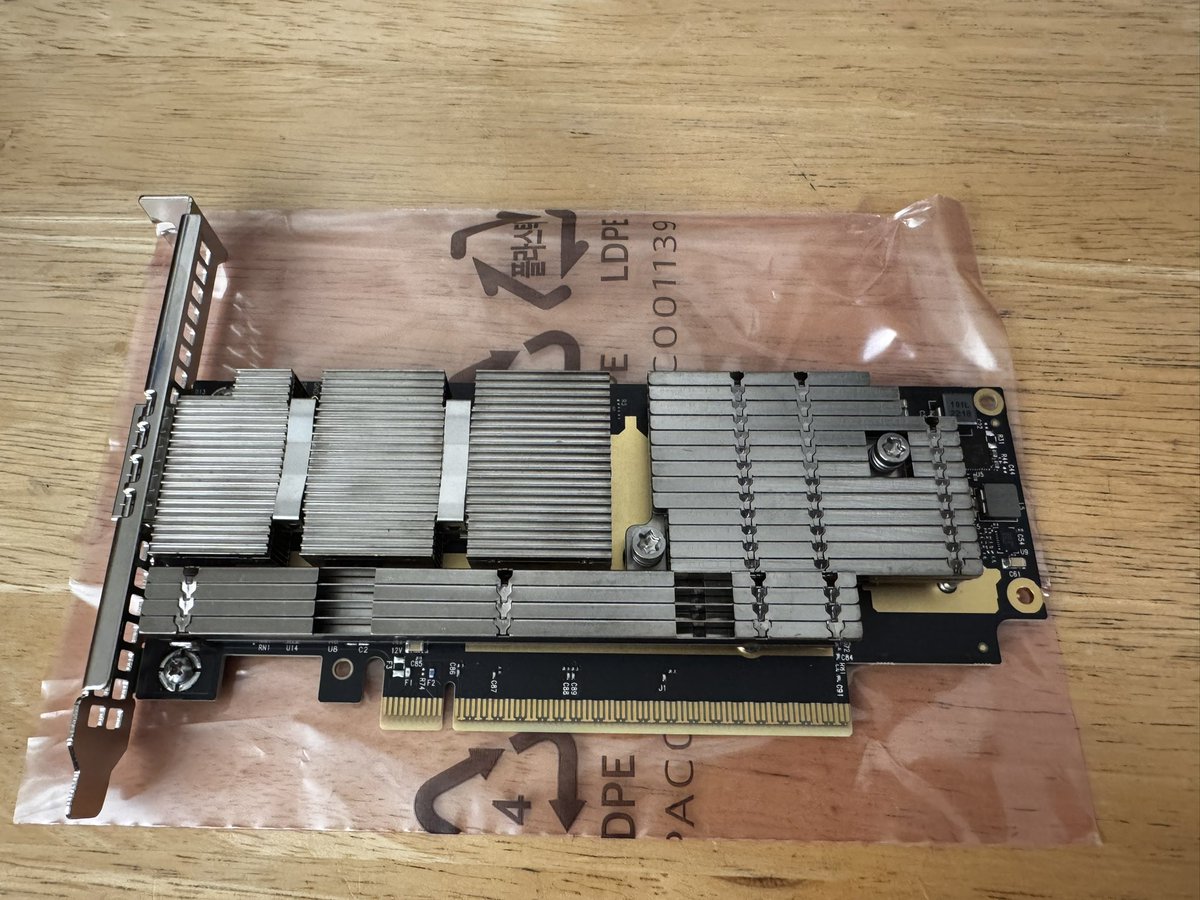
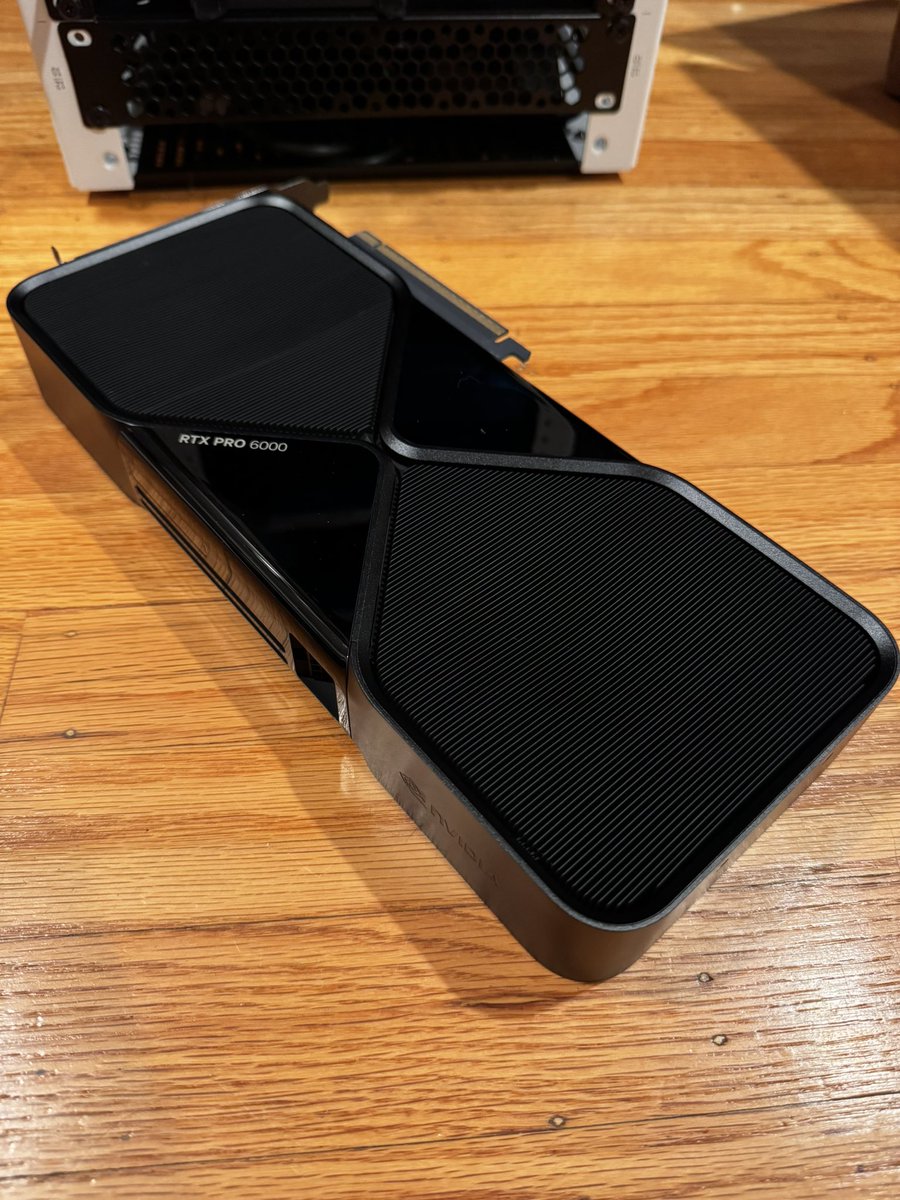
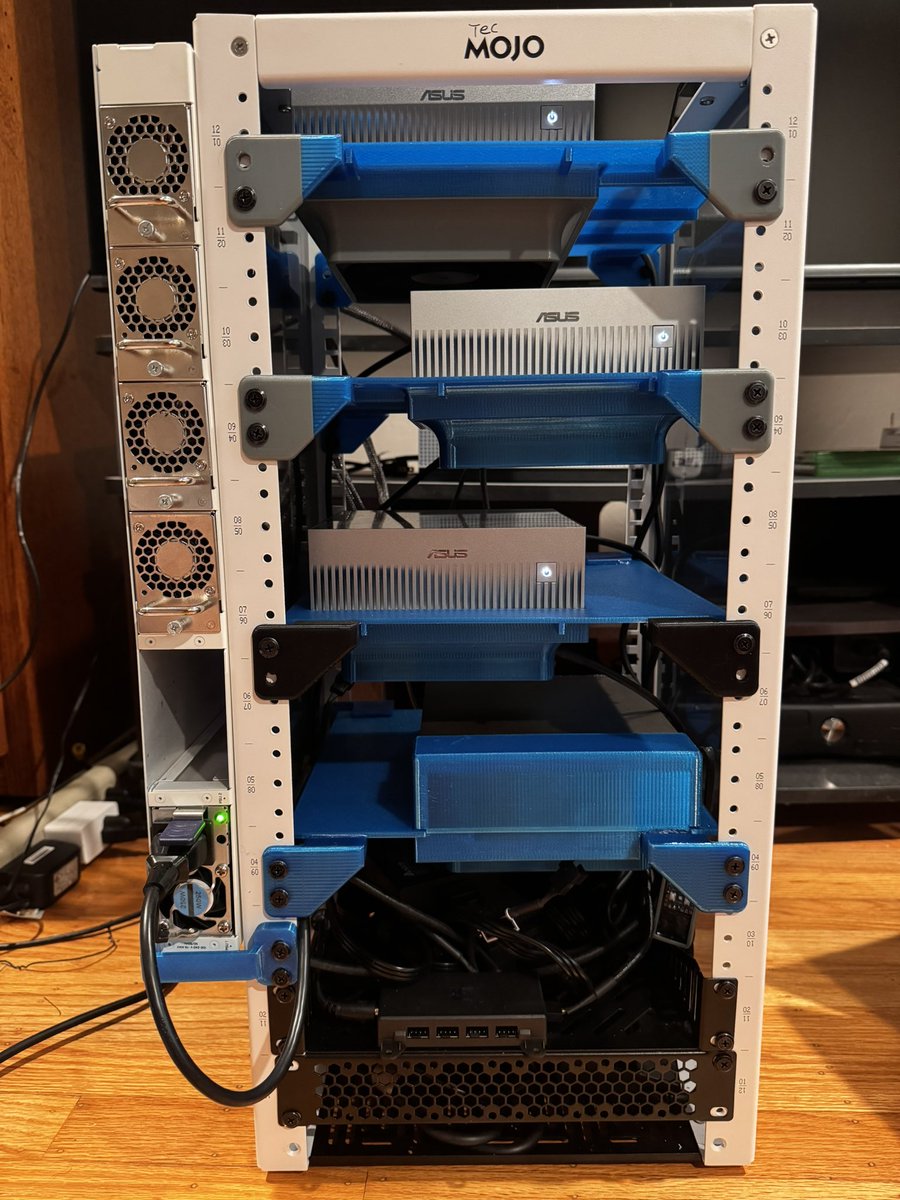
New toy arrived. Using this to bridge my RTX PRO 6000 workstation into my DGX Spark cluster via ConnectX-7.
Going to start experimenting with a hybrid GPU + Spark setup to speed up large MoE models on the sparks
The meta is using the GPU as the coordinator for attention/KV cache/scheduling/routing etc while the sparks act as distributed workers for the MoE expert compute
Here’s the repo I came across that shows how much faster it speeds things up by: https://t.co/6IwzEQOJfE
Tons of potential going this route
@liu5269@ItsmeAjayKV Good choice on their end, A3B is too small, better to focus on the mid sized models like qwen 3.8 flash next or even a ~400B sized
@cpaek72@autonomous_labs It's a dangling carrot for sure, but frontier models getting cheaper with less energy costs? Then why are they cutting our quotas for subscriptions by more and more every time a new model is released?
@superalesha Having 8gb and 12gb means they got their GPU for gaming, and not for AI. Lowering the model's size and quality just to cater to people who aren't actually using AI in a meaningful way is a waste of resources