Eridu is a pioneer in AI networking, breaking through the network wall with a leap in radix, throughput, and performance for scale-up and scale-out networks.
If you're at #OCPSummit26, don't forget to take advantage of your last chance to learn how Eridu is making petabit-class network switching possible.
Get another espresso drink ☕ (or two or three) to help you power through the last day at the Eridu-sponsored barista stations, and stop by booth S7 in the Expo Ballroom to say hi and enter our drawing for a remote-controlled off-road racer! 🛻
And don't miss today's session with Eridu's Dan Biederman at 2:45pm in room LL21BC on Precise Time in High-Radix Network Switches.
Haven't been able to catch us yet? Reach out at [email protected] to connect.
#AIInfrastructure #AINetworking
Thousands of GPUs in a scale-up domain, connected by a single network tier? Impossible?
Catch our CTO Promode Nedungadi with Dan Daly of Delos Data tomorrow morning at OCP Global Summit as they discuss an open architecture to achieve just that.
Session: An Open Architecture for Multi-rack Scale-up Domain of 5000+ GPUs
When: Wednesday, Oct 14 at 8:00am
Where: Room 220B
Add it to your agenda: https://t.co/5LImAwB9hR
#OCPSummit26 #AInetworking #AIinfrastructure
We're excited to be here as #OCPSummit26 gets into full swing today!
We've got lots going on all week:
📍 Stop by booth S7 in the Expo Ballroom to meet the team and to enter to win a remote control off-road racer
⚙️ Check out sessions on Wednesday featuring Eridu CTO Promode Nedungadi and Delos CTO Dan Daly, and on Thursday featuring Eridu's Dan Biederman
🗓️ A full calendar of meetings and demos in our private suite
Contact us at [email protected] to schedule time to connect or learn more
And don't forget to grab your espresso, latte or cappuccino at one of the barista carts in the convention center--on us! ☕
More info at https://t.co/SRTmbn7gVq
#AInetworking #AIInfrastructure
Increasing switch radix is a key part of solving today's network bottlenecks, but getting there requires solving a number of technical challenges.
Next week at #OCPSummit26, Eridu Distinguished Technologist Dan Biederman will be discussing the importance and challenges of precise time in high-radix network switches.
As switch radix increases, networking systems encounter new timing scenarios that are easy to overlook but increasingly important to understand. The topic takes on particular relevance as AI infrastructure demands flatter networks and higher radix to help AI systems scale.
▶️ High Radix Switches and Precise Time
🕗 Thursday, Oct 15, 2:45pm
📍 SJCC Lower Level, Room LL21BC
And also be sure to check out our session with Delos Data on Wednesday, as well as stop by the Eridu booth in the Expo Ballroom.
More information on Eridu at OCP Summit 2026: https://t.co/SRTmbn7gVq
#AIInfrastructure #AInetworking
1 week until OCP Global Summit! If you're helping to build data centers that are at the leading edge of AI training and inference, make sure to say hi.
A few ways to connect:
➡️ Meet us at Booth S7 in the Expo Ballroom on Tuesday, Wednesday and Thursday
➡️ Check out our Wednesday session with @delosdata on an architecture for scale-up domains of 5000+ GPUs
➡️ Hear Eridu's Dan Biederman dive into solving the challenges of precise time for high radix switches on Thursday
And in case you need an espresso to keep up with everything, get free coffee on us from the barista carts in the Expo hall! ☕
Learn more about what Eridu is up to at OCP and how to get in touch at: https://t.co/SRTmbn7gVq
#OCPSummit26
Solve those challenges and the benefits compound--a high-radix switch enables flatter fabrics, larger single-hop domains, and fewer network stages across both scale-up and scale-out environments.
If AI compute is scaling by orders of magnitude, the network connecting it has to be designed from the ground up for the same trajectory.
Read more in this interview with Eridu CEO Drew Perkins: https://t.co/6khnh3Gj56
If compute is being redesigned around AI, why is networking still based on the switch architectures and designs that were developed for cloud and SaaS? (Thread follows ⏬)
#AINetworking#AIInfrastructure
Training and inference clusters continue to scale rapidly in GPU count, memory bandwidth, and east-west traffic. At the same time, model architectures and AI-based workloads are driving ever more data movement between accelerators.
As clusters scale, conventional switch architectures require adding tiers. But more tiers mean more hops, more optics, more power, more latency, and more failure points between GPUs that need to communicate at extremely high rates.
Building a network switch that delivers the order of magnitude advance in radix and throughput that is needed for AI isn't possible by incrementally extending conventional technology.
It's a complex problem that involves solving interrelated challenges in silicon architecture, I/O, packaging, power delivery, optics, system design, and software at the same time. ⏬
What would it take to break out of today's limits to the size of scale-up domains, reaching thousands of GPUs in a single-hop domain?
If you're headed to OCP Global Summit in two weeks, join Eridu CTO Promode Nedungadi and @delosdata CTO & Co-Founder Dan Daly as they discuss an open architecture for building multi-rack, single-hop domains of over 5000 GPUs.
They'll present an architecture that shrinks collective-communication time, tightens token-generation tail latency, and lets a frontier model fit entirely inside a single domain.
▶️ "Breaking up the Monolith - An Open Architecture for Multi-rack Scale-up Domain of 5000+ GPUs"
🕗 Wednesday, Oct 14 at 8:00am
📍 Room 220B (SJCC Concourse Level)
#OCPSummit26 #AIInfrastructure
Agree that bottlenecks in data movement are a complex problem to solve, but one that is critical to performance and scale of AI clusters.
Thanks for attending our presentation at AI Infra Summit by @EriduAi co-founder @omarhassen. The slide you shared from that presentation summarizes the networking challenges that we've been hearing from the market.
We're looking forward to continuing to share our thoughts and experience in solving those challenges using a system-level design approach. High radix is at the center of that, in the context of a system architected from the ground up to utilize that effectively.
We're excited to be part of OCP Global Summit, happening next month in San Jose! We're looking forward to discussing how we're solving the network bottleneck in AI data centers.
If you'll be there, we hope to see you:
🖥️ At our booth in the expo hall, where our team will be talking about our frontier network switching systems
⚙️ On Wednesday in a session featuring Eridu CTO Promode Nedungadi and Delos CTO Dan Daly discussing how to scale AI infrastructure across multiple racks without losing latency
💻 In our private meeting room, where we'll be providing demos and updates
Contact us at [email protected] to schedule time to connect or learn more.
#OCPSummit26 #AIInfrastructure
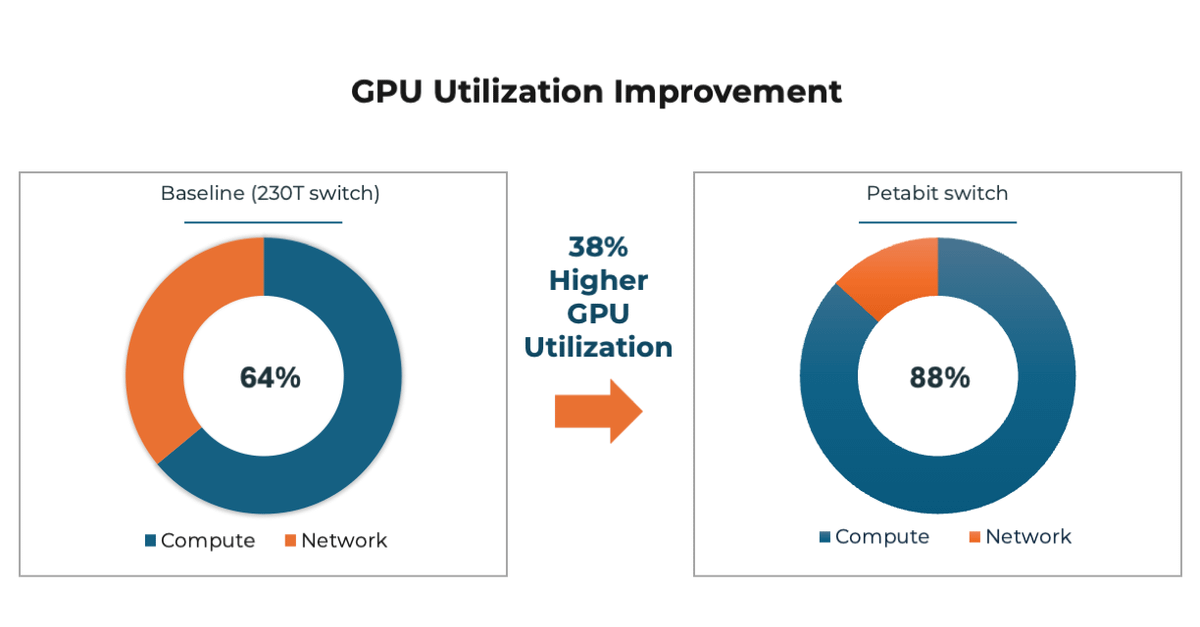
📊 38% improvement in GPU utilization--from 64% to 88%
⚡ 4.5x faster all-to-all collectives
📈 27.5% faster job completion time
Those results demonstrate how important the network is for training--not only for training performance, but also because it impacts cost and scalability of the infrastructure needed to support training.
That's why Eridu is focused on delivering an order-of-magnitude advance in radix and throughput with a purpose-built network switch that has been designed from silicon to system for the demands of AI. https://t.co/5ATfwP0p6I
To learn more:
▶️ Watch the Hot Interconnects Recording: https://t.co/43CnSs6Hxv
📊 See the slides: https://t.co/FPeCKkR6aM
Underutilized GPUs are one of the most significant obstacles to improving performance in AI model training. A recent session at @IEEEHOTI found that improvements in networking could increase GPU utilization by 38%, a significant improvement with a direct impact on training performance, scalability and cost.
Thread with more information follows.
#AInetworking #HotInterconnects2026
The scenario: researchers from Turbalance and Lawrence Berkeley National Laboratory ran a deep simulation of the impact of a 1 Pbps network switch on training time for a frontier mixture-of-experts AI model, comparing it to a baseline scenario using a hypothetical 230 Tbps switch.
The training workload: a ~20T parameter MoE model derived from Llama 4 Maverick, with 2,304 experts (16 active).
The approach: Turbalance's trace-driven, discrete-event simulator whose flow-level backend models point-to-point traffic for every collective.
Their results for a maximum expert parallelism scenario:
We had a great week at AI Infra Summit talking with customers, partners and investors! Some of the highlights:
➡️ Co-founder Omar Hassen on stage talking about why high-radix network switching is critical to the advance of AI
➡️ A packed schedule of meetings and demos where we were able to share a sneak peak at the progress we've made
➡️ Running into former colleagues and friends from our decades of experience in the industry
✉️ Didn't get a chance to connect at the show? Contact us at [email protected] to get in touch.
Happening tomorrow: see Eridu Co-Founder & CPO @omarhassen live at AI Infra Summit talking about how to solve AI networking's most important challenges.
🕛 12:00 PM
📍 Data Movement Track
More info at https://t.co/IhnWoqzBc0
See you there!
#AIInfraSummit #AInetworking #AIinfrastructure
Eridu is hiring in Taiwan! We're looking for experienced engineers ready to step in to important roles in our growing engineering team.
You'll work with a team that has decades of experience to help us build next-generation network switching systems for AI that incorporate multiple industry-first innovations across silicon, packaging, software, and systems.
We're looking for Hardware, Power, Packaging and Mechanical Engineers interested in the opportunity to shape the future of AI infrastructure.
Review openings and apply online at https://t.co/lNGanGwiWb
Wrestling with too many networking technologies and platforms while GPUs are going underutilized? What if you could increase GPU utilization by 38% with a single platform for scale up, out and across?
Join us next week at AI Infra Summit to hear how high-radix network switching enables AI infrastructure to keep up with not only the rapid advances in computing power, but also with the demands of modern AI models and workloads.
👀 Join our co-founder @omarhassen on Sept 15 at 12pm as he discusses upcoming innovations in network switching that can break through the network wall: https://t.co/IhnWoqzBc0
✉️ Reach out to us at [email protected] to set up time to meet our team and see a private demo
Hope to see you there!
#AIInfraSummit #AInetworking #AIinfrastructure
What will it take to address the rapidly-increasing pressure on the back-end networks that are critical to AI clusters?
A great panel of industry experts from Open Compute Project Foundation, 650 Group and Eridu dove into that topic recently, looking at the growing challenges in networking that result from the exponential growth of AI.
➡️ Why conventional switch architectures are hitting a “network wall” as GPU clusters grow
➡️ Why scale-up networks are moving beyond a single rack toward larger, multi-rack domains with optical interconnects
➡️ What technology innovations are needed to make an order of magnitude advance in switch performance and scale
➡️ How higher-radix switching can create flatter networks with fewer hops, less complexity, and more efficient use of infrastructure
Hear the full conversation in the webinar replay (free registration required) at https://t.co/BeNXDN5Dhl