A simple recreation of "aha" moment of Deepseek R1 based on VeRL. This was a good learning in RL post training, VeRL framework and good design practices. Next step is to create wrappers around env e.g like @PrimeIntellect
https://t.co/CqAl4W2zOf /
https://t.co/xAp1lQJEub
Terence Tao put it plainly: there is no evidence that LLMs exhibit genuine creativity.
Yes, they have solved some Erdős problems. But these are low-hanging fruit, questions that attracted little attention and that yield once the right existing techniques are applied. That is not creativity. That is search plus recombination.
Yes, LLM outputs can look impressive. But look at who is impressed: typically non-experts. Experts know very well that LLM performance gets terrible when you approach the frontier of human knowledge.
And this is not a temporary gap. It reflects a structural limitation.
We do not fully understand human creativity. But we do know a key property:
Conceptual leaps: the ability to generate new representations, not just recombine existing ones.
LLMs do not do this. They interpolate in representation space. They operate within existing conceptual frameworks; they do not create new ones.
This is why we haven’t “yet seen them take the next step”.
Introducing TurboQuant: Our new compression algorithm that reduces LLM key-value cache memory by at least 6x and delivers up to 8x speedup, all with zero accuracy loss, redefining AI efficiency. Read the blog to learn how it achieves these results: https://t.co/CDSQ8HpZoc
@PrimeIntellect The inspiration for this project came from @jiayi_pirate although a year late but still many lessons learned along the way. thanks for the datasets and special thanks to @verl_project
A simple recreation of "aha" moment of Deepseek R1 based on VeRL. This was a good learning in RL post training, VeRL framework and good design practices. Next step is to create wrappers around env e.g like @PrimeIntellect
https://t.co/CqAl4W2zOf /
https://t.co/xAp1lQJEub
@willcb Would love to join but currently working on my own framework around VeRL. Lately @karpathy is inspiring me to do stuff on your own in the code (lean code).
@drfeifei I saw your talk on lenny's and now here. Coming from automotive domain personally I feel it a bit hard to measure spatial intelligence. Ofcourse you see some traces in some models (VLM, VLA) etc but to me that's not the intelligence itself. Was wondering how to measure it
@levelsio What are you trying to achieve here? I think there are other models out there which are taking care of generating lipsync videos although low resolution in the start and but if real time is not the issue then you can use image enhancer models and you will get nice lipsynced video
@karpathy I use noise canceling headphones with some puffy pillows and it's nice. Haven't recorded the data yet but would be nice to see some data on it.
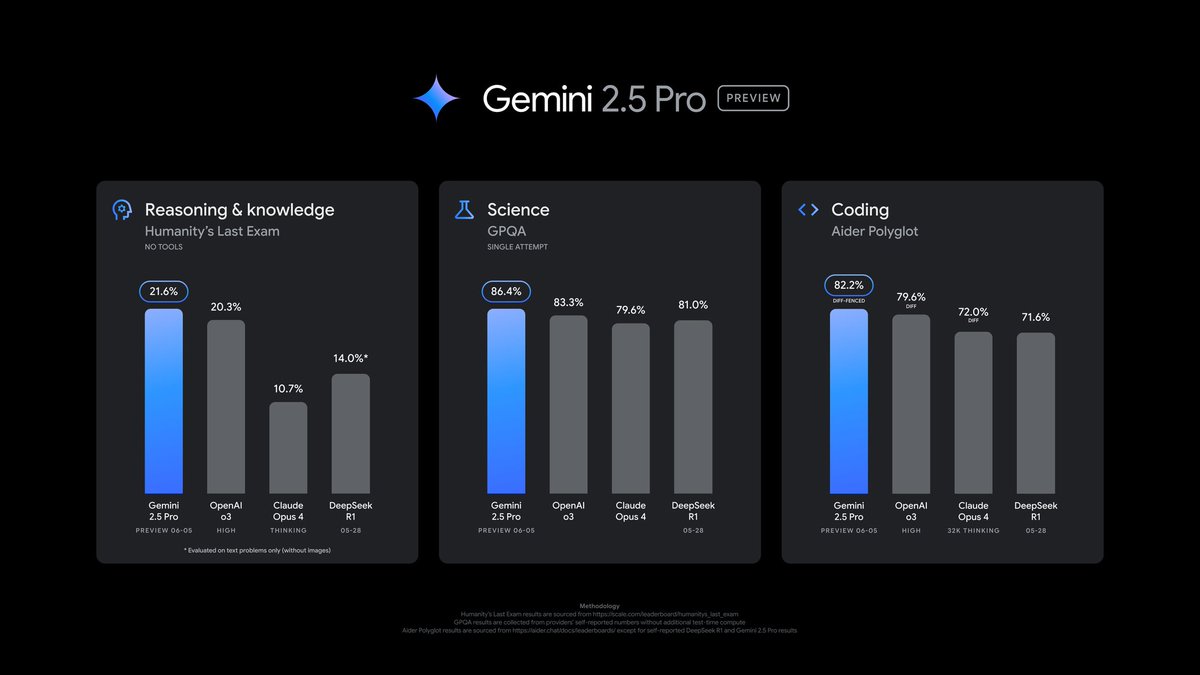
Our latest Gemini 2.5 Pro update is now in preview.
It’s better at coding, reasoning, science + math, shows improved performance across key benchmarks (AIDER Polyglot, GPQA, HLE to name a few), and leads @lmarena_ai with a 24pt Elo score jump since the previous version.
We also heard your feedback and made improvements to style and the structure of responses. Try it in AI Studio, Vertex AI, and @Geminiapp. GA coming soon!