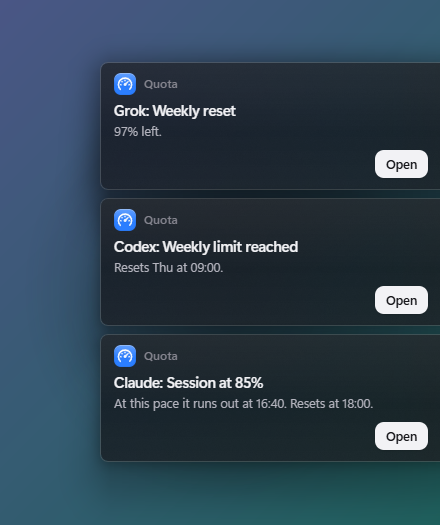
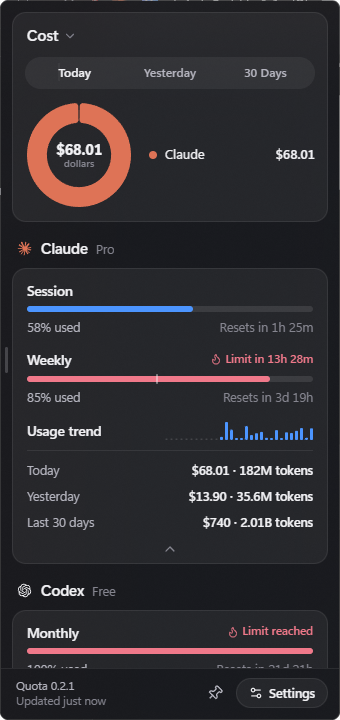
First Holster app just dropped: Quota
It shows all your AI subs in one place (Claude, Codex, Cursor, Muse Code, OpenCode, and more...)
You can track limits, spending, tokens used, and usage projections
Built on top of OpenUsage by @robinebers
Download in the replies
First Holster app just dropped: Quota
It shows all your AI subs in one place (Claude, Codex, Cursor, Muse Code, OpenCode, and more...)
You can track limits, spending, tokens used, and usage projections
Built on top of OpenUsage by @robinebers
Download in the replies
Built a dock for the little apps I keep making for myself. Lives on the edge of the screen, hover a tile and the preview peeks out!
It's called Holster, Windows 11 only
https://t.co/COu3FmptDv
The dock doesn't have any real apps out of the box, so I'll release some of my own in the coming days. But you can use the skill to build your own right away!
Built a dock for the little apps I keep making for myself. Lives on the edge of the screen, hover a tile and the preview peeks out!
It's called Holster, Windows 11 only
https://t.co/COu3FmptDv
@_ak_111 Opus 5.5 is way better at coding and designing. But Sol is useful for reviewing and finding optimizations.
Also with the current limits, Claude is probably the better value
The cache expires after about 1 hour, so compacting the next day means the servers have to reprocess all your context from zero.
I suggest compacting manually when you finish a task (while the cache is still warm), especially if the context exceeds 200/250k tokens. If the agent finishes overnight and in the morning the cache is expired, just start a new session. Re-explaining the project is often not needed if the previous agent saved things in the project memories, this way you just need to start a new session and ask it to explore the project, the agent will go through the project + memories on its own.
It sounds impressive if you don't know what it is
The max output is just how many tokens a model can generate in a single turn, every tool call usually ends the current turn and the agent continues in another one.
Agents don't generate one giant response, they output hundreds of short ones...
The craziest part of Gemini 4 Argon...
1M OUTPUT tokens.
Not context... Output...
GPT-6.1 Sol: 128K
Claude Opus 5.5: 128K
Claude Sonnet 5.5: 128K
Claude Fable 5.1: 128K
Gemini 4 Argon: 1,000K 🤯
That's nearly 8x the standard output limit of OpenAI + Anthropic's frontier models.
Context = how much AI can read.
Output = how much it can generate + work through in one run.
1M output means much longer coding, research and agent workflows without stopping and restarting.
It's a big deal.
@BernieSanders Pausing AI is harder than it sounds, I explained a bit more here (this specific article was about the late July debate, but the core argument is the same): https://t.co/GeNUAVfKWV
A thousands frontier lab researchers signed a statement asking for tools to pace AI development.
Pacing only works if everyone paces. China is behind and closing, and nobody touches the brakes while closing the gap. https://t.co/cuW7XkttJZ