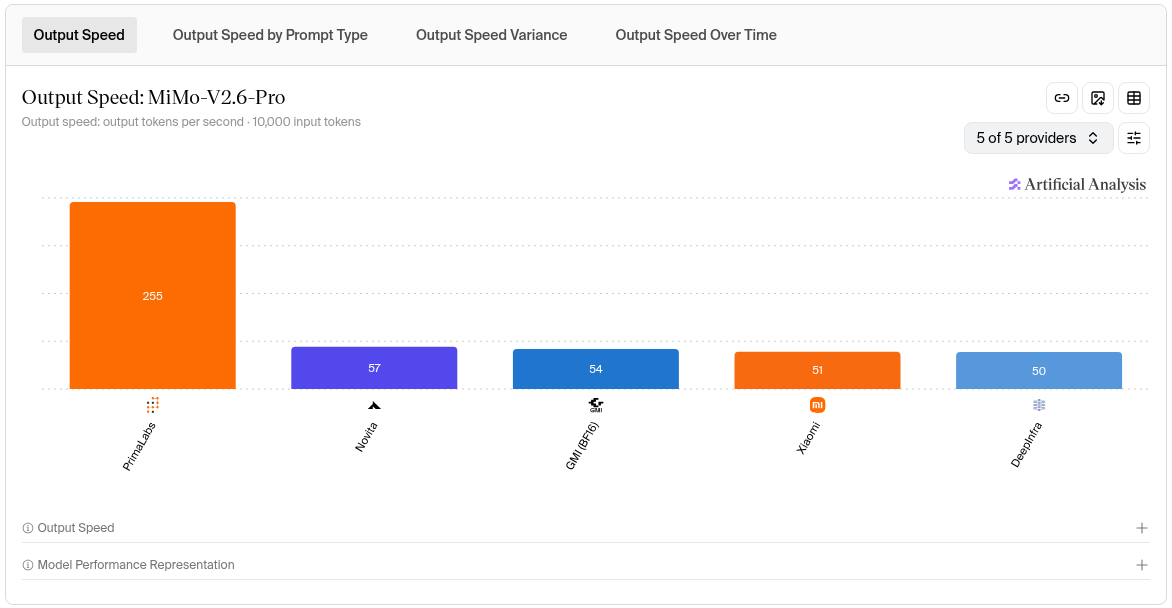
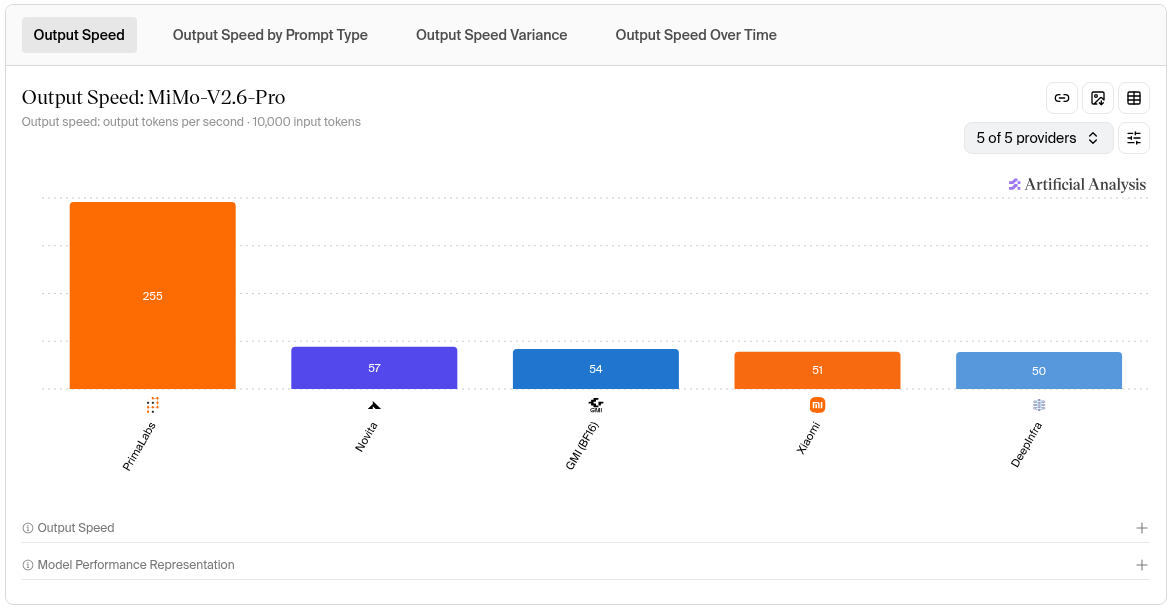
Fastest MiMo-V2.6-Pro endpoint on Artificial Analysis.
407 tok/s at 10K input. 9x Xiaomi's own API.
5.6s to first token vs 47.2s.
$0.87 per 1M output tokens.
Try it today.
2,000+ people. Two days. The first SGLang Summit.
Together, we announced SGLang v1.0, released Miles v0.2, and launched the SGLang Consortium with nine founding members: @nvidia, @AMD, @intel, @Google, @Meta, @thinkymachines, @Cloudflare, @modal, and @radixark.
SGLang is now used by 332 organizations. At Meta, it powers production inference for products serving billions of users. Teams from Modal, Cloudflare, LinkedIn, and others shared their production lessons.
Across 90+ technical talks and six hands-on workshops, the community explored what comes next for inference, reinforcement learning, and AI agents.
To everyone building, deploying, and contributing: thank you for making this possible.
Explore the announcements, engineering lessons, and moments from SGLang Summit 2026 in the link below.
The PrimaLabs team just wrapped a great few days at @sgl_project Summit in San Francisco, where our Co-Founder and CEO @pbalapra , took the stage to share how we serve the fastest open-model inference.
Huge credit to the crew who held down the booth: @Chaitanyahir , @ankitainfers@david_lee28691 and Yes, they were smiling like that the whole time.
Thank you to everyone who stopped by to meet the team. Fast tokens, great people, and not nearly enough coffee.
The fastest open models, now connected to live enterprise data.
We're excited to partner with @cdatasoftware . PrimaLabs brings fast open-model inference, ranked at the top of Artificial Analysis.
CData Connect AI Gateway brings governed access to hundreds of enterprise sources.
Together, teams can run agents on open models with the data access and controls they already need.
Looking forward to building this with the @cdatasoftware team
https://t.co/K5eHRTxYFj
@AdamHoltererer Thanks for the shoutout, @AdamHoltererer Great to see PrimaLabs in S-tier for accuracy. We’re also now #1 for Kimi K3.1 Pro cost per task on Artificial Analysis. Excited to keep pushing on performance and value.
AA benchmark: https://t.co/0J8zue69xC
@Kimi_Moonshot K3.1 Pro is live on PrimaLabs.
On OpenRouter right now, we’re the fastest of the 16 providers serving it: 120+ tokens/s. Cache hit rate above 92%.
$1.80 / $9.00 per 1M tokens, 55% below Claude Opus 5.5.
46 on the Artificial Analysis Intelligence Index.
Try it now: https://t.co/upGCVHrEw2
@merge_api@Xiaomi@Meta MiMo-V2.6-Pro leads open weights, and on Artificial Analysis we're the fastest provider for it at the same price as everyone else.
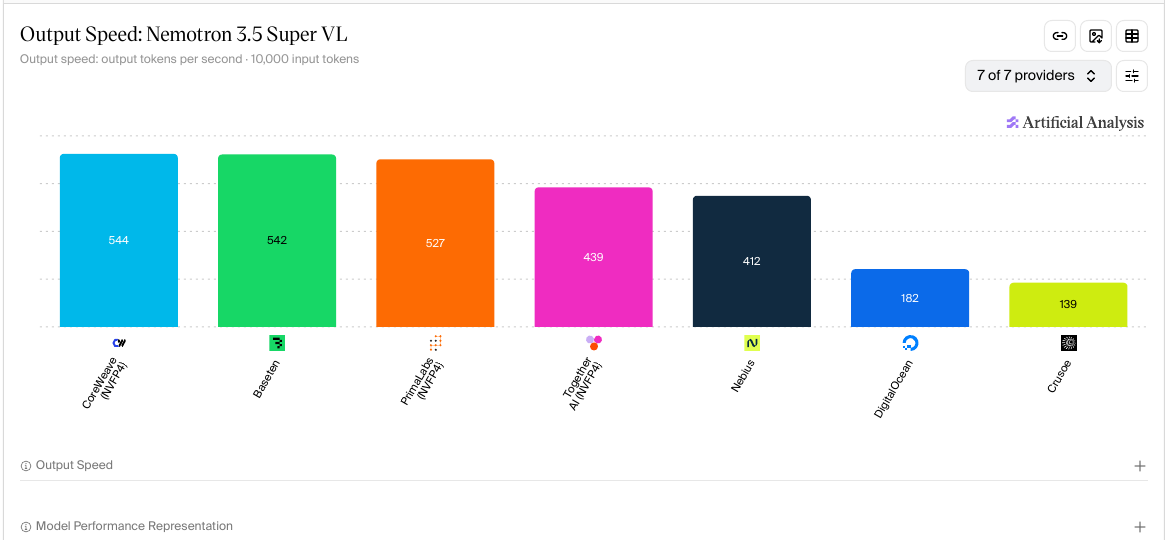
@NVIDIAAI@ArtificialAnlys We're serving Nemotron 3.5 Super VL at 526.8 output tokens/s on Artificial Analysis, #3 of 7 providers, with the #2 end-to-end response time (5.49s).
@ArtificialAnlys Super VL is live on PrimaLabs serverless. AA measures us at 526.8 t/s output and 5.49s end-to-end, #2 of 7 providers on response time.
@gptzone_net on a long task the price is the same everywhere, $0.18 blended at all 5 AA providers. speed isn't: 31 to 188 tok/s. we run the 188 one.
https://t.co/ty6LGd4pb3