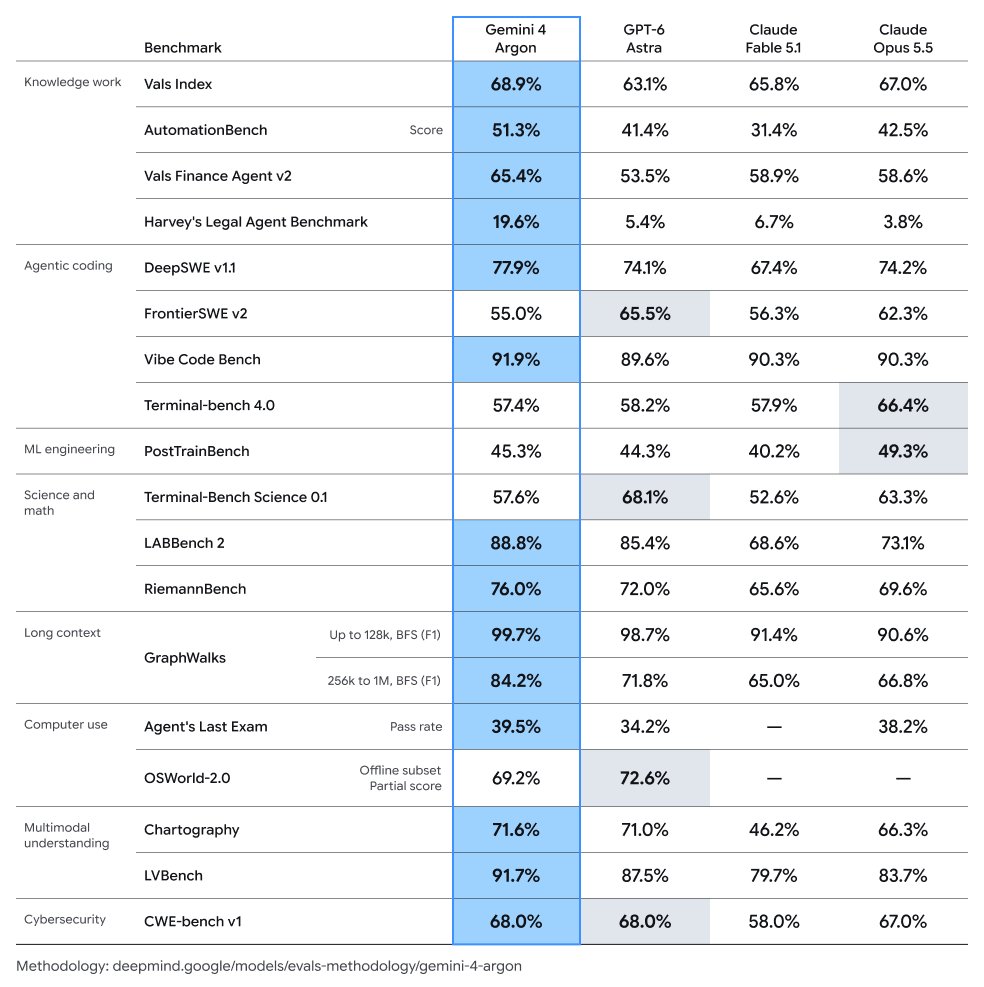
If you announce a model's benchmarks without releasing it (weights, product, api, etc "later"), feels like almost a sure thing that someone releases a better model in your category before you get it out.
This is actually completely backwards, the largest customers (OAI/Ant/Meta) only take/highly prefer baremetal.
Managed k8s/slurm is great for small/medium labs. But even amongst these, you'd find a preference for baremetal.
The framing makes it sound like baremetal is easy; it's not.
to be a real neocloud you need to build software, not just supply power and GPUs
lots of people are buying sites and filling them with B300s
that’s cool, they’ll probably sell a few racks, but they’re gonna get blown out of the water by companies that build software
spot is fundamentally a software product. the platform is constantly shifting workloads around and cleaning up between jobs, and you’re solving many orchestration problems at scale
i’d be bullish on anyone doing spot or serverless like https://t.co/lXdOW2HHam
and bearish on anyone buying power and GPUs and calling themselves a neocloud
Jev nailed the product requirements:
- Ultrafast
- Dirt cheap
- Accurate enough
I feel like every "but we already have Jev" post I've seen has just 2 of those 3 but you need all of them.
The Jev moment happening now is similar in energy to the OpenClaw moment that happened in January, and also to the Opus 4.5 moment before that. Developers are scrambling to find use cases for a new hot thing, and it's a sudden blooming of creativity.
Models have typically NOT optimized for specific use cases and have gone the other direction, generalizing over all of them. This could be a very important moment for the whole AI ecosystem if this turns out to be the beginning of other model skews that make the market much more diverse, such as compaction, summarization, extraction and more, all of which can now be used to optimize harnesses and decouple them from provider lock-in.
We'll see what happens over the course of the next few weeks when the model labs optimize their small models more or try new ways of branding and packaging them.
1/ We’re entering the era of agentic commerce, and we believe that world models are the missing engine.
Instead of browsing static product pages, agents will let you interact with products inside your own world before making decisions.
Today, @DecartAI we're releasing Anywear👇
Today, we're introducing @Intelligence_ai.
In 6 months, as a team of 10, we scaled from $5M to $60M ARR and 5.5M users across 190+ countries.
We raised a $7.9M seed, led by @IndexVentures with participation from @conviction, @A_StarVC, and @combinator to build DesignArena, a universal interface for accessing and evaluating the world's AI capabilities.
Most evaluations try to simulate the real-world. We believe the real-world is the ultimate verifier.
People come to @DesignArena with a request. Models compete to fulfill the request, and users determine what works best for them.
Their live user behavior evaluates the models, improves how work is routed, and helps people access the right intelligence.
We've helped the world's leading frontier labs break the news on their SOTA capabilities.
What's the limit? Join us and find out.
Today, SkyPilot is out of stealth.
Building custom intelligence is now existential. We help frontier AI teams build intelligence faster by removing their biggest bottleneck: AI compute fragmentation.
Frontier teams like @appliedcompute, @AbridgeHQ, @hippocraticai, @hcompany_ai, and @nubank already run on SkyPilot, with 10x faster time-to-intelligence and double-digit increase in GPU utilization.
AI teams today get compute anywhere they can. They then firefight compute fragmentation across providers. Researchers burn time on workload setup. Infra gets paged when GPUs go down. Frontier teams build slowly even on the fastest compute.
@skypilot_org turns your fragmented compute into one AI supercomputer, so you run frontier workloads faster. Many users manage 10,000+ GPUs across providers with SkyPilot. GPU hours consumption has grown 6x in the last 6 months.
1/ We're launching SkyPilot Platform — the AI compute platform for frontier AI teams to manage large GPU fleets and accelerate building custom intelligence.
Optimized for fleet management, team governance, and frontier workloads — pretraining, post-training, multi-cluster serving, and sandboxes. SkyPilot open source users can switch to the platform with a server URL change.
2/ We've raised over $20M led by @Lux_Capital (@breeves08), with participation from @AmplifyPartners (@dauber, @lennypruss), @coatuemgmt, @FoundationCap (@ashugarg , @JayaGup10), @RaceCapital, @thehousefund, and top operators like @alighodsi (CEO, Databricks), @JeffDean (Chief Scientist, Google), @rauchg (CEO, Vercel), @amasad (CEO, Replit), @ClemDelangue (CEO, @huggingface) and more.
We're hiring across Engineering and GTM to deliver the platform for the next decade of AI.
Above all, I'm excited to be building with the incredible team we've assembled, along with my cofounders Zhanghao @Michaelvll1, Romil @bromil101, Scott, and Ion @istoica05.
If you firefight AI compute, let's build.
This is a very good teaser but the details behind the scenes are even cooler!
For some intuition on CSM, Cerebras made everyone understand that if you can pool SRAM together on a big wafer you are going to go very fast. Etched can pool the SRAM without needing to keep the dies attached. This means they can push from 8x to 128x to 1000x+ chips all working together in ultra low-latency scale up domains, and then at the same time they can use LVI to pack the die with tons of flops for throughput. These are beautiful ideas and it’s great to see them coming to life!
What if video editing had a “volume knob”?
We are excited to share new research from @DecartAI and @TelAvivUni, accepted to #SIGGRAPH2026. We found directions within video models that enable smooth control over edit strength, from subtle changes to full transformations!
Check out our paper & blogpost 👇