Google has really strong models out finally and good to have them back. But their naming and marketing is atrocious.
Carbon > Argon. Neon is faster but more expensive than carbon. If you stack two Hydrogens side by side you get a helium, but if you stack a hydrogen on top of another hydrogen you get a Neon?
Just wait for tomorrow for the new Gemini Oxygen if the above left you out of breath!
Inkling is the best open-weights model on FutureSim!
It shows the largest improvement at test time across any model.
It starts the lowest and climbs all the way to the top, outperforming even Muse Wonder and landing right next to GPT-6.1-Sol.
Noise + KL reg strikes again 😄. We did a fine-tuning version of this in RoBERTa days(2020): noise on embeddings + KL consistency to reduce representational collapse. Cool that it carries over to pretraining distillation! https://t.co/mpMS1UYqpO
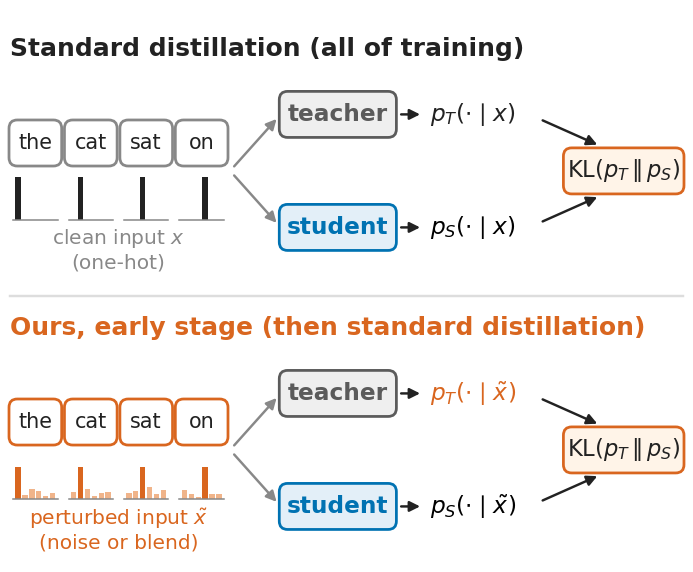
New paper w/ Yihe Dong, @DimitrisPapail & @ShivamGarg91462: Perturbing Inputs Improves Pretraining Distillation.
In pretraining distillation, a small student LM learns to match a larger teacher’s next-token predictions on the training text. We change one thing: for the first part of training, both models read a perturbed version of the text (for example, with noise added to the token inputs), and the student matches the teacher’s predictions on that. Then we switch back to clean text.
With the same steps and token budget, this beats standard distillation, and it also works well in data-constrained, multi-epoch settings. 🧵
> be Anchit Gupta
> study computer science at IIT Bombay
> intern at a research institute in Austria and Samsung’s security lab in Seoul
> graduate in 2017 with three medals
> head to Stanford for a master’s
> research reinforcement learning for robotics in Dr. Fei-Fei Li’s lab
> intern at Facebook, then join full-time in 2019
> spend six years going from NLP research to generative AI
> help create early AI characters demoed to Mark Zuckerberg
> become a staff research engineer
> join xAI in September 2025
> become responsible for RL recipes behind Grok 4.5 and 4.6
> work on coding, machine learning, and long-horizon tool use
> join Thinking Machines Lab in August 2026
> help bootstrap long-horizon capabilities from near-zero pass rates
https://t.co/QTDVYwrWXA
inkling 2 small is extrememly impressive
it's a new pre train from scratch (17B active 594B total param), train fully in only a few dozen of days, with much much much less compute and data (only 12T token!) than any other model they are competing with. the base model ppl loss on their internal code is lower than Kimi K3.1 (they even "base-recovered" the model to make a fair comparison!!)
the benchmark are super strong overall and they also optimize for metric and domain that they care, like finetunability and domain like finance
huge congrats, imo one of the most impressive release in the open weight western ecosystem this year
https://t.co/ceHO9OQ5ln
8.4T tokens in 68 hours, natively in NVFP4 🔥
that was the main pretraining phase for Inkling 2 Small. no magic, just solid things done right. so proud of this team!
this is just one rung of our predictive scaling ladder 🪜 more coming soon!