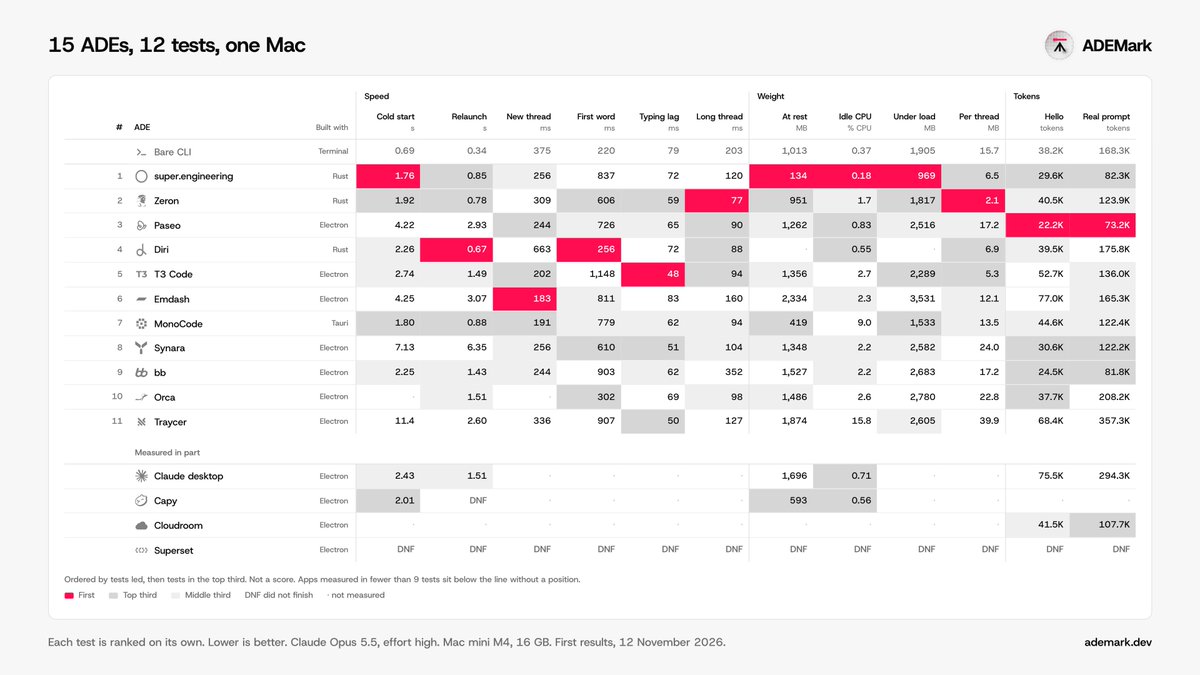
ADEMark v1 is out.
Same Mac mini, same tasks, same model, bare CLI as the baseline.
Did not expect most of them to use fewer tokens than the CLI on its own. Or one to sit at 16% CPU doing nothing.
First of many, updates come way more often from here.
https://t.co/xKWlPADGbb
@andrewdfeldman@cerebras 36 seconds changes behavior more than the benchmark does. At that speed people ask the agent before the standup instead of digging through Linear after it.
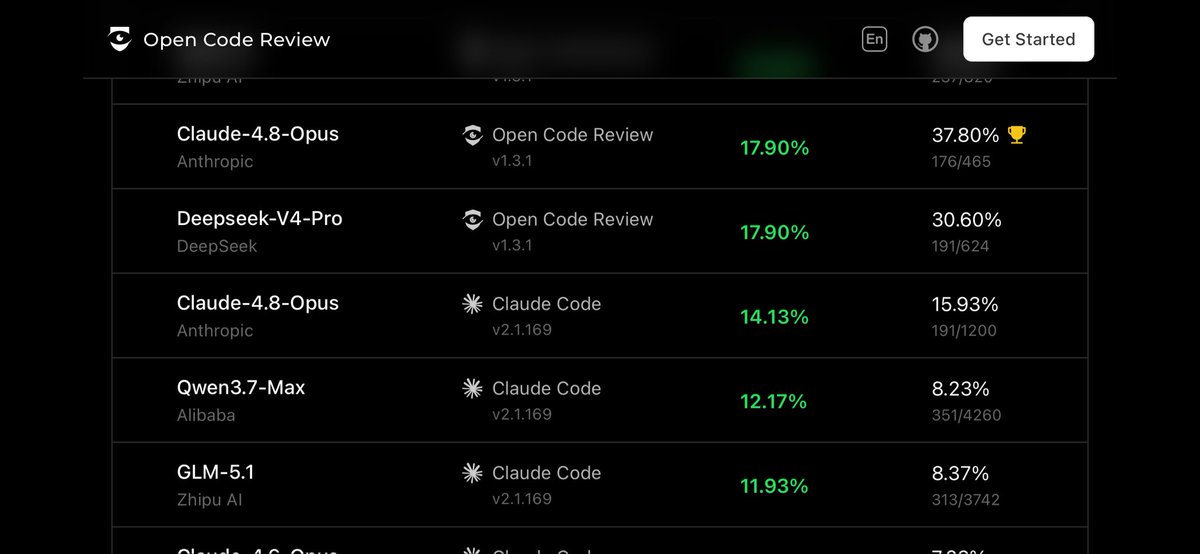
A Alibaba abriu o code review que usa internamente há dois anos. No benchmark deles, com o mesmo modelo, gasta ~1/9 dos tokens do Claude Code e termina mais rápido, porque escolher arquivo e cravar a linha do comentário é código determinístico, não LLM.
https://t.co/H0EgrOpJF3
De 85 segundos pra 0,3 no primeiro token de uma conversa longa, num modelo de 27B rodando local num Mac.
Isso é a diferença entre um agent que você usa e um que você abandona. E roda num binário Zig, sem Python. https://t.co/kNUu3LubO6
TensorFold 1.2.7 is out. 🔥
A big fix for long conversations on Metal: Qwen3.8-27B now reuses its history even when the client drops earlier reasoning.
In the measured M3 Ultra test with 34k history and a 5 GiB prompt cache, follow-up time to first token dropped from about 85s to 0.3s. Same replies in that test.
Also in this release:
• Responses API over WebSocket.
• LightOnOCR-3 0.8B and 4B image chat on CUDA.
• Opt-in GLM conversation reuse at turn boundaries on CUDA.
• Prompt-cache and disk-tier stats in the dashboard.
• Targeted speed and memory improvements across Metal, CUDA and HIP.
• Fixes for GPU builds, malformed GLM tool calls, damaged JPEGs and disk-cache recovery.
Massive thanks to everyone contributing code, testing on their hardware and reporting issues. I really appreciate the time you put into this.
@andersjw_@Bizuayeu@defilan@devopsfortunato@unigilby@kelchm@teleogen@petruspennanen
And on GitHub: AbrahamCete, BobClawblaw, ciprianveg, garvrao80, jschmied, laidick, millaguie, Mirrdhyn, mrv777, tacosta, volfco and wojo.
Thank you too to the tester who reported the JPEG fault privately.
@volatilemarkts@MiaAI_lab@petruspennanen@plotarmordev
Servir LLM direto de um binário Zig, sem Python, já seria motivo pra olhar o TensorFold. Mas o que me ganhou foi o Recall.
Quando o agent volta a escrever um código ou tool call que já escreveu antes, o engine confere o trecho inteiro em poucas rodadas em vez de gerar token por token. E a resposta sai exatamente igual, só mais rápida.
https://t.co/Lhp2Hnc2qM
Saiu o Codex Security da OpenAI: o scan usa o SECURITY.md do repo como guia do que importa, e o próprio CLI rascunha esse arquivo fora do repo, sem tocar no que já existe. Você revisa o diff e só então copia.
https://t.co/EbuNc4wpJa