This paper is both a nice tip of the hat to the films of Danny Boyle, and another step in our ongoing quest to reconstruct everything in the world in 3D. Check out more at the webpage here!
https://t.co/slEIh1hs8g
Check out this cool work from @hanyuc1110 on creating really useful new data for training 3D foundation models like VGGT!
He uses the wonderful zoo of images on Wikimedia Commons to reconstruct very nice 3D models of objects from vintage Atari computers to Ford Fiestas.
Choose life. Choose a train, a statue, a pipe organ. Choose a 1967 Volkswagen Beetle, a K6 red telephone box in London.
We chose not to choose. We reconstructed them all.
Introducing 🚂 📸 Trainspotting: 12,068 objects reconstructed in 3D from 311,886 found photos.
🧵
1/8
Choose life. Choose a train, a statue, a pipe organ. Choose a 1967 Volkswagen Beetle, a K6 red telephone box in London.
We chose not to choose. We reconstructed them all.
Introducing 🚂 📸 Trainspotting: 12,068 objects reconstructed in 3D from 311,886 found photos.
🧵
1/8
Please apply to come be a postdoc at Cornell through this wonderful Empire AI Fellows program! I'll be looking to recruit a postdoc myself alongside the rest of the vision group at Cornell Tech in NYC.
Cornell (and me) is hiring postdocs, with focus on technical AI/ML research. Deadline for full consideration is Dec 15.
I am recruiting through this call as well. I encourage applying as early as possible, because I am starting to review folders now!
Application link ⬇️
Honored and humbled to receive the ECVA PhD Award at #ECCV2026@eccvconf! So grateful to my advisor @mapo1 for his guidance throughout, to all my brilliant coauthors over the years, and to the computer vision community for the support and the journey together. Thank you all
🚀 We are excited to release the dataset, code, and expanded paper for ORBIT++: Benchmarking SfM in the Wild with 360° Video!
Following our initial publication at CVPR, we’re releasing the full benchmark and codebase:
🌐 Project: https://t.co/YsWjbc4f5Q
📄 arXiv: https://t.co/NIX3aHCFrF
💻 Code/Data: https://t.co/0eTYkAR3Gu
(1/3)
Introducing FilmGPT 🎬 (#SIGGRAPH2026)
Can we learn the grammar of film directly from movies?
We train an AR transformer on feature films to edit raw footage into coherent cinematic sequences, without generating new pixels.
Project page: https://t.co/tHFbaEfn7P
Demo below👇
Picture stepping into a live 3D broadcast or 3D video call and looking around freely. That is the promise of dynamic NVS.
But multi-view camera setups are fixed so parts stay hidden. Looking anywhere means recovering them from memory, which current stateful and stateless models cannot do in real-time over long-horizons.
Until now. Introducing NSTM.
⚡️Real-time inference + 🧠minute-long memory.
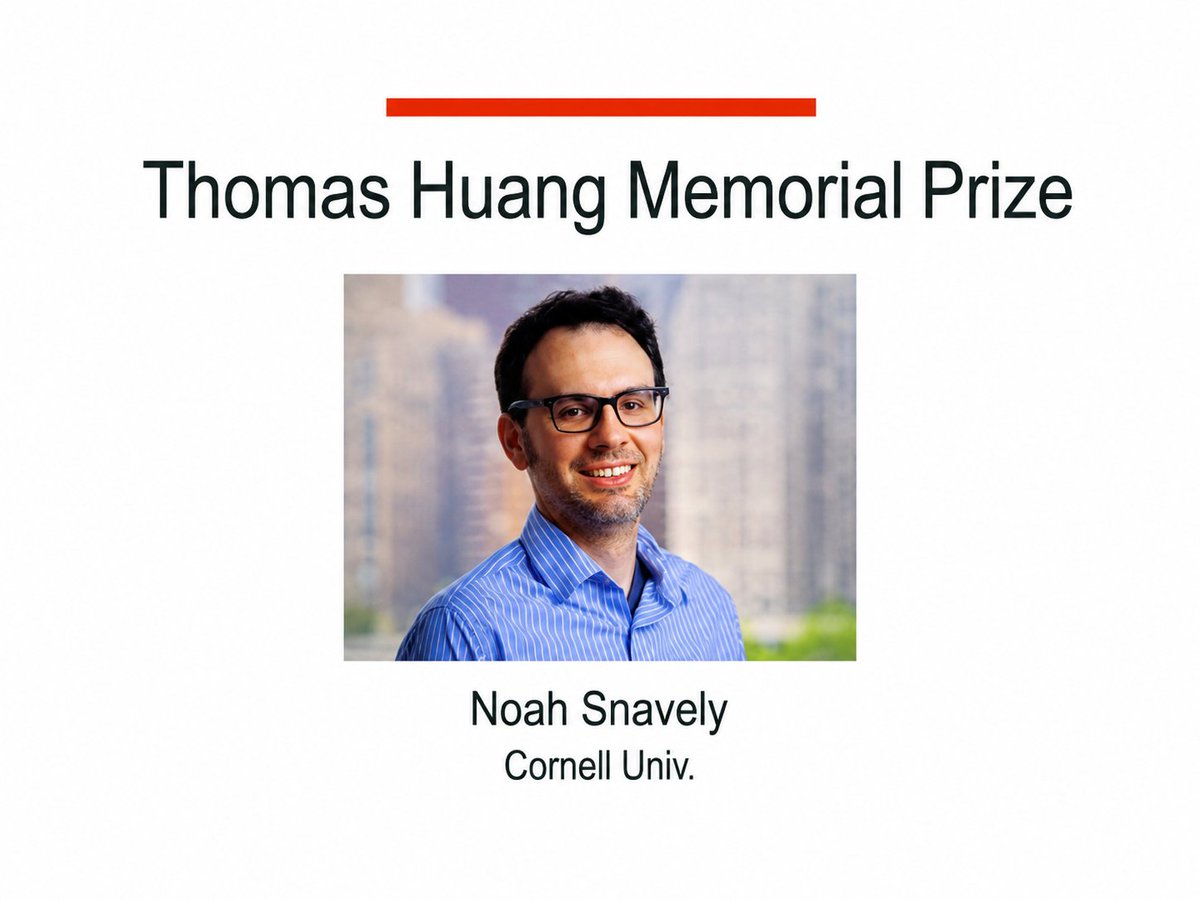
Congratulations to Noah Snavely @Jimantha from @Cornell receiving the 2026 Thomas S. Huang Memorial Prize at @CVPR — a well-deserved recognition of his impactful contributions to computer vision research and our community.
Remembering Tom & Margaret: https://t.co/WQeJLMEHZb