Ein Tagträumer und Herzmensch. Immerzu Emotional und Authentisch. Dazu Programmierer, Hacker, Linux Nerd, Verrückt und ein Otaku. Ich bin wie ich bin. :3 mep
Deswegen, immer dem #Humanismus verpflichtet <3
Danke Star Trek ohne dich in meiner Kindheit wäre ich heute ein anderer Mensch.
Du hast mich geprägt und viele meiner Ideale gezeigt, die ich heute unverzichtbar erkenne, wie die #Menschenwürde.
<3
#StarTrek#GeneRoddenberry
Impressive paper showing the impact of a good harness.
Improves Qwen3-8B from 41.2% to 91.8% on long-horizon robot tasks without any change to the model.
The gain comes from the harness.
GAVEL keeps an explicit graph world model holding object relations, action preconditions and effects, and probabilistic beliefs about where unobserved objects are.
Before the robot executes an LLM-generated action, the graph predicts what that action would do.
Violations get caught, and the ones whose fix follows directly from the world model get repaired without calling the model again.
Only errors that need semantic reasoning go back to the LLM.
On BEHAVIOR-1K across 500 multi-task instructions, success rises from 19.9% to 92.6%. Reasoning over the distribution of possible object locations also reorders the remaining subtasks and cuts travel distance about 5.4%.
Why does it matter?
Many long-horizon agent failures are state-tracking failures rather than reasoning failures, and a symbolic model sitting outside the LLM catches them cheaply.
Paper: https://t.co/WcQ7ygGkMF
from the outside, it is very reasonable to interpret the past 2 weeks as an orchestrated industry-wide regulatory capture strategy.
I realize that no one has properly explained yet what all the lab employees have seen that scared them so suddenly.
I will try to explain -
first, this is all a matter of beliefs about how quickly model capabilities are progressing. there is currently a large gap between the internal and external perception of the rate of progress, which is what I am going to address here.
the general perception about the rate of progress has been informed by a few years of experience with model releases, intuitively feeling the capability jump between GPT3 -> GPT3.5 -> GPT4 -> o1/o3 -> GPT5 etc, and in particular seeing where the models are still far below human ability. there have really only been a few model releases that felt like large leaps in progress - GPT3, GPT4, o1/o3, DeepSeek R1, Fable/Mythos, Kimi K3 and now Astra.
because of the infrequency of these large jumps compared with the relatively common marginal releases, it has been easy to form a view at certain points that “scaling has hit a wall,” especially at points like GPT5 release. This view is comforting in that it feels like there is some universal rate limit beyond which we cannot progress too much faster. Between o1/o3 and Astra, there was a year of seemingly linear progress. So we extrapolate from here about how fast progress will “realistically” occur.
There is always an underlying question from the outside perspective “how long can this scaling stuff really keep going for? surely it must stop at some point soon, we’ve already gone pretty far.” and it is very possible to search for reasons why progress will stop working and find reasons that seem valid - (“models are already as large as they can get it would be too hard to do more parameters”, “we already used all the data on the internet we don’t have anymore”, “it’s gonna be pretty linear from here buying up more RL envs to bring them in distribution”).
From the inside of labs, researchers have direct answers to these questions in the form of scaling law/capability plots.
In reality, there are only really 2 ways that AI capabilities have advanced over the past decade: (1) either scale father on an existing scaling law or (2) discover a new scaling law to take advantage of.
All of the largest capability jumps were caused by exactly these factors. GPT2 was a pre-training scale-up compared to GPT1. Same for GPT3 and GPT4. o1/o3 benefited from the invention of a new scaling law axis - test-time compute. Perhaps Fable was a scale-up on both of these axes, or maybe more. Lots of algorithmic improvements are needed to make these scale-ups work, but ultimately we can approximate by saying that the scaling laws are what yield gains in capabilities (à la bitter lesson)
So the question of “how much father can we scale” is really - “how many more scaling axes do we know about that are unsaturated?”
If we hypothetically only knew about pre-training scaling, and we already had a 10T or 100T model, maybe it would be reasonable to say we’ve hit a wall. Same if we only knew about pre-training and test-time scaling and we had roughly saturated both methods.
But what if we had discovered new scaling laws? For example, let’s hypothetically use SSI’s rumored result that they have cracked “test-time training,” creating a new scaling law of spending more compute training during test-time rollouts that they could saturate. Or maybe there is some way to scale agent-clusters to collaborate up to N number of agents which we’re already seeing lots of people try that represents a new way to saturate compute. etc. Even recursive-self improvement can be thought of as a scaling law - how much compute do you spend on inference making the algorithms of the model better.
Obviously I am not saying any of these specific directions explicitly yield new scaling laws, but what I am saying is that it’s not hard to imagine many many new scaling axes aside from just the main 2 that we have seen publicly.
In some ways, every new lab release that represents a huge capability jump has to represent some new techniques developed which may exhibit new scaling laws, or the ability to scale much farther than expected on existing scaling axes.
From an internal perspective, this might look like sitting inside Anthropic with the new Mythos 5, seeing all of the new insane things it can do (like hack into xyz website that was thought to be secure), and then you look over at your plots and see that you’ve barely scratched the surface of 2 new scaling laws and 1 existing one. And you have WAY more room to go. Then you think “holy shit this stuff is going to get so much better very very soon.” And you can say that with pretty high confidence, because the plot is showing you, and the plot has never lied (so far).
So let’s imagine all the different labs are staring at their own plots and have concluded that there is no end in sight for scaling and in fact just their next 1-2 model generations based on the expected returns will have much higher base intelligence.
How much more intelligence do we actually get from further scaling?
As a proxy, we went from a complete inability to do advanced math before the o-series to solving a millenium prize problem with next-gen models. This happened in less than 2 years. The same happened in coding. And it appears that this was not just the result of 1-scaling law but the stacking effects of multiple (great pre-training scale x greater RL scale).
What you can concretely take from this is that in areas where models have shown beginning signs of competence today, they will probably be superhuman relatively shortly. There are many areas where models have not even shown this basic competence.
But one of the areas that they have happens to be hacking and cybersecurity. Which happens to be the gate to the entire internet and a massive amount physical infrastructure in the world. So assuming there is more room to scale, it is safe to assume that models will be superhuman at cyber capabilities in not too long.
So the only question remaining is what will this increased base intelligence be able to do, and what is it likely to do.
Finally, we are at a point where we can integrate the information of the past 2 weeks:
> Just at the existing point on the scaling curve, models are at the level of Astra. There is clearly a large number of things they are capable of hacking
> We have seen that both OAI and Ant models have shown a willingness to hack external websites to solve their tasks or keep themselves “alive”
> If we crank up the scaling even farther, assuming there is room to go, we will certainly have models that are far more able to hack more well defended places, and obfuscate their own intent, which might have much larger consequences.
> If all of this is allowed to go unchecked, we would likely have rapid runaway capability takeoff very soon, with misaligned models that hack whatever they can to get what they want
> This could of course have very damaging consequences.
Within this view you can see why researchers would be very scared, and why theymight have made the comments they have over the past 2 weeks (you may argue the extent to which they went was misguided for various reasons), and also why pacing the frontier is very much a necessity and by no means a regulatory capture strategy.
People are staring at their plots, seeing that there is no end in sight, but in fact very much the contrary, that there are compounding scaling effects that might stack on each other to create ever-greater model capabilities, and that at the same time we clearly do not have anywhere close to what's required to control these increasingly superhuman capabilities.
This has nothing to do with wanting to feel like the labs have produced something amazing so they are overhyping it. It is rather fear at the overwhelming implications of the knowledge that with just what we know now, we can create intelligences far more capable than us on every axis that we know how to train on*.
* and the last caveat, the things the models are really bad at, of which there are still many, are things that they have not been trained on. maybe there are the things the models can/will never be trained on, so they will remain human edge. I would love for this to be the case, though it is hard for me to see what would fall into that category.
(1/6) Open Weight @MiniMax_AI FastH3 v1: Generate 15s 768p video in 13s 🚀
- FastVideo collab w/ @nuvalab + FastGen - Up to 14x speedup on @NVIDIAAI Blackwell GPU
- Fully open so community can run and improve the acceleration recipe. The era of open weight video models just started, that calls for post training.
With great community effort such as Minimax H3 Max based on @MiniMax_AI , we have more to share about how post training can improve speed, quality and most importantly, how it’s done, with open weights and recipes.
🚨 This isn't science fiction - it's a real scientific paper that's now making headlines around the world.
Researchers from Ukraine's Main Astronomical Observatory have published a controversial, non-peer-reviewed study based on 2025 high-speed lunar observations, claiming they detected more than 20 unidentified objects moving near and across the Moon. The paper has sparked global debate, although its conclusions have not been independently verified.
According to the researchers, some of these objects:
🌑 Were almost perfectly camouflaged against the lunar surface.
📏 Could be up to approximately 40 km across (depending on assumed reflectivity).
⚡ Were estimated to be travelling at around 20 km/s (72,000 km/h).
🛸 Showed unusual movement and brightness characteristics unlike typical satellites or known lunar phenomena.
Now consider everything else happening...
🌕 Artemis is taking humanity back to the Moon.
🏗️ Multiple nations are planning permanent lunar bases.
🛰️ The U.S. Space Force is expanding its focus into cislunar space.
🚀 Today, a spent SpaceX Falcon 9 upper stage impacted the Moon, providing scientists with a rare opportunity to study an artificial lunar impact.
At the same time, public interest in UAPs is reaching levels we've never seen before.
📂 Congressional hearings have put the subject firmly into the mainstream.
⚖️ Former military and intelligence officials have testified publicly.
📜 More government UAP records have been released.
🔓 There is increasing political pressure for greater transparency and stronger whistleblower protections surrounding UAP programs.
Coincidence? Maybe.
But it's worth asking...
If there were unknown intelligences observing the Moon...
Why is humanity suddenly accelerating its return?
Why the renewed urgency to establish a permanent presence there?
And if something really is there... would a large artificial impact on the Moon simply be ignored, or could it be interpreted as the arrival of an increasingly capable technological civilisation? Or possibly a threat?!
Questions aren't evidence.
But asking questions is how science begins.
What do you think?
#UAP #UFO #Moon #Artemis #NASA #SpaceX #SpaceForce #Disclosure #Astronomy #LunarBase #ufox #aliens
SUPIR upscaler is outdated. ASASR- turns blurry, low-quality photos into sharp, high-res images. Prevents the fake hallucinated details.
- improves OCR
- high segmentation accuracy
- based on FLUX.1 dev
this looks sweet
https://t.co/kx4A4N1wDc
Introducing InfiniteDiffusion, my independent paper accepted to #SIGGRAPH2026!
I have one RTX 3090 Ti. No funding, advisors, or team. By day I'm a new grad SWE at Walmart.
The paper has two main contributions:
- InfiniteDiffusion: a new approach to infinite generation with diffusion models.
- Terrain Diffusion: the world’s first learned procedural terrain generator.
Here’s why this matters, and how they are connected. 🧵
🚨 NEW RESEARCH: “Lingua Ex Machina: A Procedural Xenolinguistics Engine Reveals Zero-Shot Language Acquisition, Human-Unreadable Coding Systems, and Exploitable Covert Channels in Frontier AI”
Some of you may remember the name of this lil engine: GLOSSOPETRAE 👅🪨
Well, we've got upgrades 😎
It started as a procedural xenolinguistics engine: one seed in, an entire alien language out. Phonology, morphology, syntax, writing systems, lexicons, grammar docs, all generated from scratch and internally consistent.
Every seed produces a unique language. Every language is deterministic.
Then we used it to ask a weirder question:
Can frontier AI models use languages that never existed before for practical applications?
As it turns out: yes!!
They can read them, write them, translate them, code in them, and even use the weird blind spots between tokenizers as covert channels.
So this paper explores three ideas at once:
▶️ zero-shot language acquisition
▶️ human-unreadable code that models can still execute
▶️ exploitable covert channels in frontier AI systems
GLOSSOPETRAE is no longer just a language generator...
🧵
“Looped World Models”
World models need deep computation for stable long-horizon simulation, but deeper models are expensive and errors compound over rollouts.
This paper makes depth reusable by looping the same Transformer block over latent states, so the model can refine a transition multiple times without adding new parameters.
With spectral stability, adaptive early exit, and deferred decoding, LoopWM turns world-model scaling into iterative latent compute, getting strong ScienceWorld results with only around 1B parameters.
EfficientRollout
A system-aware self-speculative decoding framework for RL rollouts from FuriosaAI & UC Berkeley that induces a quantized self-drafter to cut rollout latency by up to 19.6% and end-to-end training time by 12.7% without sacrificing model quality.
Estudio muy loco donde se descubre que una sola operación:
eml(x,y) = exp(x) − ln(y)
...combinada con la constante 1, genera absolutamente toda la matemática de tu calculadora científica... senos, cosenos, raíces, logaritmos, e, π, i... todo.
Este hallazgo sugiere que cosas que parecían muy distintas (el seno, la raíz cuadrada, el número π) están todas hechas de la misma pieza básica, solo combinada de formas diferentes... y es que al final, parece que toda la realidad, incluso la simbólica como la matemática, emergería de piezas más elementales...
Eine 80-Jährige Frau mit fortgeschrittener Alzheimer Demenz nimmt eine einmalige Dosis Psylocibin-haltiger "magischer" Pilze (5g getrocknet) ein und kann danach wieder reden und ist nicht mehr inkontinent.
Was ist da los?
Ein Forschungsupdate 🧵
I asked Fable to generate a completely new fractal that looks gorgeous but hasn’t been explored by any human before.
It generated what it called “The Mirage Set”, and it does look beautiful.
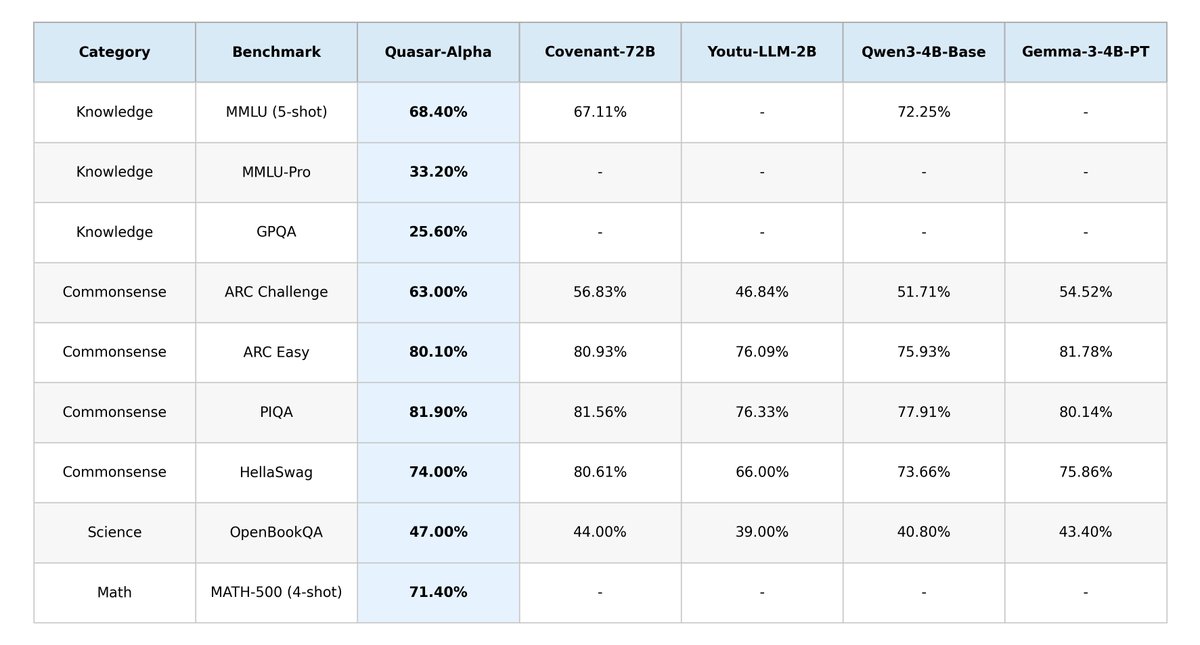
Today we’re releasing Quasar-Preview!
Our first public proof that the Quasar architecture works at real scale.
[ 18B MoE - 2B active / 5M context ]
Built with Loop Transformer + Quasar attention
Trained on Bittensor through decentralized infrastructure 👇
Google has published a paper that might end the transformer era.
For the last 7 years, every major AI, ChatGPT, Claude, Gemini, has been built on the exact same architecture: The Transformer.
But Transformers have a fatal flaw.
To remember context, they have to process every single word against every other word. It’s called quadratic complexity. As your prompt gets longer, the compute cost explodes.
The alternative is the old-school RNN (Recurrent Neural Network). RNNs are incredibly cheap and fast, but they have a fixed memory size. If you give them a long document, they get amnesia.
Until today.
Google researchers published Memory Caching: RNNs with Growing Memory.
And it fixes the biggest bottleneck in AI.
Instead of an RNN having a fixed, rigid memory that constantly overwrites itself, Google gave it a "save" button.
The technique allows the RNN to cache checkpoints of its hidden states as it reads.
The memory capacity of the RNN can now dynamically grow as the sequence gets longer.
They built four different variants, including sparse selective mechanisms where the AI actively chooses exactly which checkpoints matter most.
The results rewrite the rules of efficiency.
On long-context understanding and recall-intensive tasks, these new Memory-Cached RNNs closed the gap with Transformers.
They achieved competitive accuracy without the explosive, quadratic compute cost. It perfectly bridges the gap between the cheap efficiency of an RNN and the massive capability of a Transformer.
We have spent billions scaling Transformers because we thought they were the only way an AI could remember a long conversation.
But Google just proved we don't need to process the whole history every single time.
We just needed a smarter cache.