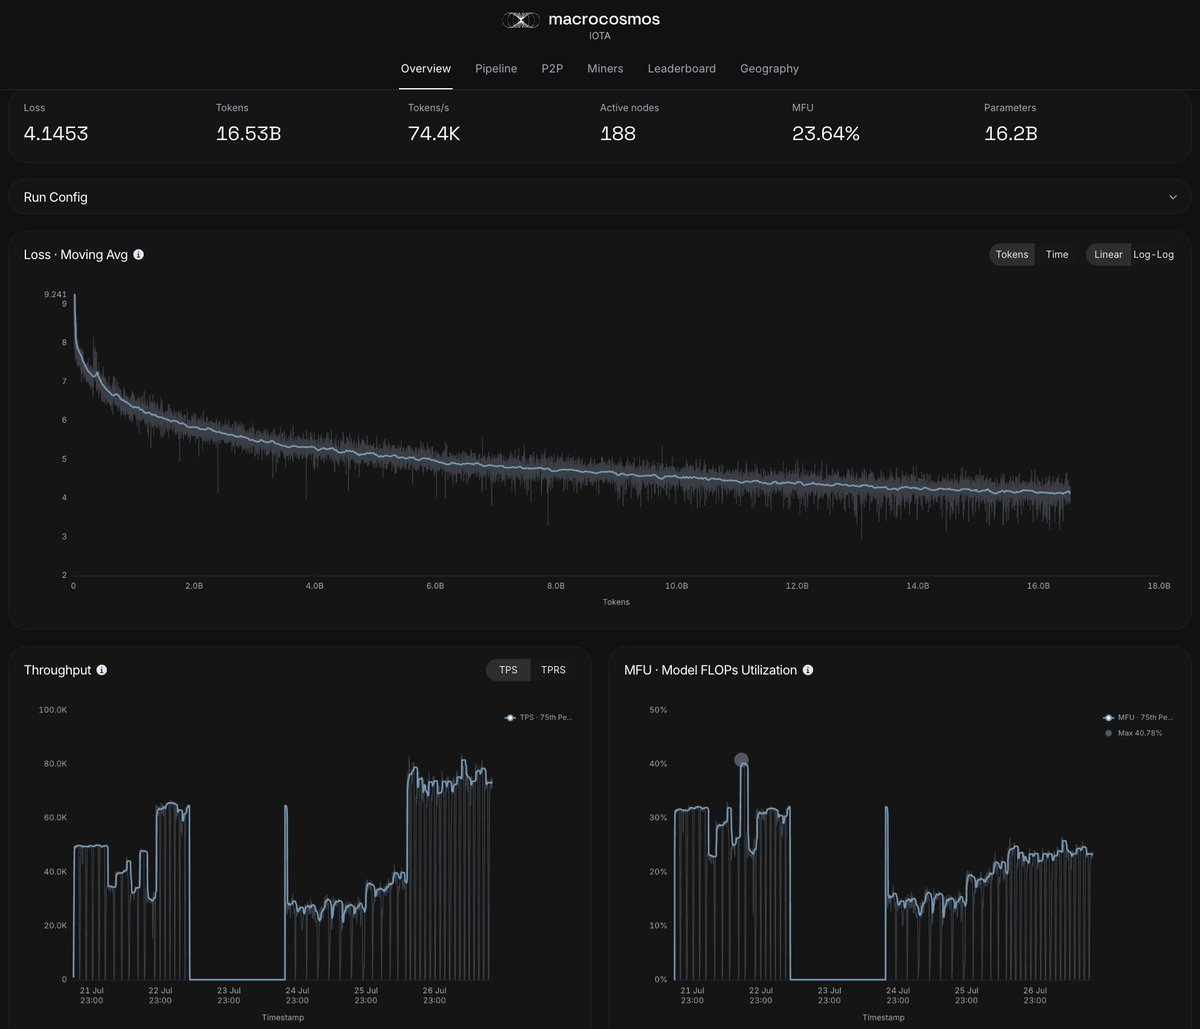
I cannot overstate how excited I am to share this with the world. 16B trained over the internet by 4090/5090s with help from @green_compute_ and @TargonCompute. MFUs upwards of 40%, with compute all the way from the USA to Hong Kong. @IOTA_SN9
https://t.co/rXA9XMVxvR
@maxrumpf ok dumb guy question here but Google has been optimizing search for decades. I wouldn't presuppose any frontier model is better at search than their stack of algos they use. Is there a way to benchmark against parts of their / non-llm based search?
You could argue that most of what we do as humans is long-horizon reasoning, and we need more environments that try to understand this problem.
Results from @oroagents show that our frontier models can collapse in this domain. SOTA isn't as good as it may seem!
We put 16 AI models in charge of buying for a produce wholesaler, every morning for 90 days. Only 3 made more money than a simple reorder formula.
The models noticed their mistakes and wrote them down, but then they mostly kept making them.
Abolish the war machine.
Remember all the victims of war.
Let us work towards a world free of war, conflict, and genocide.
Learn more here:
- https://t.co/ZXYYlh6A07
- https://t.co/M8nXNu2NwF
- https://t.co/JmVGKPcCIo
Our latest competition solves a practical problem for our friends at @urnetwork + their 350k monthly users:
They set a goal: *reduce p95 latency by 20%*
End of round 1: *top agent reduced latency by 63%*
+ 14 independent solutions exceed their stated goal
The most impressive part is that the top solution opens a new door to many further innovations.
Only 5 rounds left.
Token usage at all-time highs. Politicians who can barely open a PDF are holding emergency meetings to slow it down.
AI Prohibition is coming. History tells us how that ends.
You can’t regulate away demand, and I think some of it finds a home in permissionless protocols.
✅ BENCHMARKED: IOTA Decide 4B v0.4, an open-weight decision model from @MacrocosmosAI, running on my 64GB M5 Pro Mac mini
You hand it a state (a ticket, a policy, an agent trace) plus questions and one forward pass returns a probability for every answer. With their bundled loader on the Mac's GPU in full bf16, it loaded in 12.8 seconds and peaked at 10.7 GB.
Short ticket, about 130 tokens:
- yes/no: 88 ms
- 3-way choice: 105 ms
- 3-level score: 88 ms
That's about 11 decisions a second on a desktop Mac.
Their own example, a refund asked for 45 days after purchase on a 30-day policy, answered all 3 questions in 277 ms with the same answers on every repeat:
- eligible: 2.2% yes
- route: refunds team, 86%
- urgency: Low, 63%
Longer states take about 0.6 s per decision at 1k tokens and 2.6 to 3.0 s at 4k.
These numbers are the floor. On Mac its linear-attention layers still run on PyTorch's generic kernels, so an optimized Metal path should make it faster. Their 33 ms figure is on a dedicated GPU.
If you're building agents, about 90 ms a decision is fast enough to check a policy before an agent acts or route tickets on your own machine, with no per-call bill. I didn't benchmark accuracy, but it gave the same answers on their refund example every run.
based ai lab
- Trained distributed, end to end, using streaming DiLoCo across 16 RTX A4000s.
- Training data came from our own stack: we generated and labelled it with distributed batch inference
Decentralized training on Bittensor is now delivering competitive open models.
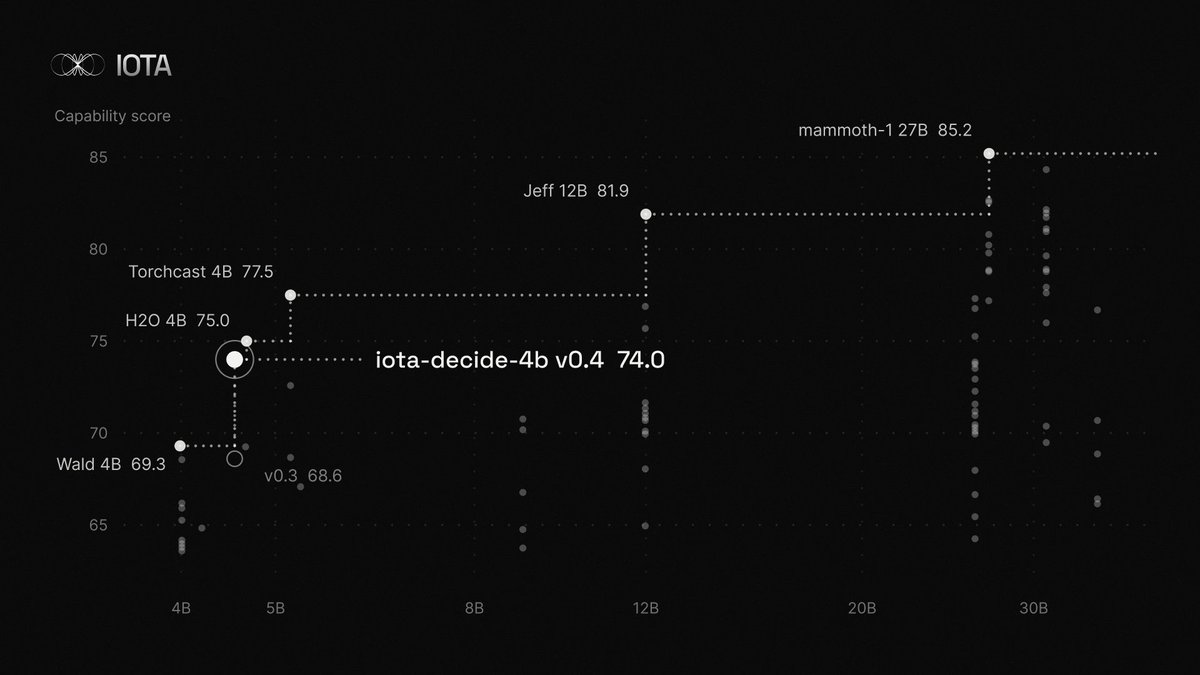
@MacrocosmosAI just released IOTA Decide 4B, fine-tuned across 16 GPUs around the world and open for anyone to build on.
We've always believed that distributed technologies can be indistinguishable from their centralized counterparts.
Our first public model shows that they can be pareto optimal too.
Introducing IOTA Decide 4B.
Introducing IOTA Decide 4B, our first public model.
Pareto optimal. Built different.
Trained across globally distributed GPUs with our SDK.
Open weights, Apache-2.0.
🤗 https://t.co/cFlqLmcnop
Nobody should care whether a model was trained distributed. They should care that it’s useful.
We’ve been using models we trained across distributed GPUs, and they’re very good. Sharing one soon.
@_arohan_ We at @MacrocosmosAI has been working on this at scale for ~2 years doing distributed pretraining and RL, so great to see more content in this space. Distributed will become mainstream :)
Local inference isn't a terrible allocation of resources if you have technology that can unite distributed, heterogenous, and idle (re, off 95%) of the time compute to do frontier scale workloads.
That's the core of our thesis - and more broadly that maximising utilisation is the core next step in the AI race.
Crazy moment when your old subnet (25) slot creates a competition to improve their technology on your other subnet slot (1)
Congrats to @urnetwork! Exciting to see
We're excited to announce our newest external competition with @URnetwork, which went live today!
UR subnet is a privacy network built on Bittensor. Their decentralized VPN network serves X users every day, and their system is powered by a set of powerful traffic routing algorithms.
The URnetwork Latency Competition has one goal: make the network faster. A single Go file, one patch. Approved winners are merged into URnetwork's codebase and become the next epoch's baseline. Improvements compound.
Docs and competition page in the links below 🧵:
We're excited to announce our newest external competition with @URnetwork, which went live today!
UR subnet is a privacy network built on Bittensor. Their decentralized VPN network serves X users every day, and their system is powered by a set of powerful traffic routing algorithms.
The URnetwork Latency Competition has one goal: make the network faster. A single Go file, one patch. Approved winners are merged into URnetwork's codebase and become the next epoch's baseline. Improvements compound.
Docs and competition page in the links below 🧵: