Silicon Valley shows you everything at the extremes: a lot of great people, a lot of true a**holes. Ask anyone who's met Jensen Huang which bucket he's in. Not saying his sins are mild. Just that of everyone here who deserves this kind of fall, he's near the bottom of the list.
Sometimes it’s hard for me to understand why Dario gets so much unjustified hate, from scientists and non-scientists alike, for saying diseases like cancer will become relics of humanity’s past in a decade or so.
If you’ve done science both pre- and post-AI, you know how absurdly productive and fun it has become. Seeing model capabilities grow like this just gives me hope.
The future is going to be fun. And you know... maybe once we really pull this off, the best of humanity’s effort will have a different agenda than relieving our sufferings from diseases!
@melvinjohnsonp@danielmckinn0n It's also doing very well on our private benchmarks at Tahoe too on a subset of our tasks with experimentally verifiable rewards. Big step up from Argon. Good work :)
(some more context: https://t.co/7GI5ok116M)
What makes a biological reasoning task verifiable? Our team @tahoe_ai has spent the last few months on that question and landed on one conviction: for human-difficult tasks with verifiable rewards, the answer key has to come from ground-truth experimental data.
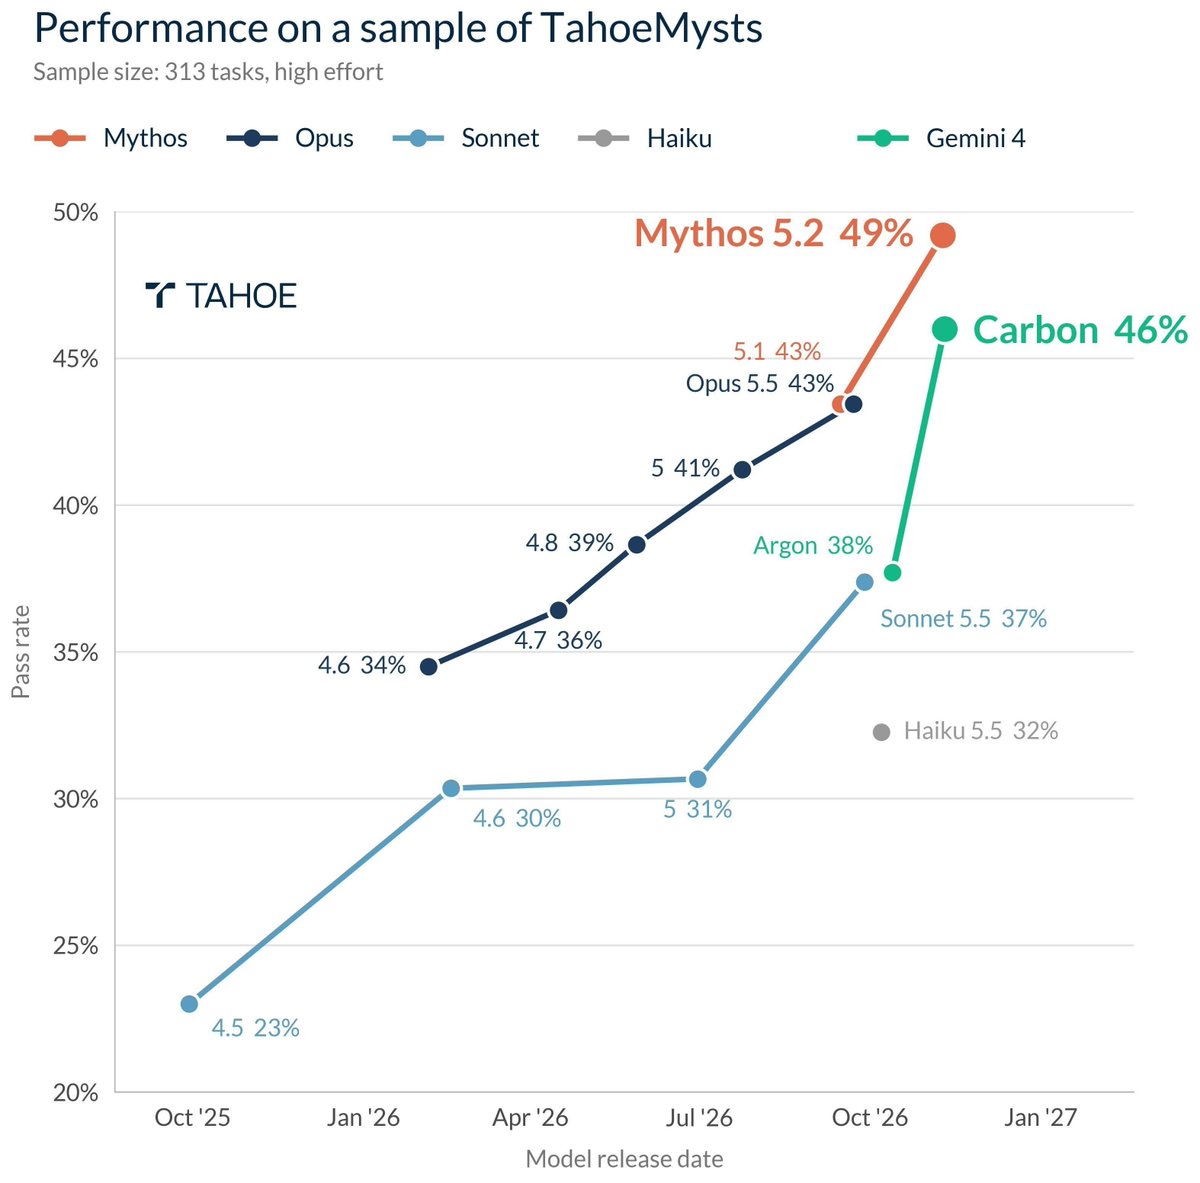
Along the way we built thousands of such environments, which we call TahoeMysts, and we use them to evaluate frontier models (among other things). Every so often a new model produces a big jump, and it is always exciting. Today is one of those days: @claudeai Mythos 5.2!
We will say more about this work in the future. In the meantime, take a look at our results today.
Evaluating a model’s ability to tackle open-ended tasks in biology (and science more broadly) is hard.
Expert-curated tasks leave a lot wanting. Even setting scaling aside, it’s hard to find an outlier scientist impressed by their difficulty or grading rubric.
I’ve been thinking about a qualitative framework that would precede the ultimate validation outcome: three levels of model / harness output, judged by a superstar expert.
Tier 1: Reliable. “OK, this is solid. It doesn’t f*** up.”
Gets the fundamentals right.
Tier 2: Legit & interesting. “Well-reasoned, well-synthesized, genuinely interesting. But I could have gotten there.”
Rigor plus non-trivial synthesis.
Tier 3: Outlier insight. “F***, I wish I’d thought of that.”
Well-reasoned and surprising. Reachable from the evidence, yet I didn’t reach it. Worth investing in proper validation.
Something has shifted in the frontier! TahoeMysts, Tahoe's internal eval, is not easy (as evident from the pass rates here). For most of the year models crept up a point or two per release... the best ones still failing close to two-thirds. But look at Mythos 5.2, and especially Gemini 4 Carbon: 38% to 46% in one jump. These lines are almost vertical!
Something has shifted in the frontier! TahoeMysts, Tahoe's internal eval, is not easy (as evident from the pass rates here). For most of the year models crept up a point or two per release... the best ones still failing close to two-thirds. But look at Mythos 5.2, and especially Gemini 4 Carbon: 38% to 46% in one jump. These lines are almost vertical!
Big news! Full article below 👇
Fauna Bio’s rare biological data and powerful AI approaches have uncovered another promising obesity drug target. @EliLillyandCo has made an additional milestone payment for a second target identified through Convergence™ AI. Huge congratulations to the @faunabio team 🚀
https://t.co/JPQ0nLhCTa
What makes a biological reasoning task verifiable? Our team @tahoe_ai has spent the last few months on that question and landed on one conviction: for human-difficult tasks with verifiable rewards, the answer key has to come from ground-truth experimental data.
Along the way we built thousands of such environments, which we call TahoeMysts, and we use them to evaluate frontier models (among other things). Every so often a new model produces a big jump, and it is always exciting. Today is one of those days: @claudeai Mythos 5.2!
We will say more about this work in the future. In the meantime, take a look at our results today.
What makes a biological reasoning task verifiable? Our team @tahoe_ai has spent the last few months on that question and landed on one conviction: for human-difficult tasks with verifiable rewards, the answer key has to come from ground-truth experimental data.
Along the way we built thousands of such environments, which we call TahoeMysts, and we use them to evaluate frontier models (among other things). Every so often a new model produces a big jump, and it is always exciting. Today is one of those days: @claudeai Mythos 5.2!
We will say more about this work in the future. In the meantime, take a look at our results today.
Excited for the launch of Gemini for Healthcare!
We’re extending the Gemini agent with specialized healthcare skills and connectors to Epic, Optum, and more, built to support HIPAA compliance.
Instead of spending hours piecing together fragmented records and policies, care teams can offload the admin burden and get time back for what matters most: patient care.
What makes a biological reasoning task verifiable? Our team @tahoe_ai has spent the last few months on that question and landed on one conviction: for human-difficult tasks with verifiable rewards, the answer key has to come from ground-truth experimental data.
Along the way we built thousands of such environments, which we call TahoeMysts, and we use them to evaluate frontier models (among other things). Every so often a new model produces a big jump, and it is always exciting. Today is one of those days: @claudeai Mythos 5.2!
We will say more about this work in the future. In the meantime, take a look at our results today.
you're touching on a very important point. In fact just using the experiment as the ground truth is not enough. Designing the eval / task such that the answer is not a function of experimental noise and is a clear “truth” is the key aspect. That's a major part of what we have been working on.