People are underestimating the importance of this news. Whatever we have seen till now, is the same old Robots-are-going-to-kill-us reporting. It's different. It's a step closer to general purpose AI.
It is not a question of sentience, but about solving humanities all problems. https://t.co/DMiOYCEIFV
1997: World's best human chess player gets destroyed by computer.
2017: World's best chess computer gets destroyed by Artificial Intelligence program that had only learned about chess a few hours earlier. https://t.co/fjKhoEkicW
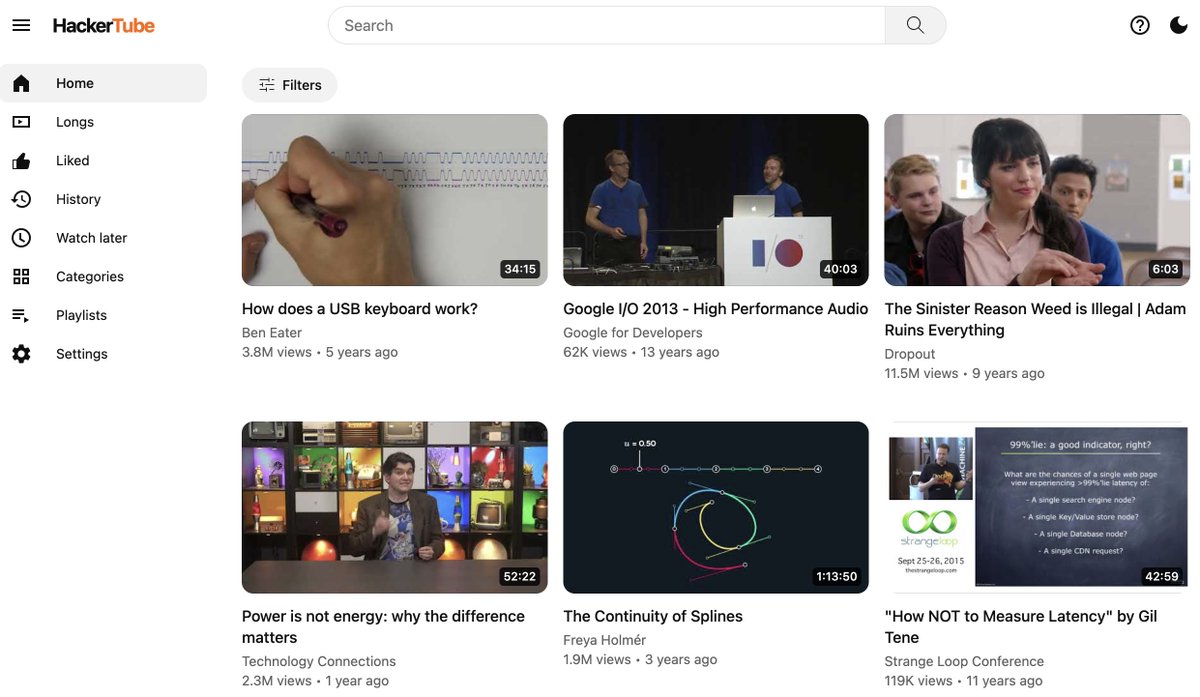
Weekend hack: HackerTube. I was annoyed with YouTube's recommendations so I had Claude filter down 43M comments over 20 years of HN to 6,454 videos that keep being recommended. *Significantly* better viewing experience, ~2 hours with Opus 5.5:
https://t.co/JIhXN7OSh1
- Excellent recs without any logins (state is kept in local browser session)
- Thumbnail is a representative frame from middle of the video instead of the super duper A/B test hyper-optimized user uploads
- Underlying data from the comment analysis as one zip file, point your Claude at it and ask for your own version
- HackerTube Longs ✊
A bit more on the process:
I use Claude Code (desktop app for Mac), Opus 5.5 on Medium effort as my default. I only talk to Claude and have it do everything, the only "manual work" I helped with in tandem was in the browser (reminiscent of MenuGen): 1) I had to create some kind of API key from Google Cloud UI to query YouTube for video metadata, 2) I booted up a VPS box for serving and 3) I bought the domain name. Once the box was up I gave Claude the IP and told it update, secure, harden, deploy and optimize the code, and it did the whole thing.
Many awesome projects that would have normally taken weeks/months even can now be few-shotted for breakfast. What else are we not thinking of.
Passkey UX is broken.
A bunch of apps ask me to create a passkey while I'm using my laptop. Sure, create a passkey, here's my fingerprint.
Then when it wants you to use a passkey, it opens a QR code and says to scan with your phone.
But the passkey is on my laptop.
- Drafted a blog post
- Used an LLM to meticulously improve the argument over 4 hours.
- Wow, feeling great, it’s so convincing!
- Fun idea let’s ask it to argue the opposite.
- LLM demolishes the entire argument and convinces me that the opposite is in fact true.
- lol
The LLMs may elicit an opinion when asked but are extremely competent in arguing almost any direction. This is actually super useful as a tool for forming your own opinions, just make sure to ask different directions and be careful with the sycophancy.
@IndiGo6E what’s up with your baggage services at Ahmedabad airport?
*Overworked Staff*
They don’t have time to answer phone calls. Delayed bag receipt that should take 2 mins to generate took 15 mins per customer because staff was getting calls continuously. Staff really wants to help but they are burdened by a thoughtless process (or lack of).
*Convoluted Process*
Delayed baggage seems to be a very common occurrence by the amount of passengers I saw in line at your baggage service desk. You should have a streamlined process that reduces burden on your staff.
*Delivery Vendor*
They want to finish the delivery asap which means they call the customer at 2AM to see if they can deliver. I understand they’d like to get this done but it should be customer’s preference if they want the delivery at all cost or with reasonable means.
This post is only to highlight a company’s failure and not individuals’. Everyone I have encountered were very courteous and always wanted to do the right thing.
@MoCA_GoI@DGCAIndia
@IndiGo6E what’s up with your baggage services at Ahmedabad airport?
*Overworked Staff*
They don’t have time to answer phone calls. Delayed bag receipt that should take 2 mins to generate took 15 mins per customer because staff was getting calls continuously. Staff really wants to help but they are burdened by a thoughtless process (or lack of).
*Convoluted Process*
Delayed baggage seems to be a very common occurrence by the amount of passengers I saw in line at your baggage service desk. You should have a streamlined process that reduces burden on your staff.
*Delivery Vendor*
They want to finish the delivery asap which means they call the customer at 2AM to see if they can deliver. I understand they’d like to get this done but it should be customer’s preference if they want the delivery at all cost or with reasonable means.
This post is only to highlight a company’s failure and not individuals’. Everyone I have encountered were very courteous and always wanted to do the right thing.
@MoCA_GoI@DGCAIndia
Excited to release new repo: nanochat!
(it's among the most unhinged I've written).
Unlike my earlier similar repo nanoGPT which only covered pretraining, nanochat is a minimal, from scratch, full-stack training/inference pipeline of a simple ChatGPT clone in a single, dependency-minimal codebase. You boot up a cloud GPU box, run a single script and in as little as 4 hours later you can talk to your own LLM in a ChatGPT-like web UI.
It weighs ~8,000 lines of imo quite clean code to:
- Train the tokenizer using a new Rust implementation
- Pretrain a Transformer LLM on FineWeb, evaluate CORE score across a number of metrics
- Midtrain on user-assistant conversations from SmolTalk, multiple choice questions, tool use.
- SFT, evaluate the chat model on world knowledge multiple choice (ARC-E/C, MMLU), math (GSM8K), code (HumanEval)
- RL the model optionally on GSM8K with "GRPO"
- Efficient inference the model in an Engine with KV cache, simple prefill/decode, tool use (Python interpreter in a lightweight sandbox), talk to it over CLI or ChatGPT-like WebUI.
- Write a single markdown report card, summarizing and gamifying the whole thing.
Even for as low as ~$100 in cost (~4 hours on an 8XH100 node), you can train a little ChatGPT clone that you can kind of talk to, and which can write stories/poems, answer simple questions. About ~12 hours surpasses GPT-2 CORE metric. As you further scale up towards ~$1000 (~41.6 hours of training), it quickly becomes a lot more coherent and can solve simple math/code problems and take multiple choice tests. E.g. a depth 30 model trained for 24 hours (this is about equal to FLOPs of GPT-3 Small 125M and 1/1000th of GPT-3) gets into 40s on MMLU and 70s on ARC-Easy, 20s on GSM8K, etc.
My goal is to get the full "strong baseline" stack into one cohesive, minimal, readable, hackable, maximally forkable repo. nanochat will be the capstone project of LLM101n (which is still being developed). I think it also has potential to grow into a research harness, or a benchmark, similar to nanoGPT before it. It is by no means finished, tuned or optimized (actually I think there's likely quite a bit of low-hanging fruit), but I think it's at a place where the overall skeleton is ok enough that it can go up on GitHub where all the parts of it can be improved.
Link to repo and a detailed walkthrough of the nanochat speedrun is in the reply.
I got GPT-5 with ChatGPT code interpreter to hunt down the US Census numbers used by the recent Apollo AI adoption rate chart and then recreate that chart from a screenshot and the raw data using matplotlib in Python https://t.co/VovBQ2Dy0X
This is why it's important to surround yourself with people who can see the real you. If not, you might find yourself morphing your personality to match people's (incorrect) model of you, subconsciously hiding your real self away.
The election is over. If your side won, congrats. If your side lost, you’ll get ‘em next go round.
Now it’s time to get back to making life better for you & your people. Back to basics…
Move your body daily.
Feed it real food.
Prioritize rest.
Love your people.
Let’s go!!
In 2002, I was working for a nation-wide retailer. About 6 months after building a new store, my car broke down. I lived so far away from the store that I was only able to get two rides home from different colleagues. I ultimately took to walking 23 miles to work (each way) 🧵
I ran hundreds if not thousands of LoRA & QLoRA experiments to finetune open-source LLMs, and here’s what I learned:
1. Despite the inherent randomness of LLM training (or when training models on GPUs in general), the outcomes remain remarkably consistent across multiple runs.
2. QLoRA presents a trade-off that might be worthwhile if you're constrained by GPU memory. It offers 33% memory savings at the cost of a 33% increase in runtime.
3. When finetuning LLMs, the choice of optimizer shouldn't be a major concern. While SGD on its own is suboptimal, there's minimal variation in outcomes whether you employ AdamW, SGD with a scheduler, or AdamW with a scheduler.
4. While Adam is often labeled a memory-intensive optimizer due to its introduction of two new parameters for every model parameter, this doesn't significantly affect the peak memory demands of the LLM. This is because the majority of the memory is allocated for large matrix multiplications rather than retaining extra parameters.
5. For static datasets, iterating multiple times as done in multi-epoch training might not be beneficial. It often deteriorates the results, probably due to overfitting.
6. If you're incorporating LoRA, ensure it's applied across all layers, not just to the Key and Value matrices, to maximize model performance.
7. Adjusting the LoRA rank is essential, and so is selecting an apt alpha value. A good heuristic is setting alpha at twice the rank's value.
8. 7B models can be finetuned efficiently within a few hours on a single GPU possessing 14 Gb of RAM.
With a static dataset, optimizing an LLM to excel across all benchmark tasks is unattainable. Addressing this requires diverse data sources, or perhaps LoRA might not be the ideal tool.
Alibaba releases QwenLM-7B and Chat variant
Self-reported results: Beats Llama2 by a mile on math(GSM8K), code (HumanEval), Question Answering and QA (MMLU)
🤯 ~2x better than GPT4 on a variant of tool selection (e.g. AutoGPT) — 8.5% False Positive Rate, compared to GPT4's 15%
Commercially licensed if below 100M users
https://t.co/qKlWF7IQgB
It’s remarkable how people like @joerogan and @lexfridman are building absolute media empires by simply listening to people for once instead of cutting them off and consistently trying to shape a cohesive narrative
If you’re against abortion, don’t get one.
If you’re against contraception, don’t take any.
If you’re against same-sex relationships, don’t have one.
If you’re against same-sex marriage, don’t marry someone of same gender.
Do not impose your beliefs & religion on all Americans.
Some said an open-world experience this immersive wasn’t possible. But it’s already here. And you don’t even need silly VR headsets.
Introducing, ✨Icelandverse✨
#icelandverse