Best tools for Hyperliquid & PerpDEX traders PART II (+1 bonus)
Bookmark so you can come back to these tools whenever you need them
1) @hyper_bubbles | real-time interactive bubble chart for all Hyperliquid perp markets. Color-coded by performance, with live prices, clickable details, and direct links to trade
2) hyperfolio .xyz by @stableAPY | HyperEVM multi-wallet DeFi portfolio tracker. Track tokens, NFTs, protocol positions, yields/APYs, and transaction history by wallet address or .hl name
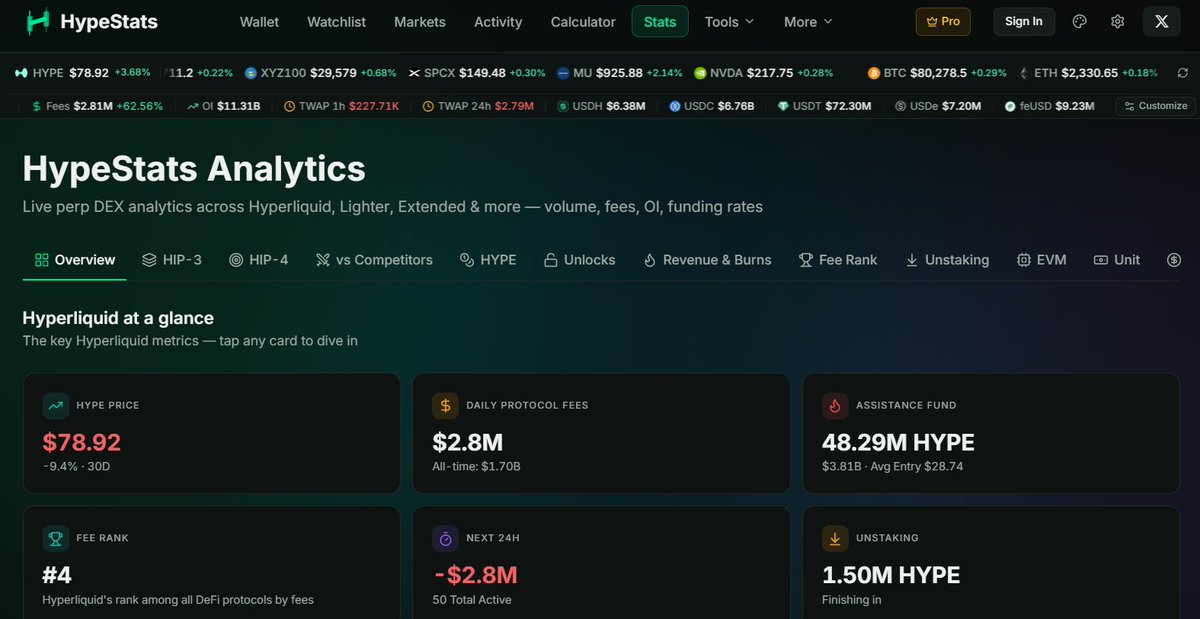
3) @HypeStatsx | all-in-one Hyperliquid portfolio and analytics dashboard. Track wallet positions (perps + HIP-3 + spot), fees, PnL, ecosystem stats, HIP-3 leaderboards, and an airdrop/FDV calculator
4) hypeburn .fun by @janklimo | live HYPE tokenomics tracker. Track burns, Assistance Fund buybacks, supply breakdown, revenue, and real-time charts
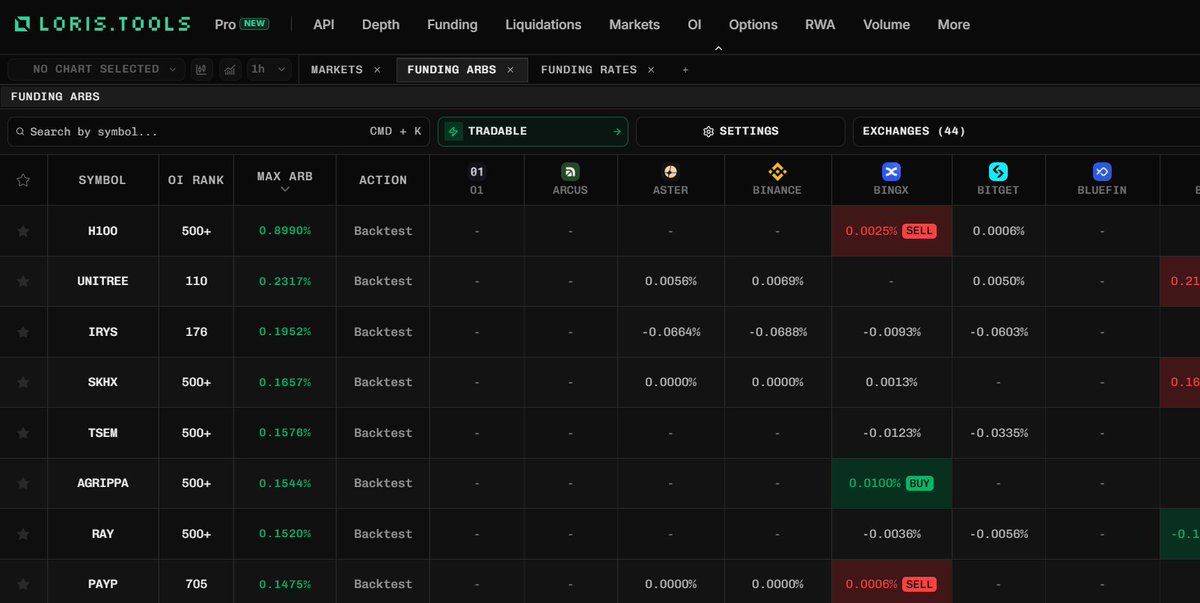
5) @LorisTools | cross-platform funding arbitrage scanner and pair trading terminal. Features dual order books, TWAP, portfolio tracking across Hyperliquid, Binance, Extended, and HIP-3 DEXs, plus an API
6) @liquidterminal | open-source Hyperliquid terminal and explorer. Explore markets, vaults, validators, HYPE supply and scarcity, portfolio margin, an ecosystem directory, and a wiki
These are just some of the tools people in the ecosystem use
If you use any interesting tools or have built one yourself - DM me
Tool websites are in the replies
Huge thanks to @flyest and the @oxleydotfun team for their donation to @liquidterminal.
They're building their own product on a tight budget and still chose to back an open source tool. That means a lot.
And thank you to everyone who donated before them. You are the reason Liquid Terminal is still standing today, free, open source, with no ads and no paywall.
@hypurr_co@shaundadevens@hufhaus9@ThatAIFreak and many more.
A big thank you as well to @hypedexer and @stableAPY for the data that powers so much of the terminal.
Your support goes straight back into the terminal: it gets upgraded every day to make the UI and the UX better, page after page.
Hyperliquid.
Kimi K3.1 vs Qwen 4: 3D helicopter
Same prompt, takeoff/land, 3D assembly and exploded views, very similar gen time at around 15-20 minutes for both
China are not playing games anymore, these are very strong
if your local inference machine is way to loud =>
my local ai box sounded like a freaking airplane and while cutting watts was working it was also killing performances
my buddy told me to lock gpu clocks instead and boyyy that was the missing piece
> 1500 mhz on the 3090
> 1800 on the 3080 Ti
my two coding agents went from 67 to 62 tok/s each, and solo-agent is still over 100+ tok/s
the whole box dropped from 452 W to 358 W and the 3090 fan from 91% to 48% and that's the blessing ngl
quiet enough to sit next to, that's what I actually needed
if your local inference machine is way to loud =>
my local ai box sounded like a freaking airplane and while cutting watts was working it was also killing performances
my buddy told me to lock gpu clocks instead and boyyy that was the missing piece
> 1500 mhz on the 3090
> 1800 on the 3080 Ti
my two coding agents went from 67 to 62 tok/s each, and solo-agent is still over 100+ tok/s
the whole box dropped from 452 W to 358 W and the 3090 fan from 91% to 48% and that's the blessing ngl
quiet enough to sit next to, that's what I actually needed
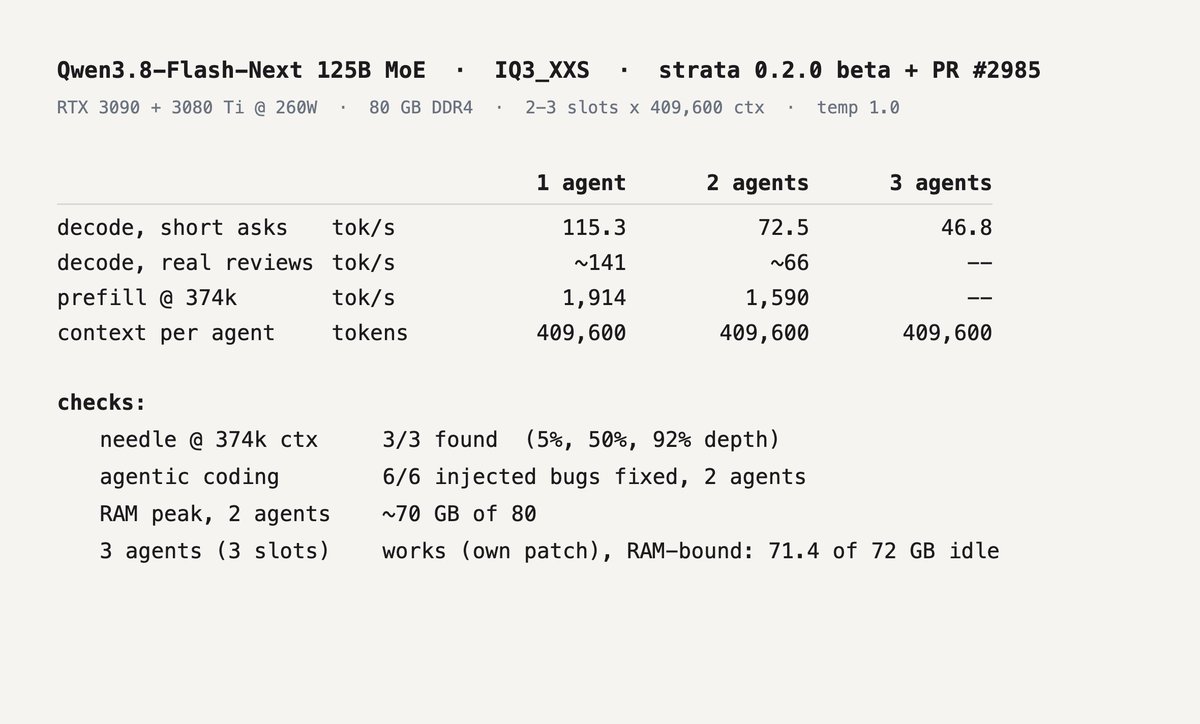
thanks to qwen3.8-flash-next + strata, this is the first time my Hermes is running fully on local LLM
IQ3_XXS running at 115 tok/s and is so capable, it's the perfect fit for my assistant
best part is I can spawn a sub agent and both agents decode around 65 tok/s with 400k context each
I even ran 3 agents at once and it works, ~47 tok/s each, but my 80gb of ram is the limit at 400k, time to buy more ram
I also use flash-next more in Deepseek Harness alongside cloud models
loved earlier small moe from qwen like the 35B, but they were not feeling frontier like flash next does
glm 5.3-flash finally crossed 30 tok/s on my local box
first attempt last week sat around 22 tok/s, today's clean baseline on the same harness is 26.1
two opt-in switches in the latest Maya took the average to 31.7 tok/s decode and around 900/1000 tok/s prefill
what held it back is my cpu doing the math for experts that never fit in vram
31 tok/s on a 321b model offloaded to 80gb ddr4, mind blowing
I'm keeping it on the box even tho qwen 3.8 flash-next is my current go-to
thanks to qwen3.8-flash-next + strata, this is the first time my Hermes is running fully on local LLM
IQ3_XXS running at 115 tok/s and is so capable, it's the perfect fit for my assistant
best part is I can spawn a sub agent and both agents decode around 65 tok/s with 400k context each
I even ran 3 agents at once and it works, ~47 tok/s each, but my 80gb of ram is the limit at 400k, time to buy more ram
I also use flash-next more in Deepseek Harness alongside cloud models
loved earlier small moe from qwen like the 35B, but they were not feeling frontier like flash next does
@JouirouMed yeah that's fair, I would need to give up a bit on the context
from what I've seen I'm not sure about the "by far superior", I need to compare the quality
@StartupHakk yep, I learned it the hard way, 4 slots at 512K froze the whole box. gonna buy more RAM to allow for real 3 agent, 47tok/s each also seems ok-ish for me
now the service is capped at 72gb so the engine gets killed before the machine does
@latent_node int8, not f16
only the last 32K tokens of each agent stay in VRAM, the rest sits in pinned RAM, around 1.16gb per 131K tokens per agent
that's the issue with 3x400k, it does not fit on 80gb of RAM, so I can only use 2 and looking to get more RAM
one night of tuning on my local box and two agents went from 30 to 66 tok/s each
the four things that moved it:
> 2 slots instead of 4
> an MTP patch
> the new strata 0.2.0 beta
> 260w on both cards
66 tok/s per agent while both generate and about 140 when one works alone
this will increase my usage of local AIs by a lot. I mean 100+ tok/s sustained on solo agent and 60tok/s for 2 sub agents working at the same time is kinda crazy