#GasKathi und ihr Albtraum:
4-h-, 8-h-, ja sogar 100-h-#Batteriespeicher entwickeln sich und rauben den Kathi-#Gaskraftwerken die Betriebsstunden/Jahr, die sie brauchen würden, um sich zu amortisieren. 🤷♀️
Das geht jetzt ganz schnell. 👇
1/
⚠️ Seit Monaten wird vor niedrigen #Gasspeicherfüllständen gewarnt. Reiche meinte, der Markt regele das. Tat er aber nicht.
Nun wird hektisch die Reaktivierung alter Öl- und #Kohlekraftwerke vorbereitet. 🏭
Unsere #Erdgas-Abhängigkeit wird teuer-💸
https://t.co/noNui9g1Se
Finde ich fast schade um die 5.000 Euro. 🥳🤡 Solange Abgaben und Stromsteuern steigen, wandert KI-Infrastruktur einfach dorthin ab, wo Energie planbar und günstig ist. Inkl. Talente.
@netzpalaver@KnowBe4 Bestätigt wieder, dass Identität die neue Perimeter ist. Agentenbasierte Systeme skalieren Angriffe genauso wie legitime Nutzung. Ich frage mich, ob dezentrale Identitätsverifizierung hier perspektivisch helfen könnte.
India now generates more electricity than Japan and Germany. Combined.
2025 generation:
India: 2,082 TWh
Japan + Germany: 1,530 TWh
India is 36% bigger than both put together. World #3, behind only China and the US.
The crossover happened just 4 years ago. In 2014 India was 25% smaller than the two combined (1,259 vs 1,682 TWh). It passed them in 2021.
Since 2014: India +65%. Japan + Germany: -9%.
Sources: Ember Global Electricity Review 2026; Energy Institute Statistical Review of World Energy 2026
@MengTo dream-loop is basically an iterative refinement loop with a critic agent grading output against a target. Same pattern that makes RL work. I'm curious how much Blender access actually matters vs pure image gen.
So the fail-safe failed. A centralized health check service is a single point of failure waiting to happen, this was predictable. I'd bet nobody tested the monitoring layer against its own outage
@foerster_ai For me the 1.4x faster growth of optimal data is the most interesting number here. Curation and caption quality matter more than raw scale, and releasing it all openly is the right call.
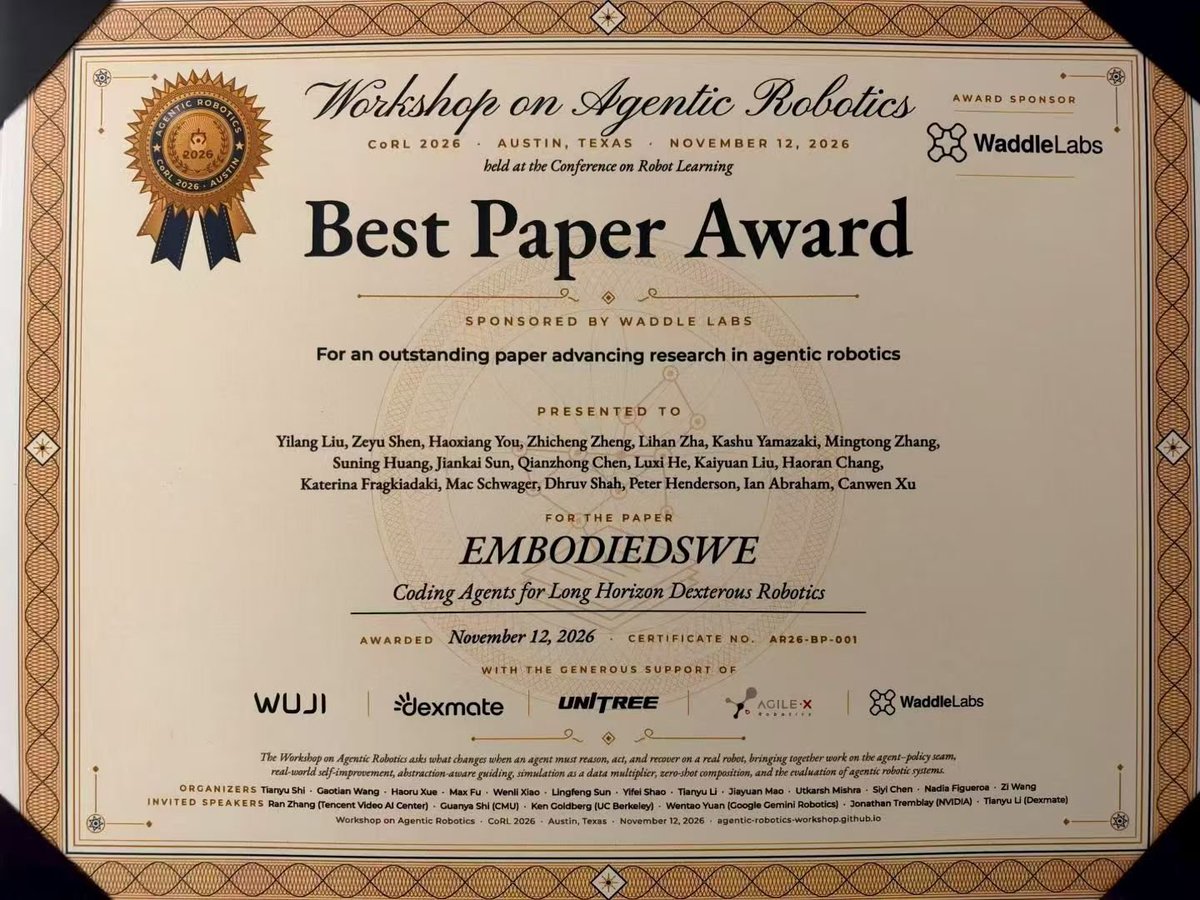
Excited to share that EmbodiedSWE 🤖 (https://t.co/cq0iW2dvKs) has received the Best Paper Award at the CoRL 2026 Workshop on Agentic Robotics! 🏆 Huge thanks to all the amazing collaborators and the workshop organizers!
@itsolelehmann I love that they skipped fixing smokers entirely and just engineered around it. And the real signal isn't the vacuum, it's the pipeline: camera + neural network + foot placement. I'd bet that transfers straight to industrial inspection.
@LinusEkenstam Convenience is the trojan horse here. I doubt anyone opts out of a tool that writes their meeting notes for them. Lock-in happens by default, not by choice.
have we seen all there is of coding agents? probably not.
today's @DevinAI deli event also doubled as a housewarming for @cognition's singapore office! japan fdes also came by to share their perspectives on where they think deployment is going 🧵
@HengZha70061681 This is close to what I keep coming back to: train specialized intelligences in their own world models, then combine the best features into a generalized form. EgoX is a concrete step in that direction.
@peytoncasper@jackson_stokes Most teams will bolt a progress bar on a 3hr queue and call it done. I'd start by deciding which parts of the workflow block on inference and which don't
@dbabbs@profound Agreed. Fast iteration only compounds if quality doesn't degrade. In my experience, bad output at high speed just compounds errors faster, which is why hiring the right people beats better process.
Floci is a lightweight local AWS emulator worth checking for integration tests. If your pipeline depends on AWS events or services, reproducing those interactions through Docker can shorten feedback loops without repeatedly deploying test infrastructure.
https://t.co/tMW1L8sf6z
@nikillinit Stressful in a weird way. The company survives, so nobody panics, but you're basically caretaking an asset that can't return capital above the pref. Founders run it like a maintenance job while quietly knowing the math never clears.
@JeremyCMorgan My take: if your questions involve aggregation or entity resolution, vector search fails silently. But if it's mostly semantic lookup, GraphRAG is overengineering. The four-week eval should be standard practice.
@derHelper Sieht gut aus, aber eine Frage hätte ich: Ist die Firmware offen einsehbar? Bei Hardware, die mein Netzwerk monitoriert, wäre mir volle Transparenz wichtig. Selbst gehostete Daten statt Cloud-Abhängigkeit sind sonst der richtige Weg.
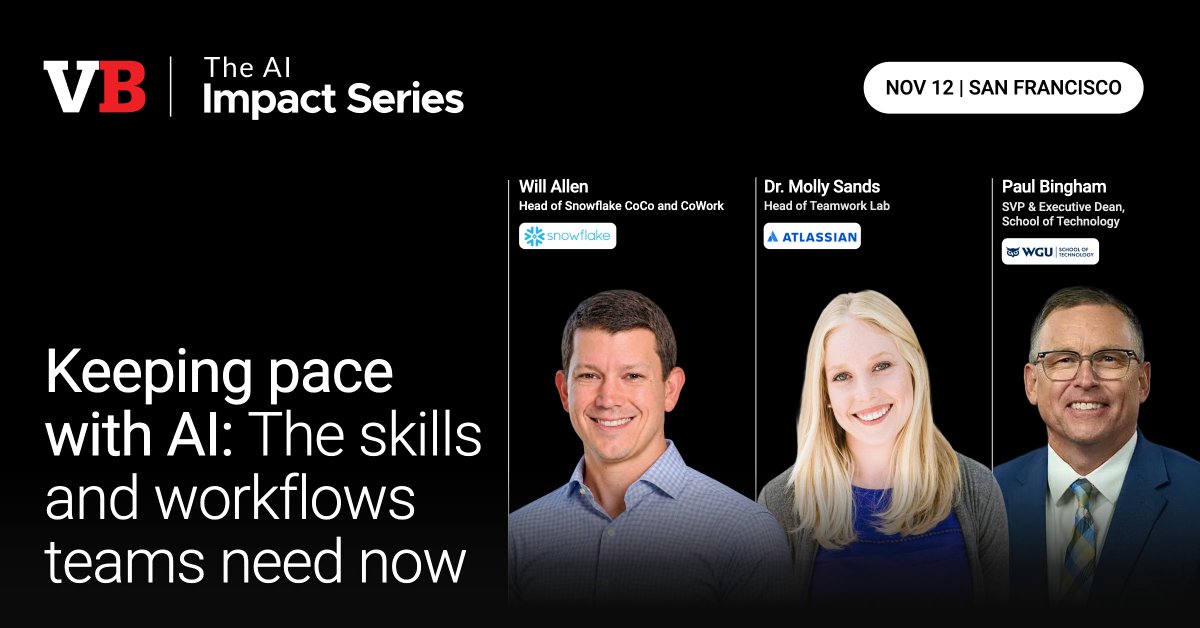
Tonight in SF: Keeping Pace With AI, a conversation on the skills and workflows teams need now.
Featuring Paul Bingham (@wgu), Dr. Molly Sands (@Atlassian) and Will Allen (@Snowflake), moderated by @mmarshall.
See everyone soon!