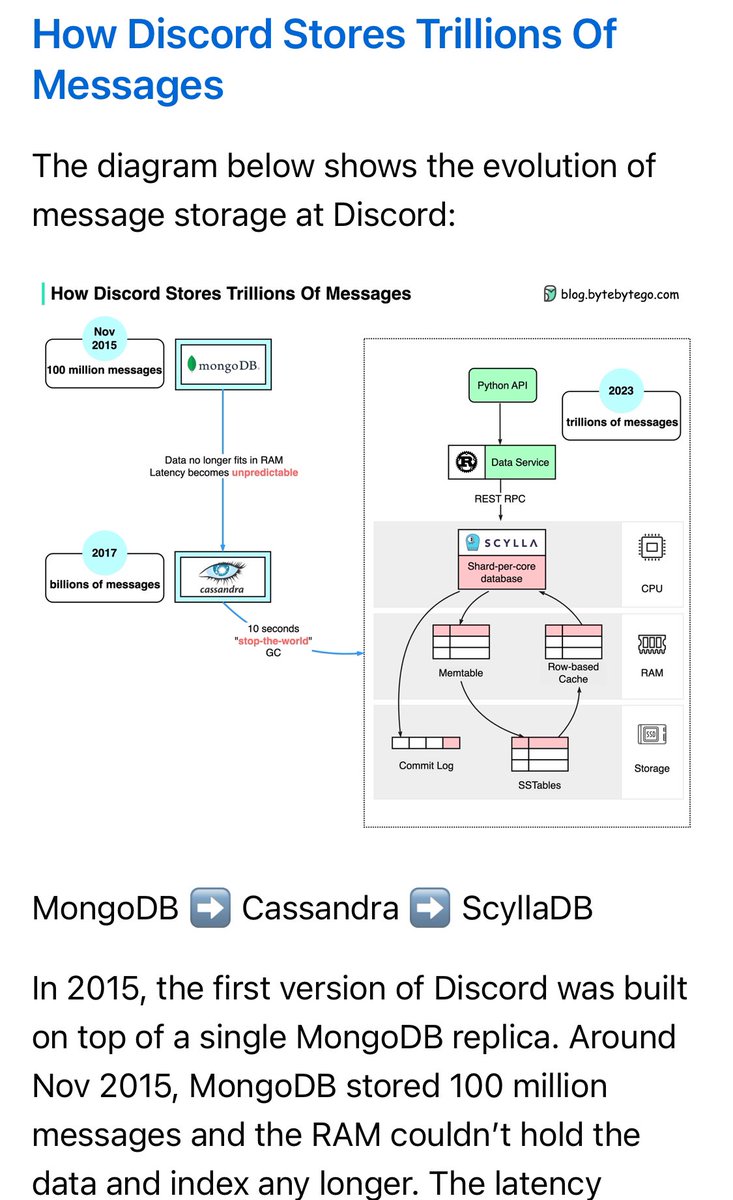
이번 스프린트 브랜치 관리가 힘들었는데 찜찜함은 역시나 이유가 있었고 🤦♀️ㅋㅋ 금욜엔 브랜치 전략 회의를 했는데 모르는 말들이 많아서 그저 동공만 흔들다 돌아온 나..
몰랐으면 공부하면 되는거구 실수했으면 다음엔 조심하면 되는거니까! 그래서 몰랐던거 공부해밨따
https://t.co/GHGPsKJ6i2
🎉 Join the Celebration! Our Gratitude to the incredible #Port3 community 🙌🚀
🎯Community IDO Whitelist Event
→ Whitelist × 800
→ 100% unlocked at TGE
→ Lucky Draw
🗓 Jan 5th 16:00 PM - Jan 7th 13:00 PM (UTC)
How to Participate:
https://t.co/MgX4ysLWWA
🎁 Embrace the chance to be part of this milestone! 🚀 Good luck to all! 🍀 #Port3Community #IDOWhitelistEvent
Excited to share that I recently left Stanford AI PhD to start Pika. Words can't express how grateful I am to have all the support from our investors, advisors, friends, and community members along this journey!
And there's nothing more exciting than working on this ambitious & creative project with the best team I can ask for :)
All your questions about dynamic experiences will be answered with Token Centric Architecture 👩🚀 Special thanks to #Smartlayer for developing the framework to power boundless innovation! 💥 #smartlayer
파이썬의 Pandas 가 널리 이용되면서, 최근 그 성능을 가속하기 위한 프로젝트가 많이 나오는데요.. 그중에서 NVIDIA GPU 와 CUDA 를 이용하는 cuDF 가 이번에 사용하기 편해졌다고 합니다.
https://t.co/ktioyDld7Y
패키지 설치와 플래그 ��정만으로 기존 Pandas 코드의 성능이 최대 150 배 향상된다고 하는데요, 문자열 비교나 CSV 읽기 같은 CPU 가 할 법한 일들도 가속이 된다는 점이 놀랍습니다.
pix2tex is a #Python library that allows you to convert images of equations into LaTeX code.
This allows you to incorporate an equation from a document into another document without recreating the equation from scratch.
https://t.co/1zckiE2BTq
Every Data Scientist needs to know these ideas.
They will blow your mind.
1. Correlation vs Causation
P(A | B) is the probability of A given B. It is the probability that we will observe A given that we have already observed B.
P(A | do(B)) is the probability of A given do(B). It is the probability that we will observe A given that we have intervened to cause B to happen.
In this context, an intervention simply means to take an action of some kind. Therefore do(B) means to take an action which causes B to happen.
The expressions P(A | B) and P(A | do(B)) might seem very similar but they represent very different situations.
2. We can only learn P(A|B) from the data alone.
Bob has an extremely accurate weather app and is always very good about bringing his umbrella when it rains. We observe Bob over several years and we find that whenever it rains, Bob always has his umbrella and he never brings his umbrellas on days when it doesn't rain.
In the language of probability, we say P(Umbrella | Rain) = 1 and P(Rain | Umbrella) = 1 as well.
What we can learn from this data alone is how to predict whether it rains with a 100% accuracy by checking whether Bob has an umbrella. We can also learn to predict with 100% accuracy whether Bob has an umbrella by checking if it's going to rain.
What we cannot learn is what will happen if we give Bob an umbrella on a random day of our choosing. The answer to this question is P(Rain | do(Umbrella) ) and it's unknowable from the data alone.
We need prior knowledge about how the world works to properly interpret the data we collected. We need to know that rain has an effect on Bob's behavior, but Bob's behavior has no effect on the rain.
Information about the effects of interventions are simply not available in raw data unless it is collected by controlled experimental manipulation.
3. Scientific Experiments work because they produce a very special kind of data.
You may have heard of what many people call a scientific experiment. Take a collection of objects, animals or people. Randomly split that collection into a control group and a treatment group. Apply your intervention to the treatment group while leaving the control group alone. If you observe any differences between the treatment group and the control group, it is logical to attribute these differences to the treatment. You can therefore say the differences were caused by the treatment.
In statistics, the procedure I just described is called a Randomized Controlled Trial. It is a procedure for generating a specific kind of data where:
P(Difference | Treatment) = P(Difference | do(Treatment) )
This is why traditional science experiments work. They are designed to capture causal information. This is not the case for vast majority of data that we collect in society.
Without human guidance or access to real world knowledge, statistical algorithms and artificial intelligences can only learn P(A | B) from the raw data. This is a fundamental mathematical limitation on the use of data alone.
That's it for now. This post is part of a series of posts about the concept of causal inference. They are based on the content of the Book of Why by Judea Pearl with lots of commentary from me.
Follow me (@kareem_carr) so you don't miss out on the next post.
Please show support by liking and retweeting the thread.
우연히 알게 된, 정말 멋진 발표! 어쩌면 어렵고 막연했을 주제를 차분하고, 깔끔하고, 아름답게 풀어 냈다. Rust의 좋은 점 하나를 꼽아야 할 때면 늘 std::result::Result를 들곤 했는데, 이제서야 그 이유를 제대로 알게 된 느낌이다. 좋은 시간이었다. https://t.co/Q5zAUMoJki