📢 About Motif 3📢
▪️ Decoder-only MoE language model with 314B parameters, 13.2B active.
▪️ Scored 47 on @ArtificialAnlys Intelligence Index, 5th among all open-weight models, ahead of @MiniMax_AI M3, @thinkymachines Inkling, @nvidia Nemotron, and all other models developed outside of China.
▪️ Built from scratch around a novel attention architecture (GDLA) and trained on only 768 B200s in ~5 months.
▪️ MIT license.
(1/3)
Excited to announce that Motif’s latest funding round includes a planned investment from @nvidia , alongside existing investors.
Now we go all in on Motif 4, and we’ll be back with a best-in-class frontier LLM. Thank you to our investors for the support. 🙏
We’re bringing Korea’s leading open models into production faster! 🏃♂️
New NVIDIA Dynamo deployment recipes support:
✔️ @SKtelecom’s A.X K2
✔️ @LG_AI_Research’s K-EXAONE 2.0
✔️ @UpstageAI’s Solar Open 2
✔️ @Motif_Tech’s Motif-3
These recipes deliver up to 2x inference performance on NVIDIA B200 GPUs.
Motif-3 stays FREE on Infron through October 1.
No minimum balance. Same API.
Try Motif-3: https://t.co/TjbARgKy23
Give Motif-3 a task that takes more than one step. Let your agent inspect a repo, run tests, and work through a failure. https://t.co/TpzjTZy77F
Motif-3 stays FREE on Infron through October 1.
No minimum balance. Same API.
Try Motif-3: https://t.co/TjbARgKy23
Give Motif-3 a task that takes more than one step. Let your agent inspect a repo, run tests, and work through a failure. https://t.co/TpzjTZy77F
@theoverstrcture built Motifcode, a coding harness designed for Motif-3. It's a community project, not an official release, and it's the most thoughtful integration work I've seen for Motif-3 so far.
Worth a look if you're building agents!
🔗 https://t.co/9bFasmKSHv
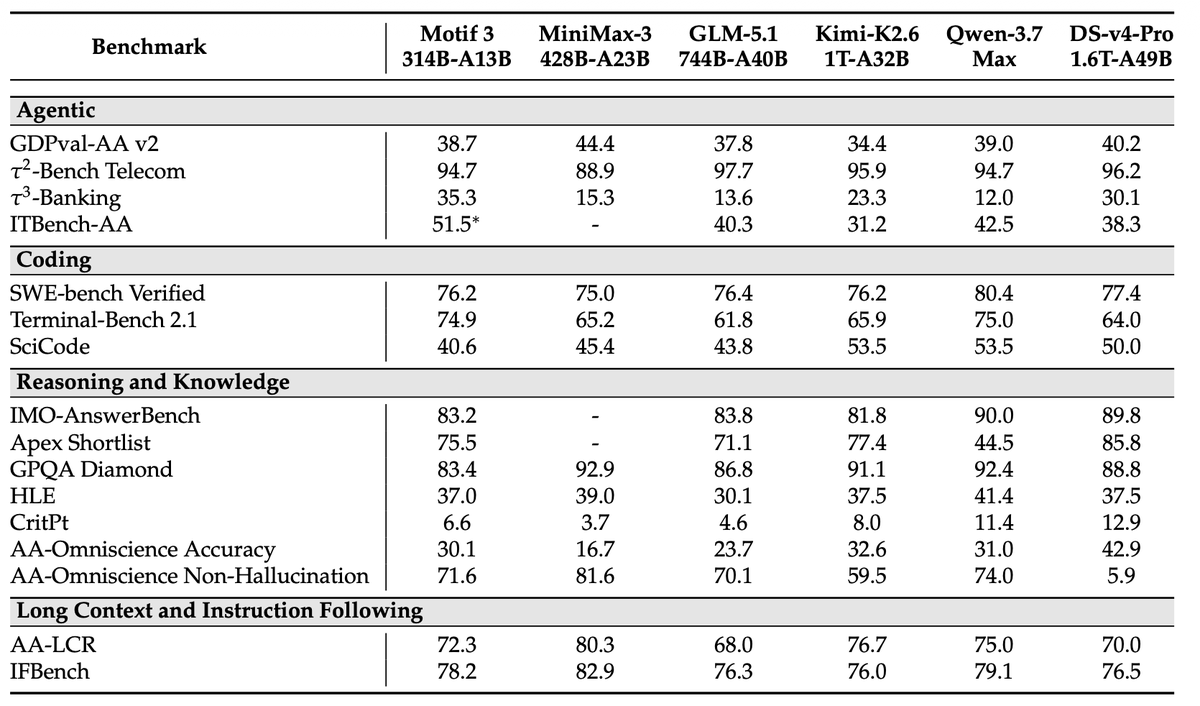
Motif 3 scores 35.3 on tau-3 Banking, ahead of DeepSeek V4 Pro in @motif_tech's published comparison: https://t.co/TjbARgL5RB
It activates just 13.2B parameters per token.
Free access on Infron. Report and API details in the first reply.
Motif 3 is free on Infron for one month.
314B total parameters, 13.2B active per token, a 256K context window, and MIT-licensed weights.
Try it with model ID motif/motif-3: https://t.co/TjbARgKy23
Built by @motif_tech. Details in the first reply.
Thank you @interconnectsai for the spotlight on Motif-3.
"Motif is one of the few hidden gems out there, showcasing innovation in their model training with very limited resources compared to others. Motif-3 comes with an MIT license and impressive scores for its size. Given the trajectory of model releases from Motif 2.6B, which we covered in 2025 and Motif-2-12.7B, the improvements are impressive."
Korea’s Trillion-Dollar Sovereign AI Investment: Nvidia Wins, Hynix Loses
Korea hosts a Squid Games, National AI Tournament,
the best non-Chinese open source model gets eliminated,
why Nvidia needs open source, implications for Hynix and Samsung
https://t.co/E3eiJx4VzN
@SemiAnalysis_ Thanks for the spotlight - we’re proud of what we’ve built from scratch.
Our weights are MIT, check out more in the links below.
Model card: https://t.co/k5smtDGt2K
Technical report: https://t.co/2jbC4tRRNm
📢 About Motif 3📢
▪️ Decoder-only MoE language model with 314B parameters, 13.2B active.
▪️ Scored 47 on @ArtificialAnlys Intelligence Index, 5th among all open-weight models, ahead of @MiniMax_AI M3, @thinkymachines Inkling, @nvidia Nemotron, and all other models developed outside of China.
▪️ Built from scratch around a novel attention architecture (GDLA) and trained on only 768 B200s in ~5 months.
▪️ MIT license.
(1/3)
Jisoo Lee, one of the driving forces behind Motif 3, will share the story of its development journey and how NVIDIA technologies were leveraged along the way.
If you’re interested, register for the session below!
⏰ Time: Wednesday, August 26, 2:00–3:00 PM
📌 Register here: https://t.co/MgXUsmX2xH
Motif 3 개발의 주역이신 이지수님께서 Motif 3 개발 여정과 Nvidia 기술들을 어떻게 활용했는지에 대해서 설명해주실 예정입니다.
관심있으신 분들은 아래 링크에서 일정 등록하세요!
⏰ 일시 : 8월 26일(수) 오후 2시 - 3시
📌 일정 등록하기: https://t.co/MgXUsmX2xH
🔔 [D-1 LIVE] 내일 오후 2시! 내 도메인에 딱 맞는 AI 모델 구축 라이브 스트리밍
Nemotron 3.5 Lightning 기반 SFT·LoRA 파인튜닝부터 모델 평가, NeMo RL 미리보기까지 — NVIDIA 전문가가 실무 핵심을 단계별로 짚어드립니다. 스페셜 게스트 Motif Technologies의 Blackwell 기반 K-AI 오픈 모델 구축 비하인드도 놓치지 마세요.
⏰ 일시: 8월 26일(수) 오후 2시 - 3시
📌 일정 등록하기: https://t.co/PBTQahB5W6"
Motif 3 is the highest-scoring open-weight model developed outside China—47 on the Artificial Analysis Intelligence Index.
Motif 3 API is coming soon. Stay tuned.
Thank you, @ArtificialAnlys, for the coverage.
South Korea has once again established a clear #3 position in the global AI race, trailing only the United States and China. The depth and vibrancy of Korea’s AI ecosystem is supported by strong domestic talent, public investment, and the incentives created by Korea’s Sovereign AI Foundation Model project
A number of South Korean labs, including Motif Technologies, Upstage, SK Telecom, and LG AI Research, have now scored above 30 on the Artificial Analysis Intelligence Index. This concentration of competitive model developers highlights the growing density of Korea’s domestic AI ecosystem. Among them, Motif Technologies and Upstage have models scoring above 40, making them the highest-scoring models on the Intelligence Index developed outside the United States and China.
Leading models from each lab include:
➤ Motif Technologies’ Motif 3 scored 47 on the Intelligence Index (314B total parameters, 13B active; open weights).
➤ Upstage’s Solar Pro 4 scored 42 on the Intelligence Index. It is a proprietary reasoning model.
➤ SK Telecom’s A.X K2 scored 35 on the Intelligence Index (692B total parameters, 33B active; open weights).
➤ LG AI Research’s K-EXAONE 2.0 scored 31 on the Intelligence Index (750B total parameters, 37B active; open weights).
Outside the competition, Korea’s model-development ecosystem has continued to broaden. Trillion Labs, Korea Telecom (KT), and other AI labs are building out their own model families, adding to a domestic field that is considerably deeper and more competitive than it was a year ago.
new huge oss release: motif 3 final checkpoint with a tech report and base model
tech report include ablations on GLDA (their new attention variant), expert stabilization, dataset (they use nemotron 3 mixture for 70% of the pt corpus) and much more
https://t.co/8Tb5SaAePH