GPS gets you close. VPS gets you precise.📍
Delivery robots need the right side of the street. Niantic Spatial’s Visual Positioning System (VPS) matches camera views to map data to help pinpoint location and direction.
Read more: https://t.co/iAt4kSHgbP
#PhysicalAI#Robotics #SpatialAI #EmbodiedAI #AI #VPS #Localization #VisualPositioning
we’ve open sourced 49 interview questions that come up the most in Inference/LLM engineer interviews, each linked to an explanation and a problem you can solve against tests.
https://t.co/JD4lJg3P9L
π4 - 0.5B foundation model for real-time 3D reconstruction and camera pose estimation from uncalibrated RGB images.
- All-in-one in a single run
- No drifting tracks
- Handles massive scenes
cool for consumer drone and action camera mapping
https://t.co/IF1F5z1zZP
Long-horizon navigation agents lose track of subtask progress and can't recover from local errors? LeaP-VLN adds a progress verifier that checks completion before advancing, plus dual-phase recovery when agents go off route 🔄
📄 https://t.co/634NS8ofb2
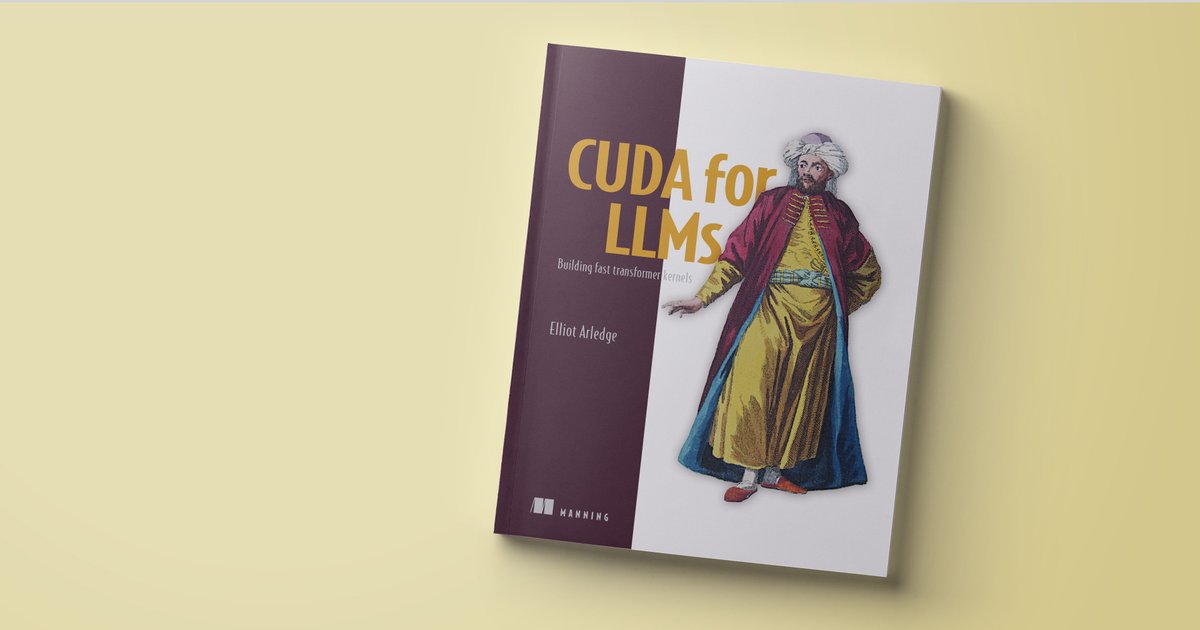
My book "CUDA for LLMs" is now in print!
If you followed along while it was in early access as "CUDA for Deep Learning", this is the finished version, now as a physical book too.
Manning gave me a code for 50% off every format through Dec 4: PBArledge
https://t.co/L3riD6Pg1F
Even powerful GPUs can struggle with LLM inference when moving data becomes the bottleneck.
In Quantization and Fast Inference, @vivekkalyanaran explains how reducing numerical precision can ease memory demands and improve efficiency.
Watch: https://t.co/GHPertZA43
All the Transformer math you actually need to scale models.
- Matrix multiplies dominate everything.
- Training costs 6× more FLOPs than inference.
- At long context, attention’s quadratic term overtakes the MLP.
- Attention becomes the bottleneck once sequence length ≳ 8× model dimension
This is the clean breakdown of FLOPs, memory, and parameters that actually matters when you’re pushing model size or sequence length.
Full breakdown with the edge cases (checkpointing, KV cache, FlashAttention)
Worth of check if you train or serve large models.
- https://t.co/PiqHX8ogOu
~590x smaller than VGGT, yet 97.4 vs 99.3 RRA@15 on CO3Dv2, and faster than COLMAP/GLOMAP beyond ~15 views.
Joint work with Jason Chui (@cphjsn) and Daniel Cremers (@daniel_cremers), @tumcvg
and @MunichCenterML
3D Gaussian segmentation trains on rendered views, so occluded Gaussians get zero supervision. VODA fixes that: volumetric depth clustering supervises every Gaussian, not just the visible ones 🔍
📄 https://t.co/T9c0Ah6NEp
🌐 https://t.co/SDvds4PdqZ