Today, we’re making Praxis-1 available to everyone. Our state-of-the-art world action model turns video pretraining into control for real robots, and it ships with open weights under Apache 2.0, ready to run and fine-tune on your own hardware.
Meshy Rigging updates on fal.
- Turns humanoid 3D models into characters ready to animate.
- Works with Unreal Engine, Unity, Blender, Mixamo and more.
- Prepares fingers for animation at no extra cost.
- Adds multiple animations to the same character.
New VFX capabilities from LTX are now live on fal.
Generate and edit production-ready video with four powerful tools:
- AlphaGen: Generate transparency mattes with fine edge detail, up to 4K
- SDR → HDR: Convert standard video to HDR with expanded dynamic range
- Reframe: Adapt videos to new aspect ratios
- Upscale: Enhance video resolution up to 4K or 8K
Build with LTX on fal.
Introducing Gemini Robotics 2.5, our most capable vision-language-action (VLA) model to date. 🤖
It increases both the breadth of skills a robot can learn and the speed at which it acquires them — helping robots step out of the lab and into real-world environments.
Learn more about Gemini Robotics 2.5, now rolling out to our robotics partners 🧵
Google has released its first decision model, Gemini Decision 1, scoring 66 on the Artificial Analysis Decision Index and leading in knowledge and reasoning benchmarks
Gemini Decision 1 from @GoogleDeepMind scores 66 on the Artificial Analysis Decision Index v2.1, in line with Elephant 9B (@baselabs) and Jev 1.14 (@typesafeai), and 7 points behind leaders Drex Max v1.1 (@NaceAI) and GLiDE v1.2 (@fastinoAI), which both score 73. It is priced at $0.10 per 1M input tokens and costs $345 per 1M Tasks across the Index, around three times higher than Drex Max v1.1 ($103) due to its higher pricing
Key results for Gemini Decision 1:
➤ Not yet frontier on Decision Index: Gemini Decision 1 scores 66 on the Artificial Analysis Decision Index. It leads knowledge and reasoning benchmarks, scoring 66 on AA-Omniscience-Decision and 49 on HLE-MultiChoice. It trails on other evaluations, including our new proprietary classification and extraction benchmark AA-Paperclip, where it answers all 15 questions correctly on 33% of documents vs. 63% for Drex Max v1.1
➤ More than 3x the Cost per Task of leading models: Gemini Decision 1 costs $345 per 1M Tasks, compared with $103 for Drex Max v1.1, $156 for Jev 1.14. This difference is driven by its token price of $0.10 per 1M input tokens vs. $0.03 for Drex Max v1.1. Gemini Decision 1 has a similar Cost per 1M Tasks to GPT-6 Luna (Decisions, $339)
➤ Strong calibration for reasoning tasks: We measure calibration with the Brier score, the average squared gap between the probability a model assigns to its chosen answer and whether that answer was correct (lower is better). Gemini Decision 1 has a Brier score of 0.18 across the Index, between Drex Max v1.1 (0.16) and Jev 1.14 (0.19). Calibration varies by task. with its Brier score of 0.20 on HLE-MultiChoice among the lowest of all models in the Index, while its 0.14 on When2Call compares with 0.04 for Drex Max v1.1
ComfyUI-Lux3D
Turn text or images into 3D assets inside ComfyUI
The extension provides 12 nodes you can combine to generate models, redraw materials, split meshes, or rebuild topology to a target face count.
Humanoid rigging and animation nodes let you rig character models and add actions. Models can be exported to USDZ, OBJ ZIP, FBX ZIP, STL, and 3MF.
A viewer previews models in the ComfyUI canvas. Local GLB models can be viewed without uploading them to Lux3D.
https://t.co/Ysc74gHjaa
Ernie 5.5 Flash Preview by @Baidu_Inc is trending towards becoming the #2 open model on the Code Arena: WebDev, at 1668 pts. The weights will be open-sourced under Apache 2.0 soon.
Its score puts it just above:
- DeepSeek-V4.1-Flash (Max) at 1664
- Kimi K3 (Max) at 1658
and on par with:
- Qwen3.8-Max at 1670
Congrats to the @Baidu_Inc team on this release!
I ported ReCaVSR to ComfyUI, a one-step 4× video super-resolution model based on Wan2.2.
960×480 → 3840×1920, 149 frames in 36 s on an RTX 4090. int8 build, runs from 8 GB.
Generate and edit images and videos directly in ChatGPT, using the fal plugin.
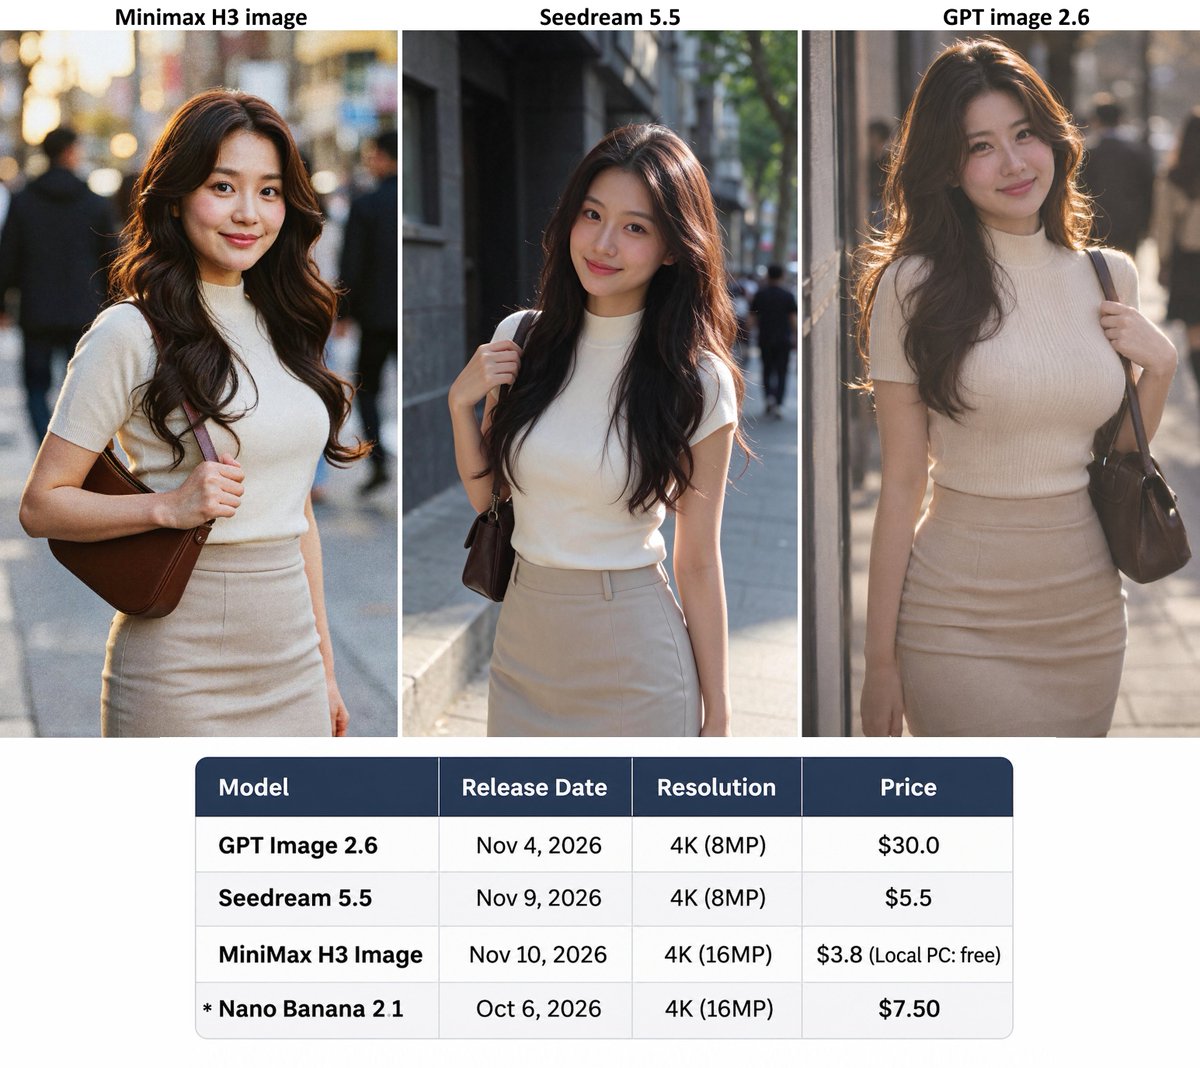
We used GPT Image 2.6 to generate hundreds of keyframes, FLUX 3 Max to animate 26 shots, and brought it all together into a 60-second commercial.
🧵 Here's how we did it.
SwitchX 3.0 is here. Our biggest update yet.
Rebuilt on MiniMax H3 for professional video-to-video:
→ Up to 4 references
→ Backgrounds that move
→ Camera tracking, no markers
→ Prompts that direct the scene
Your performance stays locked. Only the world around it changes.
99% AI. Hope you enjoy!
Lyrics: Me + Claude Opus 5.5
Image Stills: Midjourney v8
Video: Minimax H3
Editing: Me + Davinci + Claude Opus 5.5
Music: Suno v6 wild
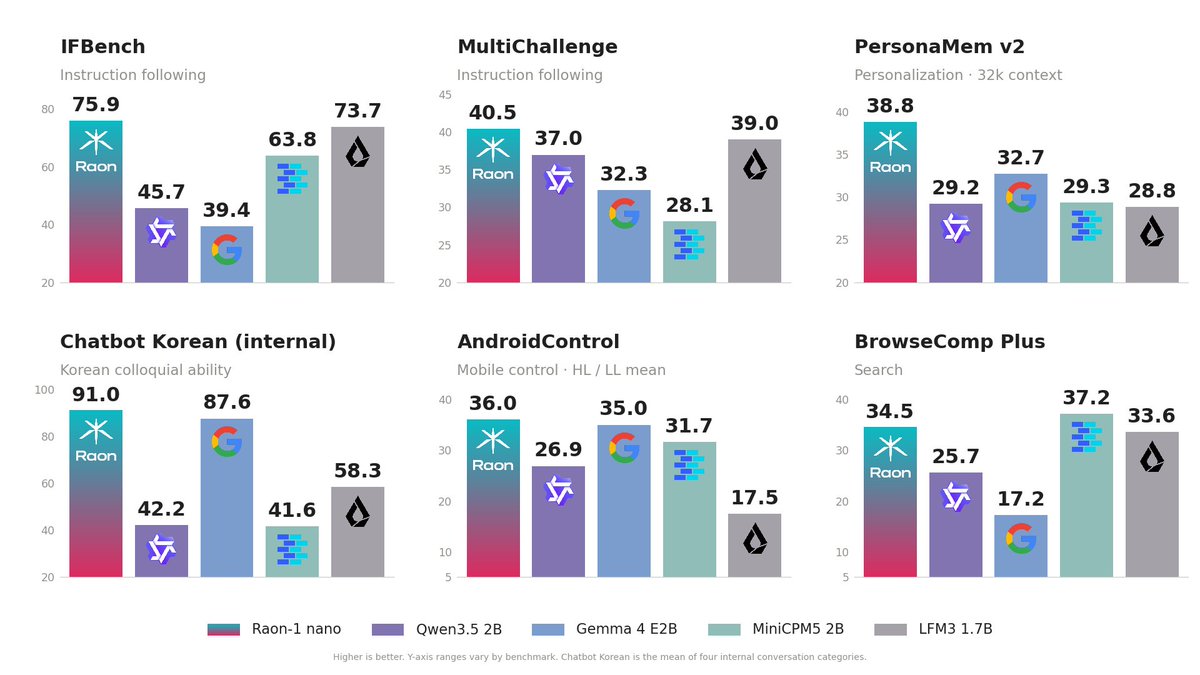
We’re releasing Raon-1 nano, an effective 1.5B dense LLM with per-layer embeddings and 3.1B total parameters. ⚡
Our journey from PUBG Ally toward on-device LLMs continues.
We pruned and distilled Raon-1 mini preview (30B-A4B) using our MoE-to-Dense approach, then further trained it on 3T tokens, followed by SFT, OPD, and RL.
Designed for natural conversations, maintaining conversational context, instruction following, and tool use in both Korean and English.
Small model. Smart interactions. Enjoy! 😊
🤗 Weights (Apache 2.0 license): https://t.co/ZVMZmlSNlz
📄 MoE-to-Dense (NeurIPS 2026 Oral): https://t.co/eoYH86lBs0
🪖 Learn more about PUBG Ally: https://t.co/A3iZvP2X7c
New on DesignArena: MiniMax H3-Image by @MiniMax_AI is ranked #2 among open weight models on Image arena.
This places it in the same performance band as top models from @ideogram_ai, @krea_ai, and @bfl_ai. At an average of 15s per generation, it is 4× than Ideogram 4.0 which is currently in 1st place and is the fastest model in the top 3.
Congrats to the @MiniMax_AI team on a top-3 open weight placement!
I've added live streaming from RGBMocap to Blender! Motion baking is also supported. I'm currently working on a retargeting add-on for characters with different body proportions. #mocap https://t.co/lIk6nnwc4o
What do AI video models like Seedance 2.5 and MiniMax H3 pick up from a 3D blockout? We break it down with examples, from basic shapes to fully animated character.
Follow for more AI video tips and breakdowns.
Introducing Gemini Decision 1, our new frontier decision model in the Gemini API.
It is $0.10 per 1M input tokens with no additional cost. With support for image, audio, video, and PDF natively, 256K context window, & 1K questions.
You can try it for free in the API!