I'm so excited that our @theworldlabs team has achieved a major milestone today! Introducing Atlas - a first of its kind multimodal world model trained from scratch! 🚀
Atlas is capable of generating frames with pixel-perfect camera control, reconstructing large scenes from as few as one single input image, simulating space-time by reframing videos, natively outputting 3D spaces from one or more input images, composing multiple posed images into a consistent 3d world, and more! This is the best camera conditioned world model ever, opening doors to many possible use cases from VFX to robotics. I'm so so so proud of our team!♥️
Dwarkesh is the most San Franscisco podcast of all. Its universe is intense, hyper intelligent and maximally AGI pilled. I suspect that it dramatically overestimates the value of intelligence outside of SF, and underestimates the inertia of the rest of the world
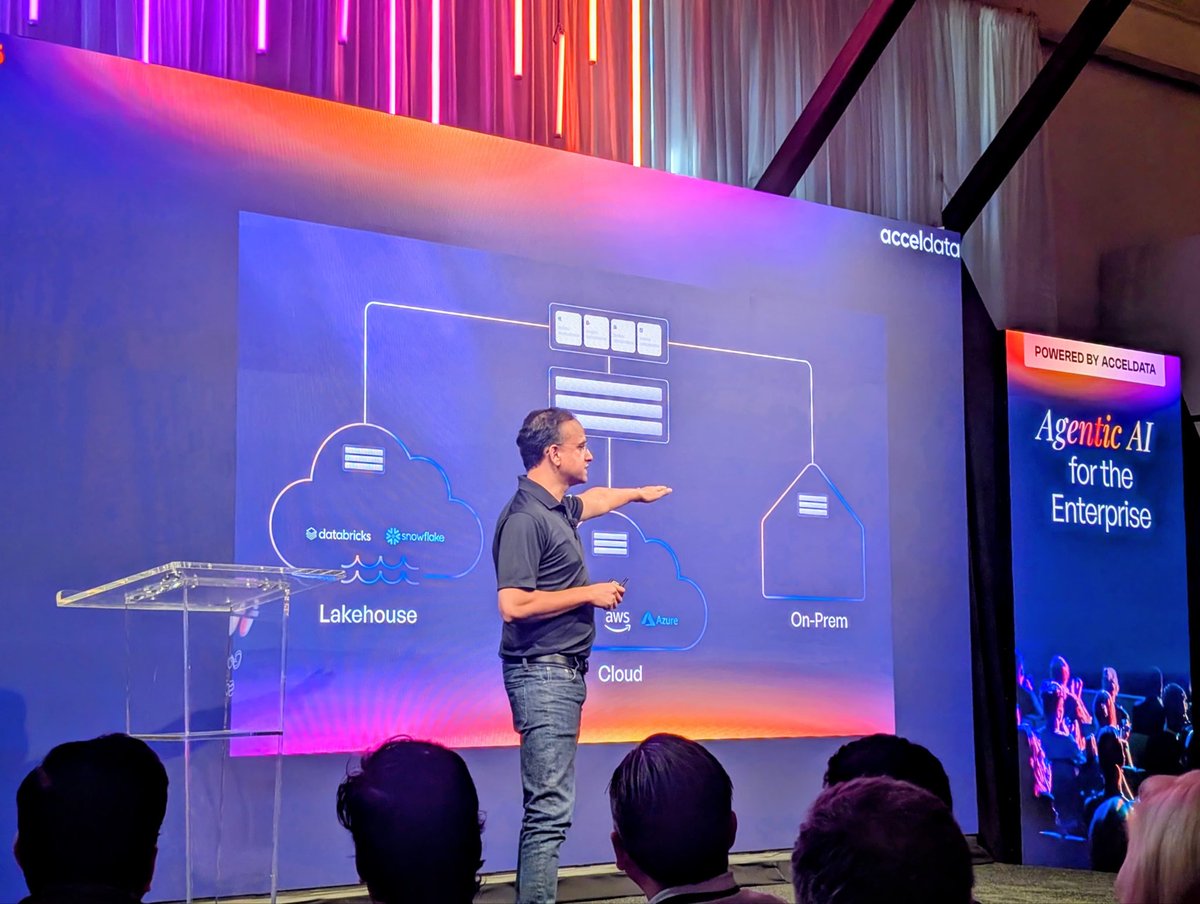
At @acceldataio’s Autonomous conference today with Rohit and Ashwin here in San Francisco.
T-Mobile, Verizon, Barclays, Merck, Pfizer, Qualcomm in the room.
All of them hitting the same wall: agentic AI doesn’t work in Fortune 500 enterprises if the underlying data — spread across on-prem, cloud, and hybrid — isn’t compute-ready at petabyte scale.
You still need a control/compute plane that runs compute and data workloads across your entire legacy and modern data stacks as well as within any agentic harness like Claude or Codex.
That’s exactly what Acceldata’s AI-native data runtime is.
Proud to be an investor in this category leader in enterprise data & AI platforms.
https://t.co/tal8Ef4sXN
Did a very different format with @reinerpope – a blackboard lecture where he walks through how frontier LLMs are trained and served.
It's shocking how much you can deduce about what the labs are doing from a handful of equations, public API prices, and some chalk.
It’s a bit technical, but I encourage you to hang in there - it’s really worth it.
There are less than a handful of people who understand the full stack of AI, from chip design to model architecture, as well as Reiner. It was a real delight to learn from him.
Recommend watching this one on YouTube so you can see the chalkboard.
0:00:00 – How batch size affects token cost and speed
0:31:59 – How MoE models are laid out across GPU racks
0:47:02 – How pipeline parallelism spreads model layers across racks
1:03:27 – Why Ilya said, “As we now know, pipelining is not wise.”
1:18:49 – Because of RL, models may be 100x over-trained beyond Chinchilla-optimal
1:32:52 – Deducing long context memory costs from API pricing
2:03:52 – Convergent evolution between neural nets and cryptography
RT to help Simon raise awareness of prompt injection attacks in LLMs.
Feels a bit like the wild west of early computing, with computer viruses (now = malicious prompts hiding in web data/tools), and not well developed defenses (antivirus, or a lot more developed kernel/user space security paradigm where e.g. an agent is given very specific action types instead of the ability to run arbitrary bash scripts).
Conflicted because I want to be an early adopter of LLM agents in my personal computing but the wild west of possibility is holding me back.
AI Agents dramatically expand software TAMs because you’ll have endless use cases for AI that you never had previously. There’s no universe where every day you could give out PhD level work to someone and wake up with it all done. AI Agents will do that for anything.
Every enterprise is going to become AI-first whether they know it or not yet. And the ones that move early will develop a far faster learning curve on how these tools shape work than those that don’t. This will become a strategic advantage for those that get started now.
The reality of building web apps in 2025 is that it's a bit like assembling IKEA furniture. There's no "full-stack" product with batteries included, you have to piece together and configure many individual services:
- frontend / backend (e.g. React, Next.js, APIs)
- hosting (cdn, https, domains, autoscaling)
- database
- authentication (custom, social logins)
- blob storage (file uploads, urls, cdn-backed)
- email
- payments
- background jobs
- analytics
- monitoring
- dev tools (CI/CD, staging)
- secrets
- ...
I'm relatively new to modern web dev and find the above a bit overwhelming, e.g. I'm embarrassed to share it took me ~3 hours the other day to create and configure a supabase with a vercel app and resolve a few errors. The second you stray just slightly from the "getting started" tutorial in the docs you're suddenly in the wilderness. It's not even code, it's... configurations, plumbing, orchestration, workflows, best practices. A lot of glory will go to whoever figures out how to make it accessible and "just work" out of the box, for both humans and, increasingly and especially, AIs.
Good post! It will take some time to settle on definitions. Personally I use "vibe coding" when I feel like this dog. My iOS app last night being a good example. But I find that in practice I rarely go full out vibe coding, and more often I still look at the code, I add complexity slowly and I try to learn over time how the pieces work, to ask clarifying questions etc.
What happens if high quality AI models become free, ubiquitous, and inexpensive to run on even low-spec hardware?
(1) First, you can rebuild every productivity app AI-first. That starts with Microsoft Word, Google Sheets, and Apple Keynote. But it extends to wholly new kinds of productivity apps.
(2) Second, every “smart” device becomes truly smart. Your fridge can double as your nutritionist. Your alarm clock is your sleep therapist. And so on. Just like your car is already your driver.
(3) Third, moats move to the app layer. As others have remarked, the GPT wrappers may end up more defensible than the GPT model itself.
(4) Fourth, physicality becomes relatively more valuable. The hardware, the secure real estate, the in-person community — these are all things digital AI can’t deliver.
(5) Fifth, high human IQ actually becomes increasingly valuable. Because AI is really amplified intelligence rather than truly agentic intelligence, since it requires the creative prompt to get started.
(6) Sixth, prompt engineering is here to stay, because prompting is programming — just in a higher-level language.
(7) Seventh, the most common form of AI doomerism is proven false, because we are getting decentralized ubiquitous AI rather than centralized monotheistic AI. More like a garden of smart things than a vengeful Old Testament God that’ll turn you into paperclips.
(8) Eighth, the combination of cuts to US “industrialized” academic research at the same time AI models accelerate discovery will mean a return to individual gentleman scientists and the advance of desci (decentralized science).
(9) Ninth, the complement to probabilistic AI is deterministic crypto. For captchas, for identity, for money, for all these things — crypto is the digital scarcity that AI can’t fake.
(10) Tenth, the main cost of software development may reduce to reducing the costs of the physical environment. That is: to providing society-as-a-service, to simply giving engineers time to type and experiment in peace. This was already so, but may become even more so.
Several of these points have been made by others, but I think that collectively they help define the second mover era.
yep exactly, great work spelling it out step by step.
sometimes I talk about it as "breadth is free, depth is expensive" in the imagined full compute graph of the neural net. afaik this was the major insight / inspiration behind the Transformer in the first place. The first time it properly hit me is when I read the Neural GPU paper a long time ago
https://t.co/TmrwEGdn8r
also btw in "from bits to intelligence" why keep including python? delete python and I think you can make it ~10X less, just along the lines of llmc.
When working with LLMs I am used to starting "New Conversation" for each request.
But there is also the polar opposite approach of keeping one giant conversation going forever. The standard approach can still choose to use a Memory tool to write things down in between conversations (e.g. ChatGPT does so), so the "One Thread" approach can be seen as the extreme special case of using memory always and for everything.
The other day I've come across someone saying that their conversation with Grok (which was free to them at the time) has now grown way too long for them to switch to ChatGPT. i.e. it functions like a moat hah.
LLMs are rapidly growing in the allowed maximum context length *in principle*, and it's clear that this might allow the LLM to have a lot more context and knowledge of you, but there are some caveats. Few of the major ones as an example:
- Speed. A giant context window will cost more compute and will be slower.
- Ability. Just because you can feed in all those tokens doesn't mean that they can also be manipulated effectively by the LLM's attention and its in-context-learning mechanism for problem solving (the simplest demonstration is the "needle in the haystack" eval).
- Signal to noise. Too many tokens fighting for attention may *decrease* performance due to being too "distracting", diffusing attention too broadly and decreasing a signal to noise ratio in the features.
- Data; i.e. train - test data mismatch. Most of the training data in the finetuning conversation is likely ~short. Indeed, a large fraction of it in academic datasets is often single-turn (one single question -> answer). One giant conversation forces the LLM into a new data distribution it hasn't seen that much of during training. This is in large part because...
- Data labeling. Keep in mind that LLMs still primarily and quite fundamentally rely on human supervision. A human labeler (or an engineer) can understand a short conversation and write optimal responses or rank them, or inspect whether an LLM judge is getting things right. But things grind to a halt with giant conversations. Who is supposed to write or inspect an alleged "optimal response" for a conversation of a few hundred thousand tokens?
Certainly, it's not clear if an LLM should have a "New Conversation" button at all in the long run. It feels a bit like an internal implementation detail that is surfaced to the user for developer convenience and for the time being. And that the right solution is a very well-implemented memory feature, along the lines of active, agentic context management. Something I haven't really seen at all so far.
Anyway curious to poll if people have tried One Thread and what the word is.
It's 2025 and most content is still written for humans instead of LLMs. 99.9% of attention is about to be LLM attention, not human attention.
E.g. 99% of libraries still have docs that basically render to some pretty .html static pages assuming a human will click through them. In 2025 the docs should be a single your_project.md text file that is intended to go into the context window of an LLM.
Repeat for everything.
Awed by Miracle of Mind, a free meditation app by Sadhguru which is setting records. Slickly designed with a very cool AI based Q&A. Built by non-profit volunteers, it hit 1M+ downloads within 15 hours of launch, faster than ChatGPT, TikTok and Instagram! https://t.co/dLp3HHgkiy
The AI revolution depends on infrastructure. With over $75B invested in AI hardware and software, enterprises are racing to build the infrastructure stack that will power the future.
Next week at @MontySummit, Together AI’s Founding SVP of Product @jamiedg will join industry leaders @PierreFERRAGU (@NewStreetR), Brian S. Raymond (@UnstructuredIO), @kbsdigital (@AMD), and @rconline (@acceldataio) to discuss the state of AI infrastructure, the challenges ahead, and what it takes to build intelligent systems that scale.