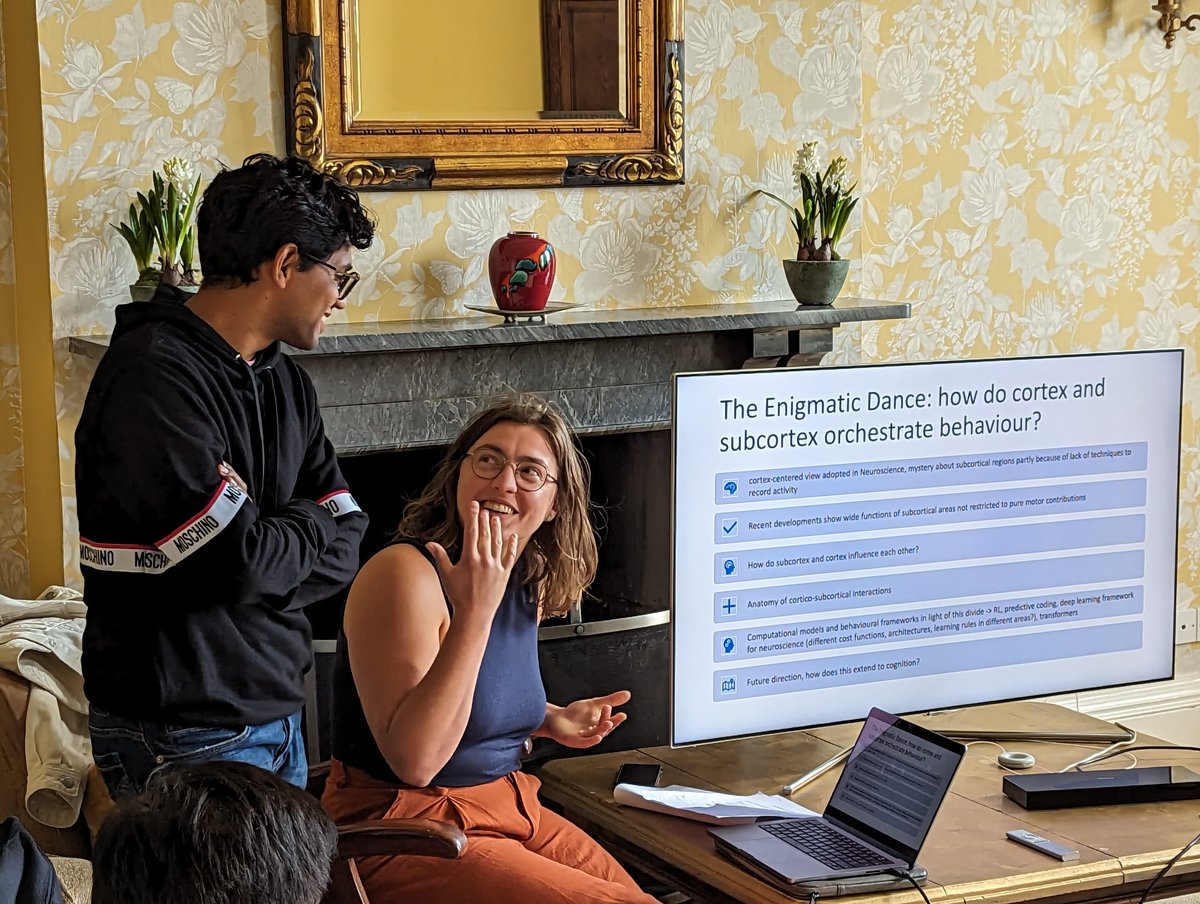
@efharkin_@somnirons But one can certainly imagine a similar scenario of visiting the same RNN state many times due to attractor dynamics. It would be cool to find out the types of task where high lambda (or non true online) fails as a result
@efharkin_@somnirons Interesting! A priori we might have expected a problem of high variance as in RL but in our case we find higher lambda to consistently perform better (discussed a little in first paragraph of the limitations section)
@efharkin_@somnirons Hi @efharkin_ ! Great question and I did briefly consider it (but not in paper). Preliminary results showed it could make improvements but in the end I felt the added computational cost (roughly x2) wasn't worth it for now. Definitely something to consider for the future though!
🚨 While working on synthetic gradients (SGs) by @maxjaderberg as a model for neuroscience, which relies on bootstrapping as commonly used in RL @JoePemberton9 wondered whether we could push this analogy further.
🧵(1/10)
[1/8] Pleased to share our work that studied cerebellar (CB) contributions to motor cortex (M1)-driven neuroprosthetic control- led by @draabbasi in the lab, published today in @ScienceAdvances https://t.co/DXMW6MHaTz
Interested in doing your postdoc on bringing anatomy and cognition into NeuroAI? Or how the cortex works differently under stress? Come do your #MSCA in buzzing Bristol, and get in touch!
Exciting postdoc position between the labs of @lengyel_m + @GJEHennequin (Cambridge U) and @DMWolpert (Columbia U) to study the neural network mechanisms of context-dependent (continual) motor learning. Máté and I will be at Cosyne, come talk to us! https://t.co/ihBcer1SH9
🚨⏰ 🚨 #TWEEPRINT TIME 🚨⏰ 🚨
💫🎊🥳My postdoc work is now online! 🎉🌝💫
@shenoystanford@SussilloDavid and I have been working to understand how neural networks perform multiple related/interfering computations using the computation through dynamics framework.
1/15
V. interesting preprint about how EI balance supports continuous olfactory representations in zebrafish, by the great @Clairemb1. Compared to discrete Hopfield nets, cont. representations provide a metric between odors & appear to help continual learning https://t.co/1c8u2OGF4Q
Why are policy gradient methods typically so sample inefficient?
Whenever a trajectory contains a reward, they credit all actions leading to it. But not all actions mattered! What if we could only credit actions that did matter?
Our NeurIPS spotlight paper does just that 🧵️
Viewing the cerebral cortex in isolation (ie without appreciation of its interaction with the thalamus, basal ganglia and cerebellum) has the potential to lead to an overemphasis of its importance and also to erroneous claims of its isolated functional capacities...
-- Mac Shine
Neural population analyses often focus on task-relevant stimulus representations. But what about task-irrelevant stimuli? Should they simply always be ignored? What if they become relevant later? We study this question in optimized RNNs and PFC recordings: https://t.co/uC7p2UuCe5
🚨 New preprint! This is our first endeavour in behavioural work (led by Anne-Lene Sax). Depression is believed to hinder one’s ability to reason about oneself (metacognition). https://t.co/zpog425yv1 (1/2)
New review paper on the role of the thalamus in shaping whole-brain dynamics and how we can test these ideas with functional neuroimaging. Collaborative effort with @kaihwang12@lauradata and @Garrett_Neuro. Out now in @NatRevNeurosci. Hope you enjoy!
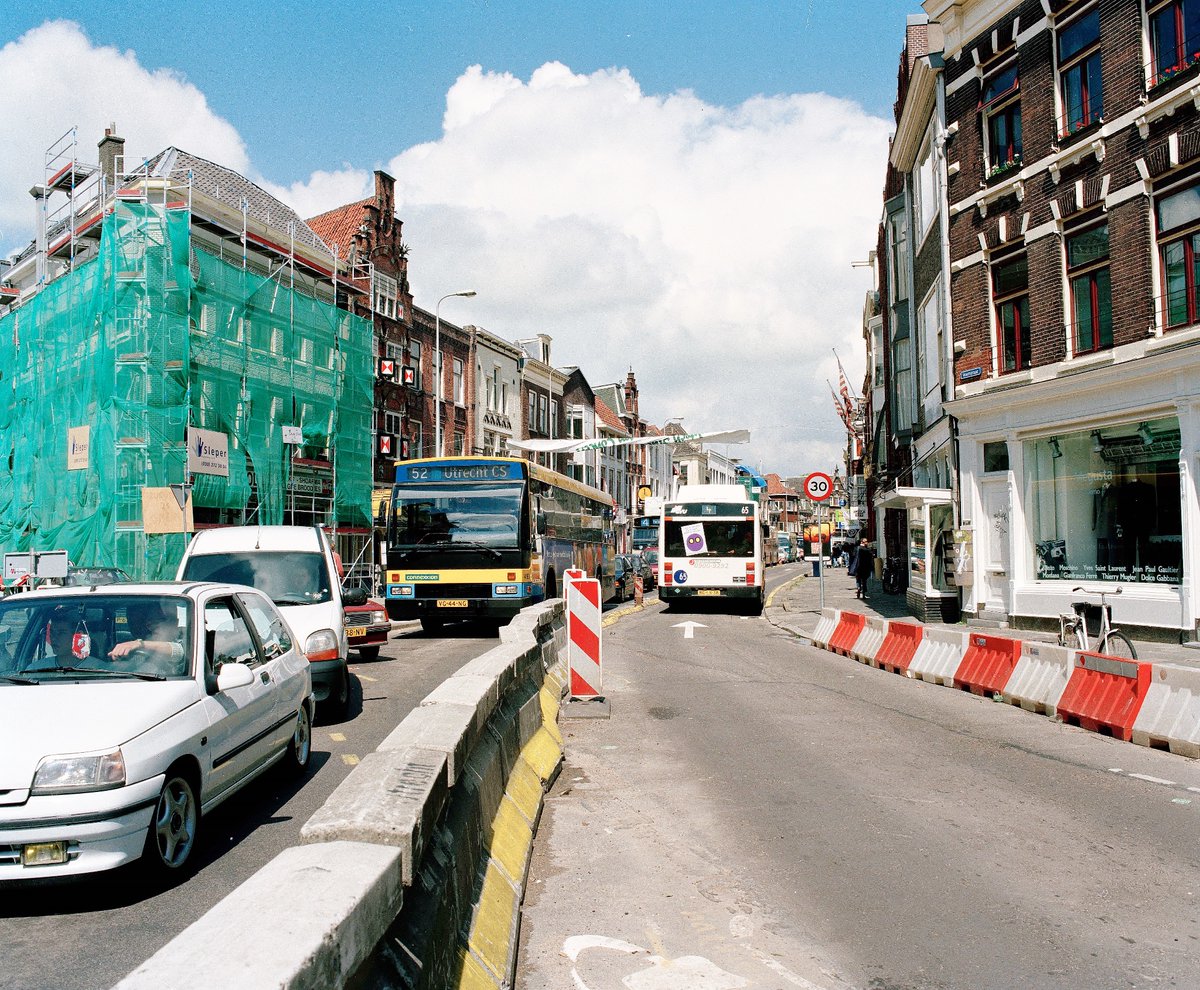
The Netherlands wasn't always known as a biking country. Change is possible!
The Voorstraat in Utrecht, photographed in 2000 vs March 2023.
Photos from @edwinlucas_ on Twitter: https://t.co/rU45Dwcosj
In a new ICLR 2023 paper @gkreiman, @DimaKrotov, @alxndrdavies, Deepak Singh and I extend upon a mapping between the cerebellum and Transformers to create a modified multi-layered perceptron that beats continual learning baselines.
Paper: https://t.co/pZijuZSYv8
Thread: 1/18
New preprint out! 💃
where we show that low-D neural subspaces are not all there is in large-scale neural data. How can we capture other types of computationally relevant structure?
With Arthur Pellegrino & Alex Cayco-Gajic.
https://t.co/ZKJBetyLxn
1/n