This is truly a must-read. Please read it, and once you have, bookmark it and revisit it often. Written by one of the smartest people I know, it offers powerful insights into the future ahead. All the more essential if you’re an investor.
🦔Starting October 5, you'll be able to trade futures on the price of AI computing power. CME, the big Chicago exchange, is launching contracts that track the hourly rental cost of Nvidia's H100 and B200 chips, the same way it runs futures on oil or wheat. In CME's own words, compute has become the currency of the AI age, and they compare it directly to how oil went from a raw material to a global trading market.
My Take
So now you can bet on the price of AI chips like they're pork bellies. I get why the hedging side exists, a company renting thousands of GPUs wants to lock in the cost, same as an airline does with fuel. Fair enough, that's a normal use for a futures market.
I have an issue with what usually comes after. Once a thing trades on an exchange, people bet on it and borrow against it. We just saw Nvidia turn its own chips into loan collateral and promise to cover their resale price, and now the rental cost becomes something traders can play. Every month there's a new way to package this boom into something tradable, and it's starting to rhyme with what they did to housing before 2008. I don't think this contract breaks anything by itself. But the more of the AI bet that gets wired into Wall Street, the more people go down with it if the thing ever cracks.
Hedgie🤗
Why would anyone pay SpaceX or Nebius $30-$50B/year/1GW of compute?
Because OpenAI and Anthropic can generate $100B+ per gigawatt per year selling inference API!
Here's how that's possible, and why it's sustainable (save this)
First, what are they actually selling? Every ChatGPT answer, every Cursor autocomplete, every enterprise copilot runs on "inference", the model generating tokens. The labs sell those tokens through subscriptions or an API, metered like electricity
@SemiAnalysis showed their model: run one gigawatt of Nvidia GB300 compute selling tokens at posted API prices and it generates over $100 BILLION a year of revenue. That same gigawatt costs roughly $12B-$50B/year to rent out
A 2-8x spread between what compute costs and what intelligence sells for
So why can they charge that much? Because the customer isn't comparing token prices to compute prices. They're comparing tokens to LABOR
A few dollars of tokens replaces work that costs hundreds of dollars an hour. Legal review, sales ops, financial close, code. That's why enterprise agent adoption is up 20x to 108x across job functions in just five months. At today's prices the buyer's ROI already fantastic
Why it's sustainable:
1. Demand compounds faster than prices fall. Token prices drop constantly, but agents burn dramatically more tokens per task than chatbots ever did, and every job function is adopting at once. Falling price x exploding volume = growing revenue
2. Supply is rationed. A handful of frontier labs, and none of them have enough compute. When you're capacity constrained you serve the highest-value demand first and pricing holds
3. The buyers keep paying UP, not down. Microsoft sells this same inference through Azure and Copilot. Nebius just disclosed its first deal at $40-50M per megawatt, the top of its own range. Nobody negotiates prices higher on a product that's about to be oversupplied
This is why the "AI capex bubble" framing keeps missing. The $100B at the top of the stack is what pays the $30-50B compute deals, which pay the datacenters, the chips, the memory, the power. The most profitable product in tech is funding everything below it
And you don't need to own the private labs to win. Every dollar of inference revenue flows down through the infra stack, and that's exactly where I'm positioned (compute, memory, power)
If this was helpful, my company provides a service where 5 top-tier analysts share their market analysis and real-time portfolios so you can see exactly how we're positioned across this stack. It's inside Milk Road PRO and just $1 to try (insane price just to check it out). Learn more here: https://t.co/o4jxfFDuMA
Follow me @kylereidhead for more insights on AI, robotics and markets!
Power is THE binding constraint.
Data centers are being shut down, GPUs are sold out, models are being commoditized and spot rates are rising all leads to power being critical. Not fanciful plans for power, future forecasts of BTM or distributed batteries blah blah blah but energized power today.
This means the following hierarchy is developing from greatest to least value:
1. Hyperscaler
2. Neocloud
3. Model maker
Ideally, you are 1+3 (Google, SpaceX, Meta) where you own massive power today and have a leading set of models to keep API pricing from 3rd parties honest enough to benefit them vs the model maker. But even if you are just (1), you can still extract great economics from (3) because owning the power is the leverage.
This means (2) needs to scale up fast. If Neoclouds do not scale up fast and move up the value stack towards hyperscalers (solely measured by energized compute online today) they are going to leave a lot of revenue on the table which will complicate their long term financing plans.
Also, starting now, a neocloud’s real competitors will be well capitalized frontier model companies who will do sweetheart deals with (1) and/or will vertically integrate and try to become (1). You can see this in the fact pattern (Ant+AWS, OAI+Stargate).
Get your hands on power.
It’s the spice.
Few words on $UBER:
It actually started to look like a no-brainer.
It’s currently at 15x 2027 earnings and 12x 2028 earnings while double digit annual growth expected through 2030.
So, the only reason it gets this discount is that the market doesn’t fully believe shareholders will really get the future cash flows. It’s concerned of potential disruption by robotaxis.
That won’t happen.
People always underestimate the tendency for aggregation.
Even if autonomous taxis become mainstream globally, it’ll be a pretty fragmented market with Waymo, Tesla, AVride, Zoox etc.
How many apps people are willing to download for mobility?
What the market misses is that fragmentation is not just a problem for consumers, it’s also a viability issue for providers.
We are looking at what’ll be a capex heavy business. Companies will need monopoly/oligopoly to deploy fleets globally, maintain and replace them regularly and still provide affordable rides to consumers. If this won’t happen, the business won’t be viable.
So, over time, we’ll see companies like Tesla and Waymo to position themselves as equipment providers (OEM) rather than service providers and platforms like $UBER will act as service providers.
Yes, $UBER could have had a faster pivot to robotaxis so far, but it is still the primary candidate to dominate the market and 15x 2027 earnings more than makes up for the execution risk.
They scale robotaxis in a few big cities and we’ll quickly see the stock above $100 again.
Memory margins are about to hit levels this industry has never seen and the ripple effects go way beyond Samsung, SK Hynix and Micron (Save this).
This chart shows the memory total addressable market exploding roughly 8x over three years, from $214 billion in 2025 to $896 billion in 2026, then $1.34 trillion in 2027, and $1.68 trillion by 2028.
Operating margins are expected to hold in the high 70s throughout that stretch, up from just 30% in 2025, meaning it's a structural reset in how profitable memory chips have become.
The reason for that margin explosion is simple.
AI driven demand for high bandwidth memory is consuming an outsized share of manufacturing capacity, since HBM eats up two to four times more wafer space than conventional DRAM for the same output and TrendForce projects HBM will absorb 30% of total DRAM wafer capacity by 2027, leaving standard DRAM chronically undersupplied.
Now here's who benefits beyond the memory makers themselves, starting with the equipment suppliers who build the machines memory chips are actually made on.
Lam Research is the clearest beneficiary, since memory has grown from about a third to 39% of its systems revenue in under a year and the company just raised its 2026 wafer fab equipment forecast to $140 billion industry wide, up from $135 billion, with management saying demand isn't the constraint anymore, cleanroom availability and installation capacity are.
Applied Materials and KLA Corp are right behind it, since Morgan Stanley raised its 2026 memory equipment spending forecast to $48.7 billion, nearly matching its most bullish prior case, and both companies got price target and rating upgrades specifically because DRAM capex plans are accelerating faster than expected.
GlobalWafers, the world's third largest silicon wafer supplier, just struck a 10 year supply agreement with Micron, with Micron providing $500 million in financing just to secure long term raw wafer supply, since even the base silicon that memory chips are built on is now something manufacturers have to lock up years in advance.
Beyond wafers, a handful of smaller specialty names sit further down the chain and tend to get overlooked entirely.
Entegris supplies the ultra pure chemicals, filtration systems, and specialty materials that go into every step of memory fabrication and it scales directly with wafer starts rather than any single chip type, making it a pure play beneficiary of higher fab utilization across the industry.
Advanced testing and packaging names like Amkor Technology and ASE Technology benefit too, since HBM's stacked chip design requires far more sophisticated testing and packaging steps than conventional DRAM and that packaging bottleneck is becoming almost as tight as the wafer bottleneck itself.
As manufacturers race to expand HBM production, demand flows upstream to equipment makers, wafer suppliers, materials companies, and advanced packaging firms and that's why the memory trade extends far beyond Samsung, SK Hynix, and Micron.
I'm tracking every layer of the memory supply chain because that's where I think the biggest opportunities are, make sure to follow @MelvinInvests for more semiconductor insights and if you want to see exactly what I'm buying as an analyst at Milk Road Pro, you can check out the link below for more.
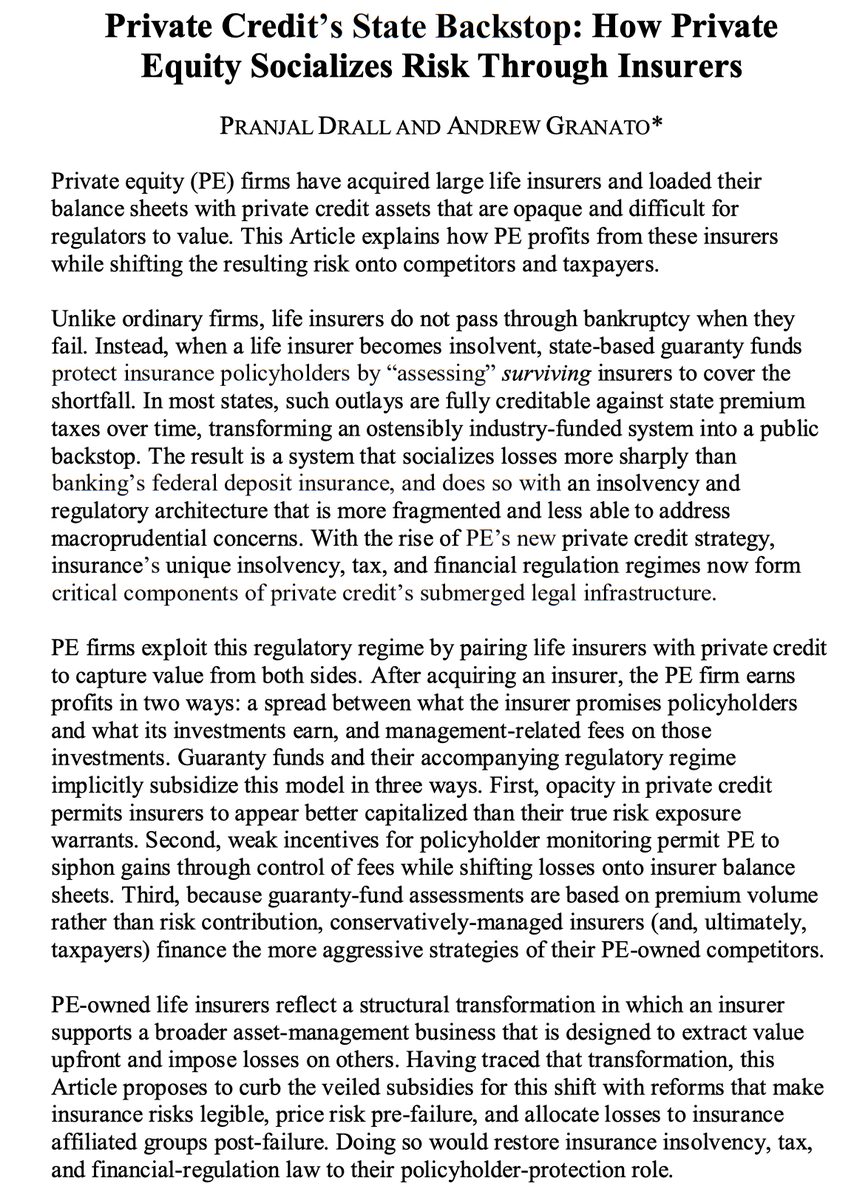
New w/ @PranjalDrall: Private Credit's State Backstop: How Private Equity Socializes Risk Through Insurers. It's about how insurance insolvency, tax, and financial-regulation law have subsidized PE's takeover of life insurance and become the submerged law of private credit.
I am getting really bullish on the big three cloud businesses $AMZN $MSFT and $GOOG.
1. Software is going to become 99% cheaper to make.
2. Thus, there will be way more software. More niche software for ever more specific uses.
3. And thus, there will be way more software companies / companies that built their own in house software.
4. Software companies are going to be smaller than before.
5. Thus, they won't ever have the scale to launch their own in house, global cloud hardware.
6. Because they are smaller. they will have less negotiating leverage with the giant cloud providers.
7. They will also be more sticky, since small companies have a relatively higher switching cost.
8. Companies are going to prioritize not giving away their work flows and unique data to the AI model companies. The giant cloud companies can operate as a sort of firewall for them, once they develop the process/technology ($MSFT's CEO is talking about this already).
Many asking what blockchain they are using, here is the answer: The digital conversions occurred on HyperLedger Besu (DTCC’s private network) and Canton (a public network). This is part of DTCC's multi-chain strategy to ensure resiliency, scalability and choice.
Our recent AI Value Capture piece tries to answer the question we get asked more than any other in calls with allocators: who is actually keeping the margin in this cycle, now that the easy infrastructure trade has been priced in? (1/4)🧵
This is a thoughtful framing from @GavinSBaker , and directionally I agree that cheaper models should increase intelligence / dollar, stimulate demand, Jevon’s etc (AI infra bull here, duh). I just think it is too early to make the either/or calls generally in AI and especially at the model layer.
Even assuming very little capability differentiation, **the low-cost provider only sets the industry price if it has enough capacity to clear the market**. If cheap supply is capacity-constrained, it sells out and demand spills into progressively higher-cost supply. The marginal producer (NOT the low cost producer) sets the clearing price. If we are going to treat intelligence like a commodity then we have to use commodity market dynamics to understand pricing…
In that world, Meta or Grok’s cost advantage becomes “scarcity rent”. They can price JUST BELOW the next-best alternative rather than anywhere near their own marginal cost. This is important: *Cheap intelligence only lowers the market-clearing price once cheap capacity becomes abundant enough to satisfy the marginal buyer*. Read it twice ;)
And, as I’ve said in the past, right now the easier AI bet may be that realized supply disappoints (supply curve shifts down). Datacenters are harder to build / energize / deploy than people think, and it's only getting harder, while cheaper intelligence / innovation IS creating more demand (the innovation-demand fly wheel is spinning pretty fast right now on a fraction of the GWs we hope to build).
So yes, this could ultimately redistribute model-layer margins toward infrastructure. BUT before getting there, we may spend a LONG TIME in a world where cheap providers sell out, more expensive providers absorb the overflow, and everyone keeps building. Now back to praying to the momentum gods :). Godspeed.
100x. That is the memory multiplier Dylan Patel @dylan522p says reasoning models just unleashed.
Patel flagged this in a December 2024 note the week O1 shipped. Chat models ran ~1,000-token contexts. Reasoning models like O1, Claude thinking, and DeepSeek R1 generate 100,000-token internal chains before answering.
The KV cache - the memory that holds every token relationship in context - scales with context length, not compute. So memory demand jumps 100x even when the compute barely moves.
Andrej Karpathy @karpathy has made the same point that inference-time reasoning is the new axis of scaling.
Every reasoning deployment is a memory multiplier. That is the demand engine under $MU and SK Hynix that a capex-only model misses.
Why the shift from chat to reasoning is a multi-year tailwind: https://t.co/iUYMxAAmfh
Source: The Next Big Thing - https://t.co/1PWkRXWSUi
Jensen wouldn't change how Nvidia reports its revenue if he weren't forecasting a slowdown in Hyperscale capex. This is a reason behind everything that Nvidia does, and there's a lot going on behind the scenes.
We’ve had every major open source models provider and CSP reach out to 8090 since the post below.
We will run a massive recursive optimization with the major open weight models (Chinese) AND American Open Source - starting with Nvidia’s Nemotron - and will publish the results.
I think you will see, unambiguously, that a 3rd party control plane (like 8090’s Software Factory) + open weight/open source + leading CSP is much cheaper and much more strategically protective than using a closed model directly.